This is the full developer documentation for Masthead Data
# What's Masthead Data?
Masthead is an end-to-end data reliability solution for Google Cloud users that monitors data pipelines and data products in Google BigQuery.
## Why Masthead?
[Section titled “Why Masthead?”](#why-masthead)
Masthead automates checks for table health and pipeline health out of the box for the entire warehouse at scale without ever reading clients’ data. Masthead processes logs and metadata to deliver any issues with freshness, volume, schema changes, or pipeline errors. You don’t have to go through logs to debug it anymore, Masthead surfaces and alerts about any malfunction in Google Cloud Project.
The goal is to build a platform for data engineers to stay informed when pipelines or data fail.
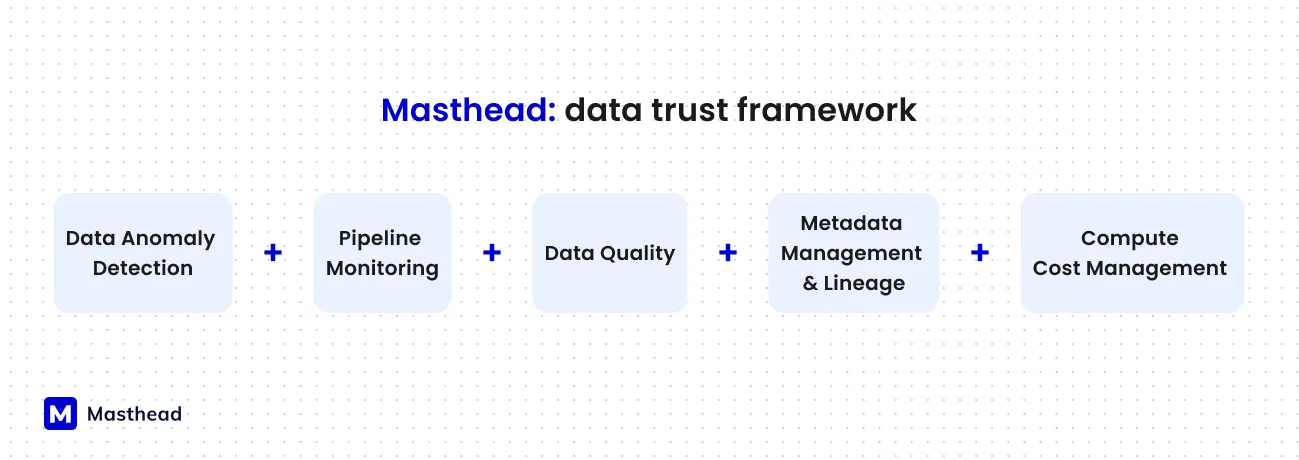
Masthead data trust framework
### Metadata management & lineage
[Section titled “Metadata management & lineage”](#metadata-management--lineage)
In today’s complex data environments, effective metadata management is essential for searching and accessing necessary data or products. Masthead enhances this process with a column-level lineage data dictionary for Google BigQuery and Looker, improving data discoverability and accessibility within organizations.
The platform enables efficient navigation and search through large datasets for relevant information, while also facilitating quicker root cause analysis of issues in pipelines or data.
### Data anomaly detection
[Section titled “Data anomaly detection”](#data-anomaly-detection)
Systems break, and so does data. Having a system that monitors each time-series table, every pipeline, and every model running in data environment ensures comprehensive visibility across the entire system at scale. Imagine managing 15,000 tables, views, and external tables in Google BigQuery as a part of everyday data warehouse scaling.
By utilizing logs, Masthead provides insights into freshness, volume, and schema changes for every table within Google BigQuery, and Google Cloud Project acting like a cardiogram for the platform.
### Pipeline and model observability
[Section titled “Pipeline and model observability”](#pipeline-and-model-observability)
Pipelines and models often fail due to various reasons such as inappropriate setup, retry errors, SQL errors, permission issues, among others. The challenge lies in identifying when and what’s failing, as well as who can rectify it. With the multitude of solutions that data engineers use today for data ingestion, transformation, and distribution, achieving observability across the entire ecosystem has become increasingly difficult.
Masthead provides observability for pipelines and models without requiring integration with any ETL or data modeling tools. It alerts data teams about any pipeline or system failures in real-time, within 15 minutes after deploying Masthead, ensuring that every job runs as expected.
### Data quality
[Section titled “Data quality”](#data-quality)
Crucial business metrics require constant monitoring, such as active users per app version and the length of strings for hashed credit card numbers. Because every business has unique metrics and use cases, you can monitor them by setting store rules. However, the challenge arises in enabling this monitoring without compromising data privacy by exposing sensitive business information to third parties.
Masthead prioritizes client data privacy and security, utilizing Google Cloud Dataplex to create and implement rules-based checks without ever accessing client data.
### Cost management
[Section titled “Cost management”](#cost-management)
Managing cloud costs has become a top priority for businesses increasingly reliant on cloud services, yet many still struggle to manage their costs effectively. Data teams frequently run experiments that impact both compute and storage costs.
Masthead provides detailed cost analyses for every running pipeline and table stored. This enables a precise understanding of the costs associated with your data products or technologies in your Google BigQuery environment, such as dbt, Looker, and Fivetran. As a result, teams can quickly identify and eliminate orphan processes, instantly reducing compute costs, and accurately attribute the cost of delivering any data products.
# Overview
Masthead’s cost recommendations identify actionable optimizations to improve cloud spend and ROI for data products.
Note
The costs in Masthead are estimates based on the workload information and closely represent the Google Cloud billing trends. Neither costs nor savings include any personalized credits or discounts.
Cost optimizations help you compare and prioritize cost saving recommendations.
Masthead focuses on Compute and Storage cost analysis and optimization:
* [Compute costs](/cost-insights/compute-costs)
* [Storage costs](/cost-insights/storage-costs)
# Compute Costs
Masthead analyzes BigQuery compute resource consumption and provides recommendations based on the pipelines and resource usage patterns. These recommendations help leverage the most cost-effective [BigQuery compute models](https://cloud.google.com/bigquery/docs/editions-intro#editions_features).
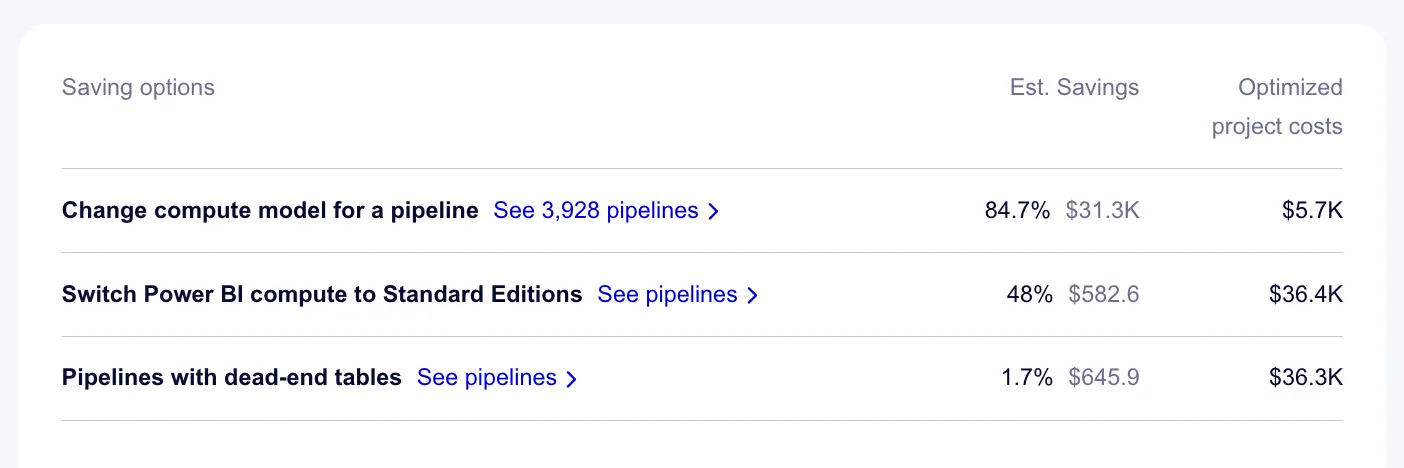
Saving options on Compute Cost Insights page
## Compute workload simulation
[Section titled “Compute workload simulation”](#compute-workload-simulation)
Switching BigQuery workloads between On-Demand billing and BigQuery Editions—or reconfiguring reservation slot pools—offers significant cost savings. However, migrating workloads without validating capacity requirements can lead to query queuing, SLA degradation, or unexpected costs.
To eliminate this uncertainty, Masthead runs discrete-event workload simulations using your historical query logs. The simulation models how queries would perform under virtual BigQuery capacity with varying editions and autoscaling boundaries before you apply any configuration changes.
### Simulation inputs
[Section titled “Simulation inputs”](#simulation-inputs)
The simulation engine evaluates several dimensions of your historical BigQuery workload:
* **Historical query execution telemetry**: Analyzes query execution logs over a 30-day evaluation window, capturing slot millisecond consumption (`slot_ms`), execution start and end timestamps, run durations, and concurrency peaks.
* **Workload taxonomy**: Categorizes jobs into logical workload groups, including DAG models (individual dbt models and Dataform actions), scheduled pipeline jobs, projects, and IAM principals (user or service accounts).
* **Target compute configurations**: Evaluates candidate BigQuery editions (Standard, Enterprise, and Enterprise Plus), regional pricing, and slot configurations ranging from baseline allocations to dynamic autoscaling limits (`autoscale_max_slots`).
* **Feature compatibility checks**: Verifies that queries within a candidate workload don’t rely on features restricted by specific editions (such as customer-managed encryption keys, BI Engine, or continuous queries) to ensure seamless execution upon migration.
### How the simulation evaluates workloads
[Section titled “How the simulation evaluates workloads”](#how-the-simulation-evaluates-workloads)
Masthead reconstructs your workload timeline down to the second, simulating real-world execution conditions:
1. **Timeline replay**: Replays past queries against a virtual reservation capacity pool.
2. **Concurrency and slot distribution**: Models BigQuery’s fair-share slot scheduling and autoscaling behavior to distribute available slots among active jobs.
3. **Queue and latency tracking**: Detects whether high concurrency periods exceed available slots, queues, and execution duration changes.
### Simulation outputs and recommendations
[Section titled “Simulation outputs and recommendations”](#simulation-outputs-and-recommendations)
The simulation generates actionable insights and sizing metrics to help you make informed decisions:
* **Cost comparison and projected savings**: Compares your actual 30-day compute expenditure against the simulated cost under the recommended compute model, quantifying net monthly savings.
* **Recommended reservation capacity**: Suggests the optimal autoscaling maximum slot size (`autoscale_max_slots`) and baseline slot allocation to maximize cost efficiency while keeping query latency within acceptable thresholds.
* **Performance impact estimates**: Provides expected duration percentiles (such as P95 execution duration) and peak queue statistics, confirming that performance remains stable under the recommended reservation size.
* **Actionable implementation plan**: Generates ready-to-apply configuration details, including SQL DDL statements to create or modify reservations, and tool-specific routing configurations (`RESERVATION_CONFIG` for dbt and Dataform, or principal assignment rules).
## Recommendations
[Section titled “Recommendations”](#recommendations)
### Alternative compute models
[Section titled “Alternative compute models”](#alternative-compute-models)
Masthead analyzes BigQuery compute resource consumption and provides recommendations for the most cost-effective [BigQuery compute models](https://cloud.google.com/bigquery/docs/editions-intro#editions_features).
See [Reservation Assignments](/cost-insights/compute-costs/reservation-assignments) for detailed guidance.
### Pipelines with dead-end downstream
[Section titled “Pipelines with dead-end downstream”](#pipelines-with-dead-end-downstream)
Masthead identifies and tags tables with no downstream consumption as [Dead-End Tables](/cost-insights/storage-costs#dead-end-tables). This allows you to identify running upstream pipelines that *only* produce these tables. Review and reclaim resources by switching off such pipelines.
**Recommendation:**
1. Check recommendations for pipelines with dead-end tables on [Costs Insights](https://app.mastheadata.com/pipelines?costEfficiency=DEAD_END\&tab=Costs+insights\&tableAlertType=\&pipelineType=) page:

Pipelines with dead-end tables
2. Verify the tables have no consumers downstream on the [Dictionary](https://app.mastheadata.com/dictionary?tab=Tables) and [Lineage](https://app.mastheadata.com/lineage) pages.
3. Adjust or turn off upstream pipelines to reduce unnecessary compute spend.
# Dataform Reservations
Page Moved
This page redirects to [Reservation Assignments](/cost-insights/compute-costs/reservation-assignments).
For detailed Dataform package documentation, see the [dataform-package GitHub repository](https://github.com/masthead-data/dataform-package).
# DBT Reservations
Page Moved
This page redirects to [Reservation Assignments](/cost-insights/compute-costs/reservation-assignments).
For detailed dbt package documentation, see the [dbt-reservations GitHub repository](https://github.com/masthead-data/dbt-reservations).
# Reservation Assignments
BigQuery offers different compute models that impact access to various compute features and directly affect costs. Masthead analyzes usage to determine the optimal model among On-demand, Standard, and Enterprise editions.
You can configure reservation assignments at different levels:
* **On-demand**: Billed per data processed. This is the default.
* **Project-level assignment**: Billing project [assigned to a reservation](https://cloud.google.com/bigquery/docs/reservations-assignments#assign_my_prod_project_to_prod_reservation)
* **Query-level assignment**: Query with [specific reservation](https://cloud.google.com/bigquery/docs/reservations-assignments#reservation). This overrides project settings.
These levels provide flexibility to optimize compute models across your workloads. Read more about [combining different compute billing models](https://cloud.google.com/bigquery/docs/reservations-workload-management#combine_reservations_with_on-demand_billing).
## Reservation assignment levels
[Section titled “Reservation assignment levels”](#reservation-assignment-levels)
Masthead provides recommendations to optimize compute costs through reservation assignments at multiple levels:
* **Project-level**: All workloads in a project use assigned reservations
* **Principal-level**: Specific service accounts or user identities assigned to dedicated reservations or routed to on-demand
* **DAG node-level**: Flexible assignment for individual dbt or Dataform models
* **Pipeline-level**: Individual pipelines assigned to specific reservations
Before applying changes, Masthead ensures your workloads are compatible with the target compute model and suggests the reservation capacity adjustments.
Creating or adjusting a reservation for the migrated workload
1. If you didn’t have a reservation, create one in the BigQuery administration project:
```sql
CREATE RESERVATION `{BQ_ADMIN_PROJECT}.region-{region_id}.{RESERVATION_ID}` OPTIONS (
edition = STANDARD,
slot_capacity = 0,
autoscale_max_slots = {estimated_slot_capacity}
);
```
If your current workload already uses reservations, you’ll need to adjust the reservation capacity as shown in the preceding code block to increase or decrease the capacity for an existing reservation.
### Project-level reservation assignment
[Section titled “Project-level reservation assignment”](#project-level-reservation-assignment)
Masthead analyzes and aggregates all compute workload running within a project to recommend the most cost-effective compute model. Masthead considers overall project usage patterns and potential savings when switching between On-Demand and Editions models with project-level reservation assignments.
### Principal-level reservation assignment
[Section titled “Principal-level reservation assignment”](#principal-level-reservation-assignment)
When multiple services, applications, and teams share a single BigQuery project, assigning the entire project to an Edition can be suboptimal. Interactive users might experience slot queuing during large batch transformations, or lightweight SQL queries might incur unnecessary reservation autoscale costs.
Masthead analyzes compute usage by caller identity to identify service accounts (such as ETL workers or BI connectors) and user identities that run consistent, compute-heavy jobs. By assigning these specific principals to dedicated reservations or explicitly routing them back to On-Demand you can isolate compute workloads without restructuring projects or rewriting pipelines.
#### Prerequisites
[Section titled “Prerequisites”](#prerequisites)
Before assigning a principal to a reservation, ensure the identity has permission to use the reservation (`bigquery.reservations.use`). Grant the `roles/bigquery.resourceEditor` or `roles/bigquery.user` role to the target principal on the reservation resource in your BigQuery administration project.
#### Implementation methods
[Section titled “Implementation methods”](#implementation-methods)
* BigQuery SQL DDL
BigQuery natively supports managing principal assignments using SQL DDL statements executed in the administration project.
**Assign a principal to a reservation:**
```sql
CREATE ASSIGNMENT `{BQ_ADMIN_PROJECT}.region-{region_id}.{RESERVATION_ID}.{ASSIGNMENT_NAME}`
OPTIONS (
assignee = 'projects/{SOURCE_PROJECT_ID}',
job_type = 'QUERY',
principal = 'principal://iam.googleapis.com/projects/-/serviceAccounts/{SERVICE_ACCOUNT_EMAIL}'
);
```
Note
For the `principal` and `job_type` formats please refer to [BigQuery documentation](https://docs.cloud.google.com/bigquery/docs/reservations-assignments#user-specific_assignments).
**Route a principal to on-demand compute:**
To ensure a specific principal bypasses project-level reservations and uses on-demand billing, assign the principal to `none`:
```sql
CREATE ASSIGNMENT `{BQ_ADMIN_PROJECT}.region-{region_id}.none.{ASSIGNMENT_NAME}`
OPTIONS (
assignee = 'projects/{SOURCE_PROJECT_ID}',
job_type = 'QUERY',
principal = 'principal://iam.googleapis.com/projects/-/serviceAccounts/{SERVICE_ACCOUNT_EMAIL}'
);
```
* gcloud & bq CLI
You can also manage principal reservation assignments using the `bq` command-line tool:
**Create a principal assignment:**
```bash
bq mk --reservation_assignment \
--project_id={BQ_ADMIN_PROJECT} \
--location={region_id} \
--reservation_id={RESERVATION_ID} \
--job_type=QUERY \
--assignee_type=PROJECT \
--assignee_id={SOURCE_PROJECT_ID} \
--principal="principal://iam.googleapis.com/projects/-/serviceAccounts/{SERVICE_ACCOUNT_EMAIL}"
```
### DAG node-level reservation assignment
[Section titled “DAG node-level reservation assignment”](#dag-node-level-reservation-assignment)
[Flexible reservation assignment](https://docs.cloud.google.com/bigquery/docs/reservations-workload-management#flexible) at the DAG node level delivers significant savings with minimal effort. Masthead provides packages for common orchestration technologies to assign reservations to individual models.
#### How Masthead recommendations work
[Section titled “How Masthead recommendations work”](#how-masthead-recommendations-work)
Masthead analyzes your workload and provides intelligent categorization for each model/action:
* **Editions**: Large data volume operations requiring consistent compute
* **On-Demand**: Computation-intensive operations with variable resource needs
Masthead bases recommendations on:
* **Usage Patterns**: Historical query performance and frequency
* **Cost Analysis**: BigQuery slot usage and billing data
* **Resource Availability**: Current reservation capacity and utilization
You can review recommendations manually in [Compute Cost Insights](https://app.mastheadata.com/costs?tab=Compute+costs) or automate the process using [programmatic insights access](/developer/api). To learn how Masthead models workload capacity, queue depths, and projected savings before making recommendations, see [Compute workload simulation](/cost-insights/compute-costs#compute-workload-simulation).
#### Implementation by orchestration tool
[Section titled “Implementation by orchestration tool”](#implementation-by-orchestration-tool)
* dbt
**Prerequisites:**
Enable dbt job labels to track compute usage per model. Add to your `dbt_project.yml`:
```yml
query-comment:
job-label: True
```
**Quick Start:**
1. Add the package to `packages.yml`:
```yaml
packages:
- package: masthead-data/bq_reservations
version: 0.0.2 # Use the latest version
```
1. Install: `dbt deps`
2. Add to your model:
```sql
{{
config(
materialized='table',
sql_header=bq_reservations.assign_from_config()
)
}}
SELECT * FROM {{ ref('source_table') }}
```
1. Configure reservations using the `RESERVATION_CONFIG` variable based on Masthead recommendations
For detailed instructions, configuration examples, and troubleshooting, see the [dbt-reservations GitHub repository](https://github.com/masthead-data/dbt-reservations).
* Dataform
Assign reservations at the Dataform action level using the Masthead Dataform package.
**Quick Start:**
Install the package and configure reservation assignments based on Masthead recommendations provided in the `RESERVATION_CONFIG` object.
For detailed instructions, configuration examples, and troubleshooting, see the [dataform-package GitHub repository](https://github.com/masthead-data/dataform-package).
* Airflow
**Prerequisites:**
Ensure your Airflow DAGs use BigQuery operator labels to track compute usage. Airflow’s BigQuery operators automatically add default labels when properly configured.
**Quick Start:**
Override reservation assignments at the query level using BigQuery’s `SET @@reservation` statement:
```python
reservation_id = 'RESERVATION_ID'
sql_with_overridden_reservation = f"""SET @@reservation='{reservation_id}';
{your_sql}
"""
BigQueryInsertJobOperator(
task_id="run_query",
configuration={
"query": {
"query": sql_with_overridden_reservation
}
},
...
)
```
For more advanced usage, configuration patterns, and examples, see the [airflow-reservations GitHub repository](https://github.com/masthead-data/airflow-reservations).
#### Monitoring and optimization
[Section titled “Monitoring and optimization”](#monitoring-and-optimization)
To ensure optimal performance across all orchestration tools:
* **Monitor performance**: Track BigQuery job execution and costs in real-time
* **Review assignments**: Regularly check model/action assignments in [Compute Cost Insights](https://app.mastheadata.com/costs?tab=Compute+costs)
* **Adjust allocations**: Fine-tune reservation assignments based on usage patterns and cost analysis
* **Get support**: Contact Masthead support for configuration optimization assistance
### Pipeline-level reservation assignment
[Section titled “Pipeline-level reservation assignment”](#pipeline-level-reservation-assignment)
Masthead provides a granular view of compute costs, grouped by pipeline. This enables optimization through pipeline-level reservation assignments, migrating pipelines between BigQuery Editions and On-Demand models based on slot-consumption and usage patterns.
**Recommendation:**
Review pipeline-specific recommendations on [Compute Cost Insights](https://app.mastheadata.com/costs?tab=Compute+costs) page. It shows current and alternative costs achievable by switching the compute model for each pipeline.

Alternative model plan for a pipeline
# Storage Costs
Masthead collects and analyzes BigQuery resource metadata and usage logs to estimate the cost for the data assets and shows the recommendations to optimize the spending.
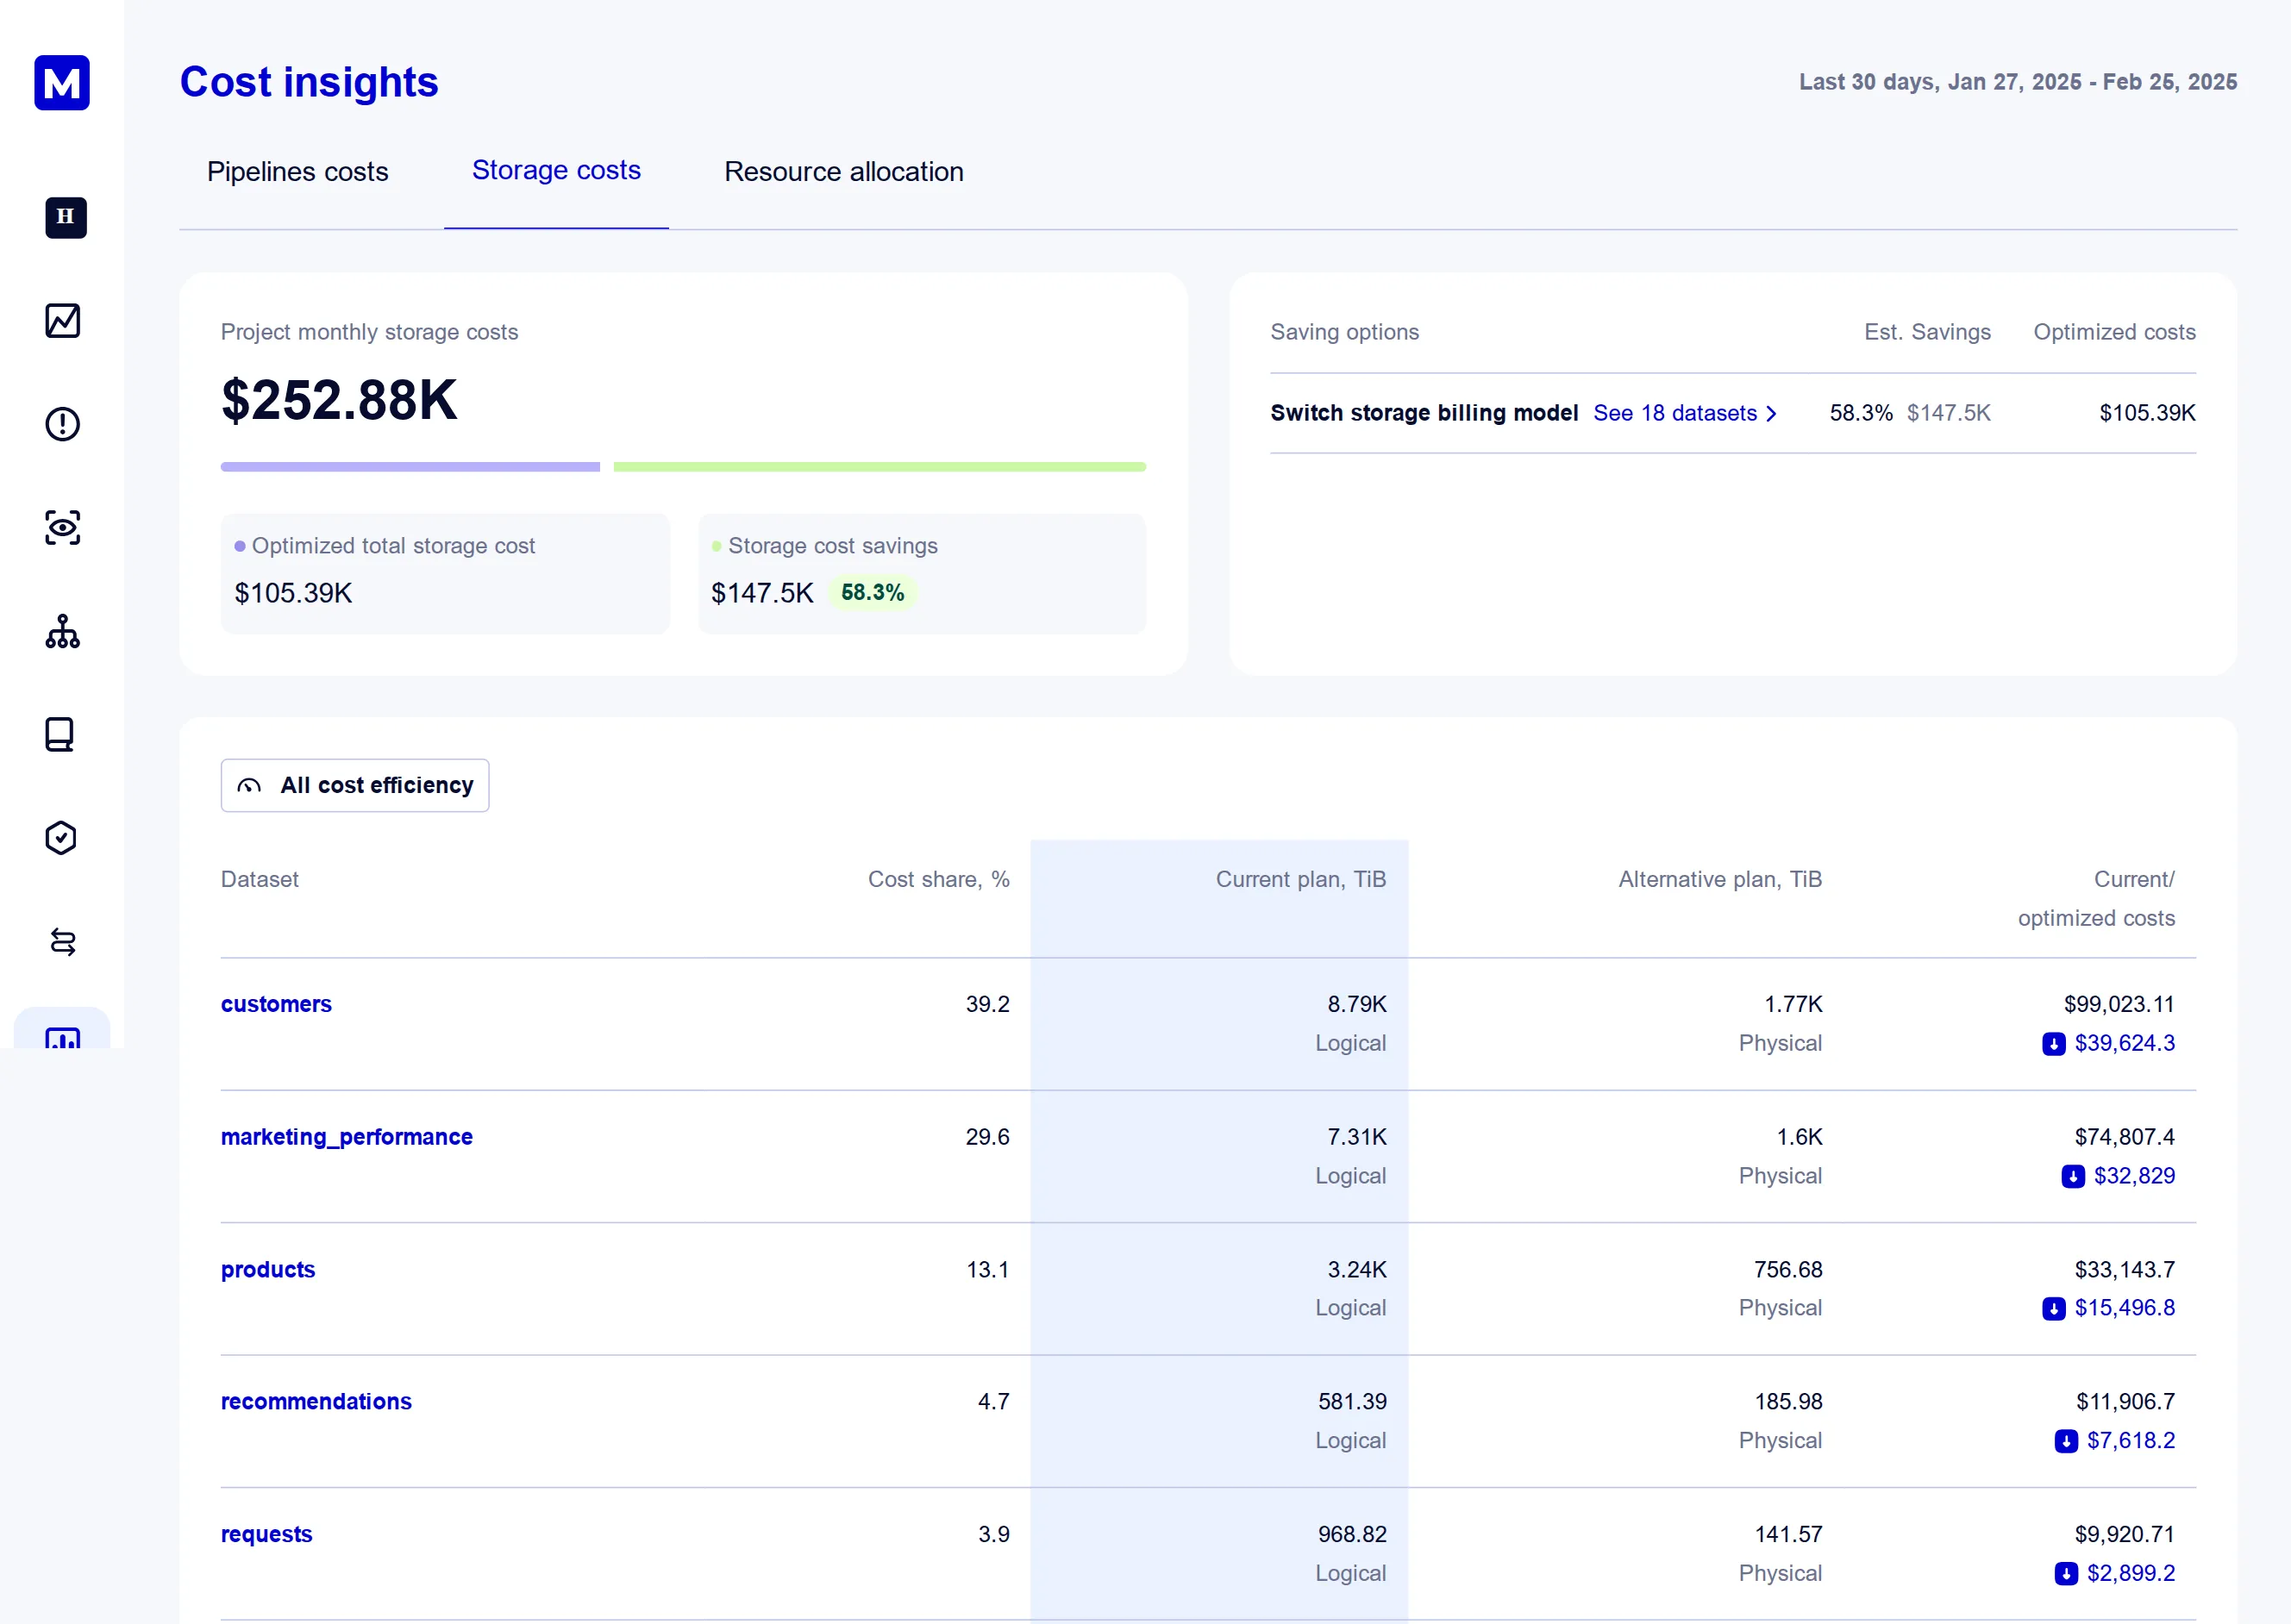
Storage costs insights and saving recommendations
[Storage Cost Insights](https://app.mastheadata.com/costs?tab=Storage+costs) page shows the details of the aggregated estimated metrics per dataset:
* storage size - most recent data point,
* storage cost - estimation based on the data storage usage over the last 30 days.
Masthead analyses each of these parameters and offers a set of recommendations optimizing the total storage bill.
## Recommendations
[Section titled “Recommendations”](#recommendations)
### Alternative storage billing model for dataset
[Section titled “Alternative storage billing model for dataset”](#alternative-storage-billing-model-for-dataset)
BigQuery provides logical and physical storage billing models. These models offer the flexibility to select costs based on data properties and operation patterns. Masthead analyzes dataset metadata and storage usage to estimate the optimal cost for each billing model.
Google Cloud Billing calculates the storage cost in the following way:
* logical storage cost:
```text
active_logical_storage_size * active_logical_storage_price + long_term_logical_storage_size * long_term_logical_storage_price
```
* or physical storage cost:
```text
(active_physical_storage_size + time_travel_physical_storage_size + fail_safe_physical_storage_size) * active_physical_storage_price + long_term_physical_storage_size * long_term_physical_storage_price
```
Masthead analyzes your data storage usage retrospectively and, using information about the alternative costs of each billing model, creates a recommendation for opportunities where the switch provides a consistent and confident saving outcome.
#### Recommendation
[Section titled “Recommendation”](#recommendation)
1. Review storage billing recommendations for the datasets on [Storage Cost Insights](https://app.mastheadata.com/costs?tab=Storage+costs\&storageCostsEfficiency=ALTERNATIVE_PLAN) page.
2. [Update storage billing model for a dataset](https://cloud.google.com/bigquery/docs/updating-datasets#update_storage_billing_models) to the recommended storage billing model.
You can adjust the dataset configuration by running a DDL statement:
```sql
ALTER SCHEMA PROJECT.DATASET SET OPTIONS(
storage_billing_model = LOGICAL or PHYSICAL
);
```
Run optimizations using a notebook
Use [a notebook example](https://github.com/masthead-data/templates/blob/main/notebooks/optimize_storage_billing_model.ipynb) to apply recommendations across all your datasets.
Note
This dataset configuration has no impact on data processing performance.
When you change a dataset’s billing model, it takes 24 hours for the change to take effect. Once you change a dataset’s storage billing model, you must wait 14 days before you can change the storage billing model again.
### Dead-end tables
[Section titled “Dead-end tables”](#dead-end-tables)
Caution
Please verify that you’re using [the Masthead agent version v0.2.7+](/get-started/integrate-using-iac) to get the accurate lineage and insights. Earlier versions of the agent didn’t have access to [Storage API](https://docs.cloud.google.com/bigquery/docs/reference/storage) data consumption operations.
By analyzing BigQuery lineage end-to-end Masthead identifies the tables that are being regularly updated, but have no downstream consumption.
Masthead applies the `Dead-end` label to the following resources:
* Regularly updated tables that have had no downstream consumption during the last 30 days, which is the default period.
* Pipelines that update them. For details, see [Dead-end pipelines](/cost-insights/compute-costs#pipelines-with-dead-end-downstream).
* other upstream tables and pipelines that contribute solely to this process.
You can explore complete lineage with `Dead-end` labels by opening a Lineage page for a corresponding table or pipeline.
Run optimizations using a notebook
Use [this notebook example](https://github.com/masthead-data/templates/blob/main/notebooks/save_on_unused_storage.ipynb) to apply recommendations across all your tables.
#### Recommendation
[Section titled “Recommendation”](#recommendation-1)
1. Review the tables labeled as `Dead-end`. The [Dictionary](https://app.mastheadata.com/dictionary?tab=Tables\&deadEnd=true) page lists all dead-end tables.
2. Optimize the table updates to resemble the data consumption requirements.
3. Delete the tables when there are no clear consumers for the data.
### Unused tables
[Section titled “Unused tables”](#unused-tables)
Masthead helps you track the costs of data assets that aren’t in active use by labeling those tables as `Unused`. Based on your lineage, these tables have had no upstream or downstream consumption for 30 days, which is the default period.
#### Recommendation
[Section titled “Recommendation”](#recommendation-2)
1. Review the tables labeled as `Unused`. The [Dictionary](https://app.mastheadata.com/dictionary?tab=Tables\&deadEnd=true) page lists all unused tables.
2. Delete unused tables to save on storage costs.
# AI agent skills
> Reference guide for pre-built AI agent skills to automate data quality and cost optimization workflows.
Masthead provides a collection of pre-built AI agent skills that allow agents, such as Google Antigravity or Claude Code, to analyze and triage issues programmatically. These skills help agents interpret BigQuery dataset schemas, lineage information, and cost optimization recommendations more efficiently.
All skills are available in the [for-agents GitHub repository](https://github.com/masthead-data/for-agents/) and ship as one plugin, `masthead-agent-tools`, for Claude Code, OpenAI Codex, and Google Antigravity. The plugin bundles the skills, two workflow commands, and the Masthead MCP server connection.
***
## Installation
[Section titled “Installation”](#installation)
Install the plugin in your coding agent, restart it, then sign in to the `masthead` MCP server once. The [repository README](https://github.com/masthead-data/for-agents/blob/main/README.md) is the source of truth for these steps; the **Agent tools** button in the Masthead app copies a setup prompt that walks your agent through them.
| Client | Install | MCP sign-in |
| ------------------ | ------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------ |
| Claude Code | `/plugin marketplace add masthead-data/for-agents` then `/plugin install masthead-agent-tools@masthead-data` | `/mcp`, authenticate `masthead` |
| OpenAI Codex | `codex plugin marketplace add masthead-data/for-agents` then `codex plugin add masthead-agent-tools@masthead-data` | `codex mcp login masthead` |
| Google Antigravity | Clone the repository into `.agents/plugins/masthead-agent-tools` or `~/.gemini/config/plugins/masthead-agent-tools` | Agent Settings, Customizations, `masthead`, **Authenticate** |
Plugins load at startup, so restart the client after installing. A `401 Unauthorized` from any Masthead tool means the sign-in step is still missing.
### Workflow commands
[Section titled “Workflow commands”](#workflow-commands)
| Workflow | Claude Code | Codex | Antigravity |
| ------------------------------------------------------------------------------------------------- | ------------------------------- | ---------------------------------------- | ------------------- |
| Incident triage: open incidents, lineage, blast radius, mitigation plan | `/masthead-agent-tools:triage` | `$masthead-agent-tools:masthead-triage` | `/masthead-triage` |
| FinOps audit: dead-end and unused tables, dataset billing models, pipelines, workload assignments | `/masthead-agent-tools:savings` | `$masthead-agent-tools:masthead-savings` | `/masthead-savings` |
Both accept an optional scope, for example `... savings tables in project my-project` or `... triage incident `.
The FinOps skills read the `insights` table from your Masthead BigQuery export. They resolve the dataset through the [`get_tenant_settings`](/developer/mcp/tools#get_tenant_settings) MCP tool and stop with a link to [request access](/developer/api#set-up-access) if the export isn’t enabled for your tenant. The incident triaging skill needs only the MCP server.
***
## Observability and incident management
[Section titled “Observability and incident management”](#observability-and-incident-management)
### Incident triaging skill
[Section titled “Incident triaging skill”](#incident-triaging-skill)
Triage, analyze downstream impact, and mitigate data quality and pipeline incidents using the Masthead MCP server.
* **Associated resources**: Masthead MCP server tools, including incidents and project metadata
* **Skill definition**: [masthead-incident-triaging](https://github.com/masthead-data/for-agents/blob/main/skills/masthead-incident-triaging/SKILL.md)
### Asset prioritization skill
[Section titled “Asset prioritization skill”](#asset-prioritization-skill)
Suggest which tables and BI assets (Looker dashboards and looks, Looker Studio reports, Google Sheets) to raise to PRIORITY or CRITICAL monitoring, or lower back to REGULAR, from Masthead asset scores, with a reason per asset taken from the score metrics, and apply the change on confirmation.
* **Associated resources**: Masthead MCP server tools `list_asset_scores`, `update_table_priority`, and `update_bi_asset_priority`
* **Skill definition**: [masthead-asset-prioritization](https://github.com/masthead-data/for-agents/blob/main/skills/masthead-asset-prioritization/SKILL.md)
The in-app prompt runs this skill in recommendation mode; apply tier changes only after confirming in your agent session.
### Data scans skill
[Section titled “Data scans skill”](#data-scans-skill)
Set up a data scan end to end: define a metric with your agent, publish it as a BigQuery table in a `masthead_dq` dataset with a scheduled query that keeps it current, grant Masthead read access to that dataset only, then validate and create the scan. The skill also lists, pauses, updates, and deletes existing data scans, and it runs every BigQuery change and every scan change only after you confirm it.
* **Associated resources**: Masthead MCP server tools `list_data_scans`, `create_data_scan`, `update_data_scan`, and `delete_data_scan`, the `bq` CLI, and BigQuery scheduled queries
* **Skill definition**: [masthead-data-scans](https://github.com/masthead-data/for-agents/blob/main/skills/masthead-data-scans/SKILL.md)
***
## Cost optimization
[Section titled “Cost optimization”](#cost-optimization)
These skills help AI agents interpret the `insights` table to recommend cost-saving operations across workload assignments, pipelines, datasets, and tables. They never execute a change: the agent prepares commands and a review list for you to run.
### Compute savings with workload assignments
[Section titled “Compute savings with workload assignments”](#compute-savings-with-workload-assignments)
Optimize BigQuery compute costs by assigning data models (Dataform, dbt, Airflow) and principals (service accounts, users) to slot reservations or on-demand compute based on Masthead recommendations.
* **Associated resources**: The `insights` table in the Masthead BigQuery dataset, specifically compute recommendations of type `Compute costs` for data models and principals
* **Skill definition**: [masthead-compute-savings-with-workload-assignments](https://github.com/masthead-data/for-agents/blob/main/skills/masthead-compute-savings-with-workload-assignments/SKILL.md)
### Compute savings with pipelines
[Section titled “Compute savings with pipelines”](#compute-savings-with-pipelines)
Optimize BigQuery compute costs by identifying and pausing/disabling unused, dead-end, or inefficient pipelines that consume compute resources.
* **Associated resources**: The `insights` table in the Masthead BigQuery dataset, specifically compute recommendations for scheduled pipelines
* **Skill definition**: [masthead-compute-savings-with-pipelines](https://github.com/masthead-data/for-agents/blob/main/skills/masthead-compute-savings-with-pipelines/SKILL.md)
### Storage savings with datasets
[Section titled “Storage savings with datasets”](#storage-savings-with-datasets)
Optimize BigQuery storage costs at the dataset level by switching storage billing models and setting expiration policies.
* **Associated resources**: The `insights` table in the Masthead BigQuery dataset, specifically dataset-level storage billing recommendations
* **Skill definition**: [masthead-storage-savings-with-datasets](https://github.com/masthead-data/for-agents/blob/main/skills/masthead-storage-savings-with-datasets/SKILL.md)
### Storage savings with tables
[Section titled “Storage savings with tables”](#storage-savings-with-tables)
Optimize BigQuery storage costs by identifying and removing dead-end and unused tables.
* **Associated resources**: The `insights` table in the Masthead BigQuery dataset, specifically storage recommendations for dead-end and unused tables
* **Skill definition**: [masthead-storage-savings-with-tables](https://github.com/masthead-data/for-agents/blob/main/skills/masthead-storage-savings-with-tables/SKILL.md)
# BigQuery dataset overview
> Overview of programmatic access to Masthead insights, lineage, and metadata via BigQuery shared datasets.
Masthead shares a BigQuery dataset containing your metadata, lineage relationships, and data quality insights. This dataset provides a direct, performant way to query and explore information about your data ecosystem.
## Set up access
[Section titled “Set up access”](#set-up-access)
To start querying the shared dataset, you must configure access for your Google identity:
1. Submit the [access request form](https://forms.gle/6zkAP1tmpbW4QY9Y9) to register your Google Account or Google Group with the Masthead team.
2. In the BigQuery console, click **+ Add data** and select [**Star a project by name**](https://cloud.google.com/bigquery/docs/bigquery-web-ui#starring_adding_a_project).
3. Enter `masthead-prod` and click **Star**.
4. The Masthead project becomes visible in the **Explorer** sidebar.
## Available resources
[Section titled “Available resources”](#available-resources)
The shared dataset exposes the following tables and procedures:
* [BigQuery dataset insights](/developer/api/insights): Actionable recommendations for cost optimization.
* [BigQuery dataset lineage](/developer/api/lineage): Consolidated table lineage relationships and traversal procedures.
# insights table
> Reference guide for the insights BigQuery table.
Preview
This feature is in preview and subject to change in the future.
## `insights` table
[Section titled “insights table”](#insights-table)
The core insights data table that provides actionable recommendations for cost optimization and data management.
### Description
[Section titled “Description”](#description)
The core insights data table for Masthead’s customers consolidates recommendations for cost optimization by identifying unused and dead-end tables, along with potential actions to reduce storage costs and improve data management efficiency.
### Schema
[Section titled “Schema”](#schema)
| Column name | Data type | Description |
| ------------------- | ----------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `category` | `STRING` | Category of the insight. Currently, this field supports only ‘Cost’. Future releases support additional categories. |
| `type` | `STRING` | Type of insight; valid values include ‘Dead end’, ‘Unused’, ‘Storage billing model’, and ‘Compute costs’. |
| `subtype` | `STRING` | Specific subtype of the insight, such as ‘Dead end table’, ‘Leaf dead end table’, ‘Unused table’, ‘Storage billing model’, ‘Dead end pipeline’, or compute model reassignment. |
| `project_id` | `STRING` | Google Cloud project ID |
| `target_resource` | `STRING` | Name of the target resource |
| `last_updated_time` | `TIMESTAMP` | When this insight was last updated |
| `overview` | `JSON` | JSON object with insight details. For details, see the insight types section. |
| `operations` | `JSON` | Array of recommended actions to address the insight. For details, see the insight types section. |
### Insight types
[Section titled “Insight types”](#insight-types)
#### Cost category
[Section titled “Cost category”](#cost-category)
##### Dead end
[Section titled “Dead end”](#dead-end)
* `Leaf dead end table` - Tables that aren’t used by any downstream processes and are at the end of the data lineage
* `Dead end table` - Tables that have no downstream dependencies and may be candidates for removal
JSON columns schema
**Overview:**
```json
{
"resource_type": "TABLE|VIEW",
"resource_name": "project.dataset.table",
"num_bytes": 123456,
"creation_time": "2025-01-01T00:00:00",
"last_modified_time": "2025-01-15T00:00:00",
"cost_30d": 10.5,
"savings_30d": 10.5
}
```
**Operations:**
```json
[
{
"action": "drop",
"resource_type": "TABLE|VIEW",
"resource_name": "project.dataset.table"
}
]
```
* `Dead end pipeline` - Pipelines that don’t produce any useful output and that downstream processes don’t use. This feature isn’t yet implemented.
##### Unused tables
[Section titled “Unused tables”](#unused-tables)
* `Unused table` - Tables that users haven’t accessed or queried within the configured time window
JSON columns schema
**Overview:**
```json
{
"resource_type": "TABLE|VIEW",
"resource_name": "project.dataset.table",
"num_bytes": 123456,
"creation_time": "2025-01-01T00:00:00",
"last_modified_time": "2025-01-15T00:00:00",
"cost_30d": 10.5,
"savings_30d": 10.5
}
```
**Operations:**
```json
[
{
"action": "drop",
"resource_type": "TABLE|VIEW",
"resource_name": "project.dataset.table"
}
]
```
##### Storage billing model
[Section titled “Storage billing model”](#storage-billing-model)
* `Storage billing model` - Datasets that you can move to a more cost-effective storage billing model based on their update patterns and data compression.
JSON columns schema
**Overview:**
```json
{
"resource_type": "dataset",
"resource_name": "project.dataset",
"storage_billing_model": "LOGICAL",
"location": "us-central1",
"cost_30d": 100.0,
"savings_30d": 20.0
}
```
**Operations:**
```json
[
{
"action": "alter",
"resource_type": "dataset",
"resource_name": "project.dataset",
"recommended_storage_billing_model": "PHYSICAL"
}
]
```
##### Compute costs
[Section titled “Compute costs”](#compute-costs)
* `Reassign models in [reservation] reservation` - Recommendations for reassigning specific data transformations to optimal BigQuery compute model based on historical slot utilization and query runtime characteristics.
### Usage examples
[Section titled “Usage examples”](#usage-examples)
Note
Replace `DATASET_NAME` with your Masthead dataset name in all SQL queries below.
#### Find dead end tables
[Section titled “Find dead end tables”](#find-dead-end-tables)
```sql
-- Get all dead end tables with their details
SELECT
subtype,
project_id,
target_resource,
INT64(overview.num_bytes) AS num_bytes,
STRING(overview.resource_type) AS resource_type,
last_updated_time
FROM `masthead-prod`.DATASET_NAME.insights
WHERE category = 'Cost'
AND type = 'Dead end'
ORDER BY num_bytes DESC;
```
#### Find unused tables
[Section titled “Find unused tables”](#find-unused-tables)
```sql
-- Get all unused tables sorted by size
SELECT
project_id,
target_resource,
INT64(overview.num_bytes) AS num_bytes,
STRING(overview.resource_type) AS resource_type,
last_updated_time
FROM `masthead-prod`.DATASET_NAME.insights
WHERE category = 'Cost'
AND type = 'Unused'
ORDER BY num_bytes DESC;
```
#### Calculate potential storage savings
[Section titled “Calculate potential storage savings”](#calculate-potential-storage-savings)
```sql
-- Calculate total storage used by dead end and unused tables
SELECT
type,
COUNT(*) AS resource_count,
SUM(SAFE.INT64(overview.num_bytes)) AS total_bytes,
ROUND(SUM(SAFE.INT64(overview.num_bytes)) / POW(1024, 3), 2) AS total_gb,
ROUND(SUM(overview.cost_30d), 2) AS monthly_cost_usd,
ROUND(SUM(overview.savings_30d), 2) AS monthly_savings_usd
FROM `masthead-prod`.DATASET_NAME.insights
WHERE category = 'Cost'
AND subtype IN ('Dead end table', 'Unused table')
AND overview.num_bytes IS NOT NULL
GROUP BY type
ORDER BY total_bytes DESC;
```
#### Get insights by project
[Section titled “Get insights by project”](#get-insights-by-project)
```sql
-- View insights grouped by project
SELECT
project_id,
type,
COUNT(*) AS insight_count,
SUM(SAFE.INT64(overview.num_bytes)) AS total_bytes
FROM `masthead-prod`.DATASET_NAME.insights
WHERE category = 'Cost'
AND subtype IN ('Dead end table', 'Unused table')
AND overview.num_bytes IS NOT NULL
GROUP BY project_id, type
ORDER BY total_bytes DESC;
```
#### Storage billing model recommendations
[Section titled “Storage billing model recommendations”](#storage-billing-model-recommendations)
```sql
-- Get a DDL statement to alter the storage billing model for recommended datasets
SELECT
*,
CONCAT('ALTER SCHEMA `', SAFE.STRING(operations[0].resource_name), '` SET OPTIONS(storage_billing_model = "', SAFE.STRING(operations[0].recommended_storage_billing_model),'");') AS ddl
FROM `masthead-prod`.DATASET_NAME.insights
WHERE type = 'Storage billing model'
ORDER BY
FLOAT64(overview.savings_30d) DESC
```
## AI agent skills
[Section titled “AI agent skills”](#ai-agent-skills)
To automate the analysis of cost optimization recommendations programmatically using AI agents, such as Google Antigravity or Claude Code, you can configure pre-built agent skills. These skills help agents query and interpret this insights table to recommend standard or enterprise compute models, alter dataset billing options, or identify dead-end tables.
For a list of available FinOps agent skills, see the [AI agent skills guide](/developer/ai-agent-skills#cost-optimization).
## Limitations
[Section titled “Limitations”](#limitations)
* **Preview Version**: This is an early preview version and the schema may change based on feedback.
* **Data Freshness**: Masthead updates insights daily based on usage patterns and lineage analysis.
* **Data Retention**: Insights include the most recent data from the account’s configured lookback window, which defaults to 30 days.
* **False Positives**: see details in [Dead-end and Unused Tables](/cost-insights/storage-costs) section.
## Best practices
[Section titled “Best practices”](#best-practices)
1. **Review Before Action**: Always manually verify insights before taking action on production data.
2. **Test Removals**: Consider moving tables to a staging area before permanent deletion.
3. **Check Dependencies**: Cross-reference with the [lineage table](/developer/api/lineage) to understand data dependencies.
4. **Monitor Trends**: Regular review of insights can help identify data management patterns and opportunities.
5. **Coordinate with Teams**: Ensure data owners are aware before removing resources they may depend on.
# lineage table and procedures
> Reference guide for the lineage BigQuery table and traversal procedures.
Preview
This feature is in preview and subject to change in the future.
## `lineage` table
[Section titled “lineage table”](#lineage-table)
The core lineage data table that consolidates and maintains data lineage relationships.
### Description
[Section titled “Description”](#description)
An alpha version of the core lineage data table for Masthead’s customers. This table consolidates and maintains data lineage relationships by joining edge and node information from the Marcia lineage system, providing a clean interface for tracking data flow connections, target types, and last update timestamps.
### Schema
[Section titled “Schema”](#schema)
| Column name | Data type | Description |
| ---------------- | --------- | ---------------------------------------------------------------------------------------------------------- |
| `source` | `STRING` | Name of the source data object (for example, `project.dataset.table`, routine, or URI) |
| `source_type` | `STRING` | Type of source data object. For details, see the [Object types](#object-types-and-subtypes) section below. |
| `source_subtype` | `STRING` | Subtype of source data object. For details, see the [Object types](#object-types-and-subtypes) section. |
| `process_type` | `STRING` | Type of process connecting source and target. See [Process types](#process-types) below. |
| `target` | `STRING` | Name of the target data object (for example, `project.dataset.table`, routine, or URI) |
| `target_type` | `STRING` | Type of target data object. For details, see the [Object types](#object-types-and-subtypes) section. |
| `target_subtype` | `STRING` | Subtype of target data object. For details, see the [Object types](#object-types-and-subtypes) section. |
#### Object types and subtypes
[Section titled “Object types and subtypes”](#object-types-and-subtypes)
`source_type` and `target_type` describe the category of the data asset:
* `TABLE` - Table-like objects in BigQuery
* `ROUTINE` - Stored procedures or user-defined functions
* `URI` - External import source or export destination URI
* `SERVICE_ACCOUNT` - Identity executing jobs
* `LOOKER` / `LOOKER_STUDIO_REPORT` / `POWERBI_REPORT` - BI dashboards and reporting assets
* `GOOGLE_SPREADSHEET` - Connected Google Sheets
* `LINKED_DATASET_RESOURCE` / `LINKED_DATASET_CONSUMER` - Analytics Hub linked datasets
`source_subtype` and `target_subtype` provide specific granularity:
* `DB_TABLE` - Standard native BigQuery table
* `VIEW` - Logical view
* `MATERIALIZED_VIEW` - Materialized view
* `EXTERNAL` - External table (for example, Google Cloud Storage, Bigtable, Google Sheets)
* `SHARDED` - Date-sharded table
* `SNAPSHOT` - Table snapshot
* `CLONE` - Table clone
* `LOOKER_DASHBOARD` / `LOOKER_LOOK` / `LOOKER_EXPLORE` - Looker asset subtypes
#### Process types
[Section titled “Process types”](#process-types)
`process_type` indicates the mechanism connecting the source and target:
* `PIPELINE` - Transformation pipeline or scheduled job (for example, dbt, Dataform, Airflow)
* `STREAM` - Streaming ingestion process
* `LINKED_DATASET` - Analytics Hub data sharing subscription
* `NULL` - Direct dependency (such as a view referencing an underlying table)
* `PARTICIPANT` - Service account or compute identity with an active relationship to the lineage node.
### Table usage examples
[Section titled “Table usage examples”](#table-usage-examples)
Note
Replace `DATASET_NAME` with your Masthead dataset name in all SQL queries below.
#### View lineage relationships
[Section titled “View lineage relationships”](#view-lineage-relationships)
```sql
-- View all lineage relationships for an account
SELECT *
FROM `masthead-prod`.DATASET_NAME.lineage
LIMIT 100;
```
#### Find downstream dependencies
[Section titled “Find downstream dependencies”](#find-downstream-dependencies)
```sql
-- Find all tables that depend on a specific source
SELECT target, target_type, target_subtype, process_type
FROM `masthead-prod`.DATASET_NAME.lineage
WHERE source = 'project_id.dataset_name.table_name'
AND target_type = 'TABLE';
```
#### Find upstream sources
[Section titled “Find upstream sources”](#find-upstream-sources)
```sql
-- Find all upstream dependencies feeding into a target table
SELECT source, source_type, source_subtype, process_type
FROM `masthead-prod`.DATASET_NAME.lineage
WHERE target = 'project_id.dataset_name.table_name';
```
#### Find recently updated lineage relationships
[Section titled “Find recently updated lineage relationships”](#find-recently-updated-lineage-relationships)
```sql
-- Get recent lineage changes in the last 7 days
SELECT source, target, target_type, updated_at
FROM masthead-prod.DATASET_NAME.lineage
WHERE DATE(updated_at) >= DATE_SUB(CURRENT_DATE(), INTERVAL 7 DAY)
ORDER BY updated_at DESC;
```
## `list_lineage` procedure
[Section titled “list\_lineage procedure”](#list_lineage-procedure)
A stored procedure for recursive lineage exploration both upstream and downstream from any data object.
### Procedure description
[Section titled “Procedure description”](#procedure-description)
An alpha version of programmatic lineage exploration for Masthead’s customers. This stored procedure enables recursive traversal of data lineage relationships both upstream and downstream from a given origin reference, providing a comprehensive view of data dependencies and their hierarchical relationships within the account’s data ecosystem.
### Procedure signature
[Section titled “Procedure signature”](#procedure-signature)
```sql
CALL `masthead-prod`.DATASET_NAME.list_lineage(origin_ref STRING)
```
### Parameters
[Section titled “Parameters”](#parameters)
* `origin_ref`: A `STRING` representing the reference of the data object to start lineage exploration from
### Output schema
[Section titled “Output schema”](#output-schema)
| Column name | Data type | Description |
| ---------------- | --------- | -------------------------------------------------------------------------------------- |
| `origin` | `STRING` | The reference of the starting point, for example, `project_id.dataset_name.table_name` |
| `direction` | `STRING` | `UPSTREAM` or `DOWNSTREAM` |
| `depth` | `INTEGER` | Distance from origin, starting at 1 |
| `source` | `STRING` | Source object reference |
| `source_type` | `STRING` | Type of source object |
| `source_subtype` | `STRING` | Subtype of source object |
| `process_type` | `STRING` | Type of process connecting source and target |
| `target` | `STRING` | Target object reference |
| `target_type` | `STRING` | Type of target object |
| `target_subtype` | `STRING` | Subtype of target object |
### Procedure usage examples
[Section titled “Procedure usage examples”](#procedure-usage-examples)
#### Basic usage
[Section titled “Basic usage”](#basic-usage)
```sql
-- Explore lineage for a specific table
CALL `masthead-prod`.DATASET_NAME.list_lineage('project_id.dataset_name.table_name');
```
#### Filtering results
[Section titled “Filtering results”](#filtering-results)
```sql
-- Get only upstream dependencies
CALL `masthead-prod`.DATASET_NAME.list_lineage('project_id.dataset_name.table_name');
-- Then filter in your application or with a view:
-- WHERE direction = 'UPSTREAM'
```
```sql
-- Get only direct dependencies (depth 1)
CALL `masthead-prod`.DATASET_NAME.list_lineage('project_id.dataset_name.table_name');
-- Then filter: WHERE depth = 1
```
```sql
-- Get only downstream tables
CALL `masthead-prod`.DATASET_NAME.list_lineage('project_id.dataset_name.table_name');
-- Then filter: WHERE direction = 'DOWNSTREAM' AND target_type = 'TABLE'
```
#### Further analysis
[Section titled “Further analysis”](#further-analysis)
```sql
-- Find the deepest dependency chain
CALL `masthead-prod`.DATASET_NAME.list_lineage('project_id.dataset_name.table_name');
-- Then analyze: SELECT MAX(depth) as max_depth FROM results
```
```sql
-- Identify critical upstream dependencies
CALL `masthead-prod`.DATASET_NAME.list_lineage('project_id.dataset_name.table_name');
-- Focus on: WHERE direction = 'UPSTREAM' AND depth <= 2
```
## AI agent skills
[Section titled “AI agent skills”](#ai-agent-skills)
To automate the traversal and analysis of data lineage programmatically using AI agents, such as Google Antigravity or Claude Code, you can configure pre-built agent skills. These skills help agents query the `lineage` table and call the `list_lineage` stored procedure to determine downstream dependencies and evaluate the blast radius of anomalies.
For details, see the [AI agent skills guide](/developer/ai-agent-skills#observability-and-incident-management).
## Limitations
[Section titled “Limitations”](#limitations)
* **Performance**: Large lineage graphs may have slower query performance.
* **Cycle Detection**: The recursive queries include basic cycle prevention but complex cycles may still cause issues.
* **Data Freshness**: Masthead updates lineage daily.
* **Cross-Project Dependencies**: External project references may have limited detail.
* **Data Retention:** Lineage includes relationships only if they changed within the account’s configured lookback window, which defaults to 30 days. This ensures lineage data remains current and relevant.
# Authentication and tokens
> Learn how to authenticate and manage tokens for Masthead developer interfaces.
Masthead provides several programmatic interfaces, each requiring a specific authentication method:
* **BigQuery shared dataset**: Authenticates using your Google Cloud IAM credentials. For details, see the [BigQuery shared dataset setup guide](/developer/api#set-up-access).
* **Resource management API**: Authenticates using static API tokens for the Masthead Terraform provider. For details, see the [Resource management API configuration guide](/developer/resource-management-api#quickstart).
* **MCP server**: Authenticates using Google SSO for interactive users or service account token exchanges for headless environments.
***
## MCP server
[Section titled “MCP server”](#mcp-server)
The Masthead MCP server supports two authentication modes depending on your environment.
### Interactive user accounts
[Section titled “Interactive user accounts”](#interactive-user-accounts)
If you use interactive developer tools like Claude Code, Codex, or Google Antigravity on your local workstation, the client automatically handles authentication:
1. On first launch, the client opens a browser tab.
2. Log in using your Google SSO credentials.
3. The client caches the returned JWT locally for subsequent requests.
### Headless service accounts
[Section titled “Headless service accounts”](#headless-service-accounts)
If you run MCP clients in headless environments like Google Cloud Build, GitHub Actions, or background daemon processes, you must exchange a Google Cloud service account token for a Masthead access token.
#### Register the service account
[Section titled “Register the service account”](#register-the-service-account)
Create a service account in your Google Cloud project and register its email address with your Masthead tenant.
#### Exchange tokens
[Section titled “Exchange tokens”](#exchange-tokens)
Exchange your service account’s Google ID token for a Masthead access token. The returned token is valid for 1 hour.
* Bash / CLI
To exchange the token using the Google Cloud CLI and `curl`, run the following commands:
```bash
# 1. Mint Google ID token (--include-email is required)
IDT=$(gcloud auth print-identity-token \
--impersonate-service-account="your-bot@YOUR_PROJECT.iam.gserviceaccount.com" \
--audiences=https://sso.mastheadata.com \
--include-email)
# 2. Exchange for Masthead Access Token
TOKEN=$(curl -s -X POST https://sso.mastheadata.com/oauth2/token \
-d 'grant_type=urn:ietf:params:oauth:grant-type:token-exchange' \
-d 'subject_token_type=urn:ietf:params:oauth:token-type:id_token' \
-d 'client_id=service-account' \
--data-urlencode "subject_token=$IDT" | jq -r .access_token)
```
* Python
To exchange the token programmatically in a Python environment, use the following code:
```python
import google.auth
from google.auth import impersonated_credentials
from google.auth.transport.requests import Request
import requests
# Target audience and service account
AUDIENCE = "https://sso.mastheadata.com"
SERVICE_ACCOUNT_EMAIL = "your-bot@YOUR_PROJECT.iam.gserviceaccount.com"
# 1. Mint the Google ID token (impersonating the service account)
source_credentials, _ = google.auth.default()
target_credentials = impersonated_credentials.IDTokenCredentials(
source_credentials,
target_audience=AUDIENCE,
target_service_account=SERVICE_ACCOUNT_EMAIL,
include_email=True
)
target_credentials.refresh(Request())
id_token = target_credentials.token
# 2. Exchange the Google ID token for a Masthead access token
response = requests.post(
"https://sso.mastheadata.com/oauth2/token",
data={
"grant_type": "urn:ietf:params:oauth:grant-type:token-exchange",
"subject_token_type": "urn:ietf:params:oauth:token-type:id_token",
"client_id": "service-account",
"subject_token": id_token,
}
)
response.raise_for_status()
token = response.json()["access_token"]
```
#### Configure the client
[Section titled “Configure the client”](#configure-the-client)
Pass the returned token in the static `Authorization` header of your client configuration. For example, to add the server in Claude Code:
```bash
claude mcp add --transport http masthead https://mcp.mastheadata.com/mcp \
--header "Authorization:Bearer $TOKEN"
```
# Masthead MCP Server
> Masthead MCP server provides near-realtime access to pipeline monitoring, incident management, and table lineage data.
Use MCP to integrate Masthead with your favorite AI coding tools and services.
The Masthead MCP server provides access to pipeline monitoring, incident management, and table lineage data. See the [tool definitions](/developer/mcp/tools) for the full list of available commands.
## Client setup
[Section titled “Client setup”](#client-setup)
Interactive clients automatically handle Google SSO authentication in the browser and cache the token. Headless environments, such as CI/CD or server agents, should use a service account token.
* **Server URL**: `https://mcp.mastheadata.com/mcp`
* **Transport**: Streamable HTTP using `POST /mcp`
* **Auth**: Bearer JWT issued by `https://sso.mastheadata.com`. To learn how to generate and exchange tokens, see the [Authentication and tokens guide](/developer/authentication).
Claude Code CLI
Run the following command to add the server:
```bash
claude mcp add --transport http masthead https://mcp.mastheadata.com/mcp
```
*Note that Claude Code automatically manages the Google SSO flow in the browser and caches the token.*
Codex
Create or edit `.codex/config.toml` in your project root:
```toml
[mcp_servers.masthead]
url = "https://mcp.mastheadata.com/mcp"
```
To log in and authenticate:
```bash
codex mcp login masthead
```
VS Code
Create or edit `.vscode/mcp.json` in your workspace root for compatible VS Code extensions. This applies to extensions such as GitHub Copilot and customized workspace agents:
```json
{
"servers": {
"masthead": {
"type": "http",
"url": "https://mcp.mastheadata.com/mcp"
}
}
}
```
Google Antigravity
Antigravity supports stdio transport only. Use `mcp-remote` as the bridge.
Open Agent panel → **MCP Servers** → **Manage MCP Servers** → edit `mcp_config.json`:
```json
{
"mcpServers": {
"masthead": {
"command": "npx",
"args": [
"-y",
"mcp-remote",
"https://mcp.mastheadata.com/mcp"
]
}
}
}
```
*Reload MCP servers or restart the IDE. A browser tab opens for Google SSO on first launch.*
Gemini Enterprise
Unlike the preceding interactive clients, Gemini Enterprise connects as a **confidential OAuth client**: it needs a **Client ID** and **Client Secret**. Masthead provisions these for your tenant; this guide assumes you already have them. Users sign in with their own Google Accounts, and each gets their own tenant-scoped access.
**1. Create the data store.** Follow the guide [to create the custom MCP server data store](https://docs.cloud.google.com/gemini/enterprise/docs/connectors/custom-mcp-server/set-up-custom-mcp-server#create_the_custom_mcp_server_data_store).
**2. Fill in the authentication settings** with the values below, pasting the Client ID and Client Secret you received from Masthead:
| Field | Value |
| ---------------------------- | ---------------------------------------------- |
| MCP Server URL | `https://mcp.mastheadata.com/mcp` |
| Authorization URL | `https://sso.mastheadata.com/oauth2/authorize` |
| Authorization URL Parameters | `&access_type=offline&prompt=consent` |
| Token URL | `https://sso.mastheadata.com/oauth2/token` |
| Client ID | *(from Masthead)* |
| Client Secret | *(from Masthead)* |
| Scopes | `mcp offline_access` |
| Enable PKCE Support | leave **unchecked** |
**3. Authenticate.** Click **Login**. A browser tab opens for authentication. Sign in and approve the access, then click **Continue**.
**4. Finish the connector.** Add a description, click **Continue**, choose a location and connector name, then **Create**. Wait for the data store status to change from **Creating** to **Active**.
**5. Enable the tools.** Open the data store, then click **Actions → Reload custom actions** to fetch the Masthead tool list. Select the actions you want and click **Enable actions**.
**6. Use it.** Attach the data store to a Gemini Enterprise app or assistant. You can then ask it questions in natural language, and it calls the Masthead tools automatically (for example, *“list the projects Masthead monitors”* or *“show open data incidents”*).
***
## AI agent skills
[Section titled “AI agent skills”](#ai-agent-skills)
To help your AI assistant automate complex tasks with the Masthead MCP server, you can configure pre-built agent skills. For the list of available skills and setup instructions, see the [AI agent skills guide](/developer/ai-agent-skills).
# Masthead MCP Tools Reference
> Detailed reference for the Model Context Protocol tools exposed by the Masthead server.
The Masthead Model Context Protocol server exposes a set of read-only and mutation tools that allow AI agents to interact with your data observability ecosystem in near-realtime.
Below is the reference guide for each tool, including its purpose.
***
## Discovery and context tools
[Section titled “Discovery and context tools”](#discovery-and-context-tools)
### `list_projects`
[Section titled “list\_projects”](#list_projects)
List all GCP project IDs monitored for your tenant. Use these project IDs as filters, such as `projectId`, in subsequent incident and table metadata queries.
### `list_users`
[Section titled “list\_users”](#list_users)
List all users in your Masthead tenant. This is useful for identifying email addresses before assigning ownership of an incident.
### `get_tenant_settings`
[Section titled “get\_tenant\_settings”](#get_tenant_settings)
Return the tenant settings an agent needs before running FinOps skills: whether the tenant enabled the BigQuery insights export, the export project and dataset (`masthead-prod.`) with its tables (`insights`, `lineage`), and the look-back window in days used to flag dead-end and unused tables (30 unless configured otherwise). Skills call this first and stop with a request-access link when the tenant disables the export.
***
## Incident management tools
[Section titled “Incident management tools”](#incident-management-tools)
### `list_open_incidents`
[Section titled “list\_open\_incidents”](#list_open_incidents)
List all active unresolved incidents, such as Open, In Progress, or Acknowledged, over the last 14 days, optionally bounded by a limit.
### `list_incidents`
[Section titled “list\_incidents”](#list_incidents)
Full incident search history with options to filter by project, status, severity, or pipeline type.
### `get_incident_details`
[Section titled “get\_incident\_details”](#get_incident_details)
Fetch full details and diagnostics for a specific incident group by its UUID.
***
## Incident action and mitigation tools
[Section titled “Incident action and mitigation tools”](#incident-action-and-mitigation-tools)
### `bulk_update_incidents`
[Section titled “bulk\_update\_incidents”](#bulk_update_incidents)
Update the status, severity, assignee, and notes of one or more incidents in one call. Set only the fields you want to change:
* `status`: the new life-cycle status.
* `severity`: `P1`–`P5`, or `NONE` to clear it.
* `assigneeEmail`: the email of a registered Masthead user, or `NONE` to unassign. The call fails if no user has that email.
* `notes` with `notesMode`: `ADD`, the default, puts the note before the existing notes with a `---` line between them. `REPLACE` overwrites the notes; `REPLACE` with empty notes clears them.
All changes in a call apply together, and the incident history records each one. The result lists each incident with `success`, and a `message` such as `Incident not found` when an incident wasn’t updated.
***
## Table, BI asset and lineage tools
[Section titled “Table, BI asset and lineage tools”](#table-bi-asset-and-lineage-tools)
### `get_table_metadata`
[Section titled “get\_table\_metadata”](#get_table_metadata)
Retrieve schema, columns count, isAnomaly status, and alert tier settings for a BigQuery table.
### `get_table_pipelines`
[Section titled “get\_table\_pipelines”](#get_table_pipelines)
Fetch the metadata and status of pipelines writing to a specific table.
### `get_table_lineage`
[Section titled “get\_table\_lineage”](#get_table_lineage)
Traces the upstream/downstream tables and pipelines associated with the target table to verify blast radius.
### `list_asset_scores`
[Section titled “list\_asset\_scores”](#list_asset_scores)
List the tenant’s scored assets—BigQuery tables and BI assets (Looker dashboards, Looker looks, Looker Studio reports, Google Sheets)—highest score first, with the raw score metrics, the current alert tier, and each asset’s percentile rank within its own asset type in the requested scope, plus p50/p90/p95 per asset type in `extra` (covering only the asset types present on the page). The score (0-1) ranks an asset’s importance from downstream and upstream compute cost, write, and read frequency, BI assets and service-account readers, normalized within the tenant and asset type. Filter by `assetTypes`, `project`, `dataset`, `alertTiers` and `minPercentile` to fetch tier-change candidates; apply with `update_table_priority` for tables or `update_bi_asset_priority` for BI assets.
### `update_table_priority`
[Section titled “update\_table\_priority”](#update_table_priority)
Adjust the monitoring alert level for a BigQuery table.
### `update_bi_asset_priority`
[Section titled “update\_bi\_asset\_priority”](#update_bi_asset_priority)
Adjust the monitoring alert level for a Looker dashboard, Looker look, Looker Studio report, or Google Sheet, and return that asset’s own score row (matched by `uuid`) after the change so the caller can confirm the new `alertType`. The call fails if Masthead didn’t apply the change. Downstream BI asset priority also drives pipeline anomaly alerting.
***
## Data scan tools
[Section titled “Data scan tools”](#data-scan-tools)
Caution
Available only on the `mcp.mastheadata.com` MCP server.
See [custom data scans](/governance/data-quality-scans#custom-data-scans) for the table columns and grants.
### `list_data_scans`
[Section titled “list\_data\_scans”](#list_data_scans)
List the tenant’s custom data scans with their table, frequency, processing delay, active flag, and last and next run times. Masthead sets up scans whose `source` is `MANUAL`; you can’t change them with these tools.
### `create_data_scan`
[Section titled “create\_data\_scan”](#create_data_scan)
Validate or create a custom data scan on a BigQuery table. With `dryRun` set to `true`, the default, Masthead reads the table as its service account and returns a summary—rows, tables, metrics, time range, and bytes processed—or an error that says what to fix. With `dryRun` set to `false`, it also creates the scan and starts its first run right away.
### `update_data_scan`
[Section titled “update\_data\_scan”](#update_data_scan)
Pause or resume a scan, change its frequency or processing delay, or point it at another table. Changing the table or frequency deletes the scan’s history and analyzes it again from scratch.
### `delete_data_scan`
[Section titled “delete\_data\_scan”](#delete_data_scan)
Delete a scan with its stored results and open incidents. The BigQuery table stays in place.
# Resource management API
> Reference guide for the Masthead Resource Management API and Terraform provider.
To manage resources such as data products, domains, or users programmatically, use the [Masthead Terraform provider](https://registry.terraform.io/providers/masthead-data/masthead/latest).
## Quickstart
[Section titled “Quickstart”](#quickstart)
1. Create a token on the [API Tokens](https://app.mastheadata.com/users?tab=API+Tokens) page.
2. Provide the token to the provider configuration.
```hcl
terraform {
required_providers {
masthead = {
source = "masthead-data/masthead"
}
}
}
provider "masthead" {
api_token = "YOUR_API_TOKEN"
}
```
For a step-by-step guide on generating these tokens, see the [API tokens guide](/settings/account-settings#api-tokens).
# Integrate using IaC
> Learn how to connect Masthead with your BigQuery data warehouse using Terraform.
To connect Masthead with your BigQuery data warehouse, you’ll need to create a few integration resources in your Google Cloud project.
Note
An account running an installation should have the `Owner` role. Alternatively, you must assign the following roles in the Google Cloud project:
* [Logging Admin](https://cloud.google.com/iam/docs/roles-permissions/logging#logging.admin): `roles/logging.admin`
* [Pub/Sub Admin](https://cloud.google.com/iam/docs/roles-permissions/pubsub#pubsub.admin): `roles/pubsub.admin`
* [Project IAM Admin](https://cloud.google.com/iam/docs/roles-permissions/resourcemanager#resourcemanager.projectIamAdmin): `roles/resourcemanager.projectIamAdmin`
## Deploy the resources
[Section titled “Deploy the resources”](#deploy-the-resources)
### Add Masthead agent module to your IaC project
[Section titled “Add Masthead agent module to your IaC project”](#add-masthead-agent-module-to-your-iac-project)
* Terraform
```hcl
module "masthead-agent" {
source = "masthead-data/masthead-agent/google"
project_id = "YOUR_PROJECT_ID"
# Enable modules for the used services
enable_modules = {
bigquery = true
dataform = true
dataplex = true
analytics_hub = true
}
}
```
More details about the module [on Terraform Registry](https://registry.terraform.io/modules/masthead-data/masthead-agent/google/latest).
* Pulumi
Install required package:
```bash
pulumi package add terraform-module masthead-data/masthead-agent/google 0.2.4 masthead-agent
```
Initialize the package in your repository:
```python
import pulumi_masthead_agent as masthead_agent
masthead_agent.Module(
"masthead-agent",
project_id='your-project-id', # Replace with your actual project ID
enable_modules={
"bigquery": True,
"dataform": True,
"dataplex": True,
"analytics_hub": True,
},
)
```
### Apply the new resource changes
[Section titled “Apply the new resource changes”](#apply-the-new-resource-changes)
* Terraform
`bash terraform init terraform plan terraform apply`
* Pulumi
`bash pulumi preview pulumi up`
### Continue integration on the UI
[Section titled “Continue integration on the UI”](#continue-integration-on-the-ui)
Go back to [Deployment](https://app.mastheadata.com/deployment) page, click **Verify custom deployment,** enter the project ID and click **Check permissions and connect**.
### Configuration completed
[Section titled “Configuration completed”](#configuration-completed)
Masthead installation creates your workspace and opens your dashboard once setup is complete.
### Workspace is ready
[Section titled “Workspace is ready”](#workspace-is-ready)
You’ll receive a notification once Masthead collects all metadata and prepares insights.
All done. Thank you for completing installation.
## Export retrospective logs
[Section titled “Export retrospective logs”](#export-retrospective-logs)
Masthead allows you to get observability insights within a few hours after project integration.
By default, Masthead uses the [Private Logs Viewer](https://cloud.google.com/iam/docs/roles-permissions/logging#logging.privateLogViewer) role to export 30 days of retrospective logs automatically. If you set `enable_privatelogviewer_role = false` in the Terraform module, you can enable quick insights by exporting the retrospective logs to Masthead for analysis:
Masthead provides `Storage Object Creator` permission to your service account to write the exported retrospective logs into Masthead’s Google Cloud Storage bucket.
The account must have the following permissions in your project:
* [Logging Admin](https://cloud.google.com/iam/docs/roles-permissions/logging#logging.admin): `roles/logging.admin`
* [Logs Configuration Writer](https://cloud.google.com/iam/docs/roles-permissions/logging#logging.configWriter): `roles/logging.configWriter`
Copy the code, update the variables and run the command to start the export operation:
* PROJECT\_ID - your project ID
* YYYY-MM-DD - export start date, 30 days ago
```bash
gcloud logging copy _Default storage.googleapis.com/masthead_retro_logs_{PROJECT_ID} \
--location=global \
--log-filter='protoPayload.methodName="google.cloud.bigquery.storage.v1.BigQueryWrite.AppendRows" OR protoPayload.methodName="google.cloud.bigquery.v2.JobService.InsertJob" OR protoPayload.methodName="google.cloud.bigquery.v2.TableService.InsertTable" OR protoPayload.methodName="google.cloud.bigquery.v2.JobService.Query" resource.type="bigquery_table" OR resource.type="bigquery_dataset" OR resource.type="bigquery_project" timestamp > "{YYYY-MM-DD}T00:00:00.0Z"'
```
[How to batch and route logs retrospectively](https://cloud.google.com/logging/docs/routing/copy-logs).
> \[!NOTE] Check the progress of the started operation:
>
> ```bash
> gcloud logging operations describe OPERATION_ID \
> --location=global --project=PROJECT_ID
> ```
### Inform Masthead team
[Section titled “Inform Masthead team”](#inform-masthead-team)
Your Masthead account uses the exported data to generate the compute and cost insights immediately.
## VPC-SC configuration
[Section titled “VPC-SC configuration”](#vpc-sc-configuration)
If your Google Cloud project is within a VPC service perimeter, you must configure ingress and egress policies to ensure that the necessary resources are accessible to Masthead Data.
Policies configuration suggestion
```hcl
restricted_services = [
"bigquery.googleapis.com",
"pubsub.googleapis.com",
"logging.googleapis.com",
"dataplex.googleapis.com",
"analyticshub.googleapis.com"
]
ingress_policies {
ingress_from {
identities = [
"serviceAccount:masthead-data@masthead-prod.iam.gserviceaccount.com",
"serviceAccount:retro-data@masthead-prod.iam.gserviceaccount.com",
"serviceAccount:masthead-dataplex@masthead-prod.iam.gserviceaccount.com",
"serviceAccount:masthead-dataform@masthead-prod.iam.gserviceaccount.com"
]
sources {
resource = "projects/431544431936" # masthead-prod
}
}
ingress_to {
resources = ["*"]
roles = [
"roles/bigquery.metadataViewer",
"roles/bigquery.resourceViewer",
"roles/logging.privateLogViewer",
"roles/pubsub.subscriber",
"roles/analyticshub.viewer",
"projects/YOUR_PROJECT_ID/roles/analyticsHubSubscriptionViewer",
]
}
}
egress_policies {
egress_to {
resources = ["*"]
roles = [
"roles/bigquery.metadataViewer",
"roles/bigquery.resourceViewer"
]
}
egress_from {
identities = [
"serviceAccount:masthead-data@masthead-prod.iam.gserviceaccount.com",
]
sources {
resource = "projects/431544431936" # masthead-prod
}
}
}
```
# Quickstart
> Masthead installation details for Google Cloud + BigQuery
Masthead offers several options to connect to your Google Cloud environment:
1. [OAuth](#oauth-installation) - the quickest option, integrate in a few clicks
2. [Terraform](/get-started/integrate-using-iac) - use infrastructure as a code approach
## OAuth installation
[Section titled “OAuth installation”](#oauth-installation)
OAuth installation takes about 2 minutes.
Note
A Google Account running the installation should have **Owner** permissions for the Google Cloud project.
Otherwise, you must assign the following roles:
* [Service Usage Admin](https://cloud.google.com/iam/docs/roles-permissions/serviceusage#serviceusage.serviceUsageAdmin)
* [Logging Admin](https://cloud.google.com/iam/docs/roles-permissions/logging#logging.admin)
* [Pub/Sub Admin](https://cloud.google.com/iam/docs/roles-permissions/pubsub#pubsub.admin)
* [Project IAM Admin](https://cloud.google.com/iam/docs/roles-permissions/resourcemanager#resourcemanager.projectIamAdmin)
### Go to [sign up](https://app.mastheadata.com/sign-up)
[Section titled “Go to sign up”](#go-to-sign-up)
Fill the form, agree with Privacy Policy and click **Sign up with Google**
### Provide access to Google Cloud
[Section titled “Provide access to Google Cloud”](#provide-access-to-google-cloud)
Select checkboxes to allow Masthead to create the required resources during installation. See [what Masthead creates during deployment](#cloud-resources-created-by-oauth-installation).
Note
Masthead doesn’t save provided authorization credentials after the integration step is complete.
### Connect your Google Cloud project
[Section titled “Connect your Google Cloud project”](#connect-your-google-cloud-project)
Select the Google Cloud project that contains the BigQuery resources and pipelines you want Masthead to monitor. Press **Connect**.
### Configuration completed
[Section titled “Configuration completed”](#configuration-completed)
Masthead installation creates your workspace and opens your dashboard once setup is complete.
### Workspace is ready
[Section titled “Workspace is ready”](#workspace-is-ready)
You’ll receive an email notification with the link to the workspace.
Masthead sends a notification once metadata collection is complete and insights are ready.
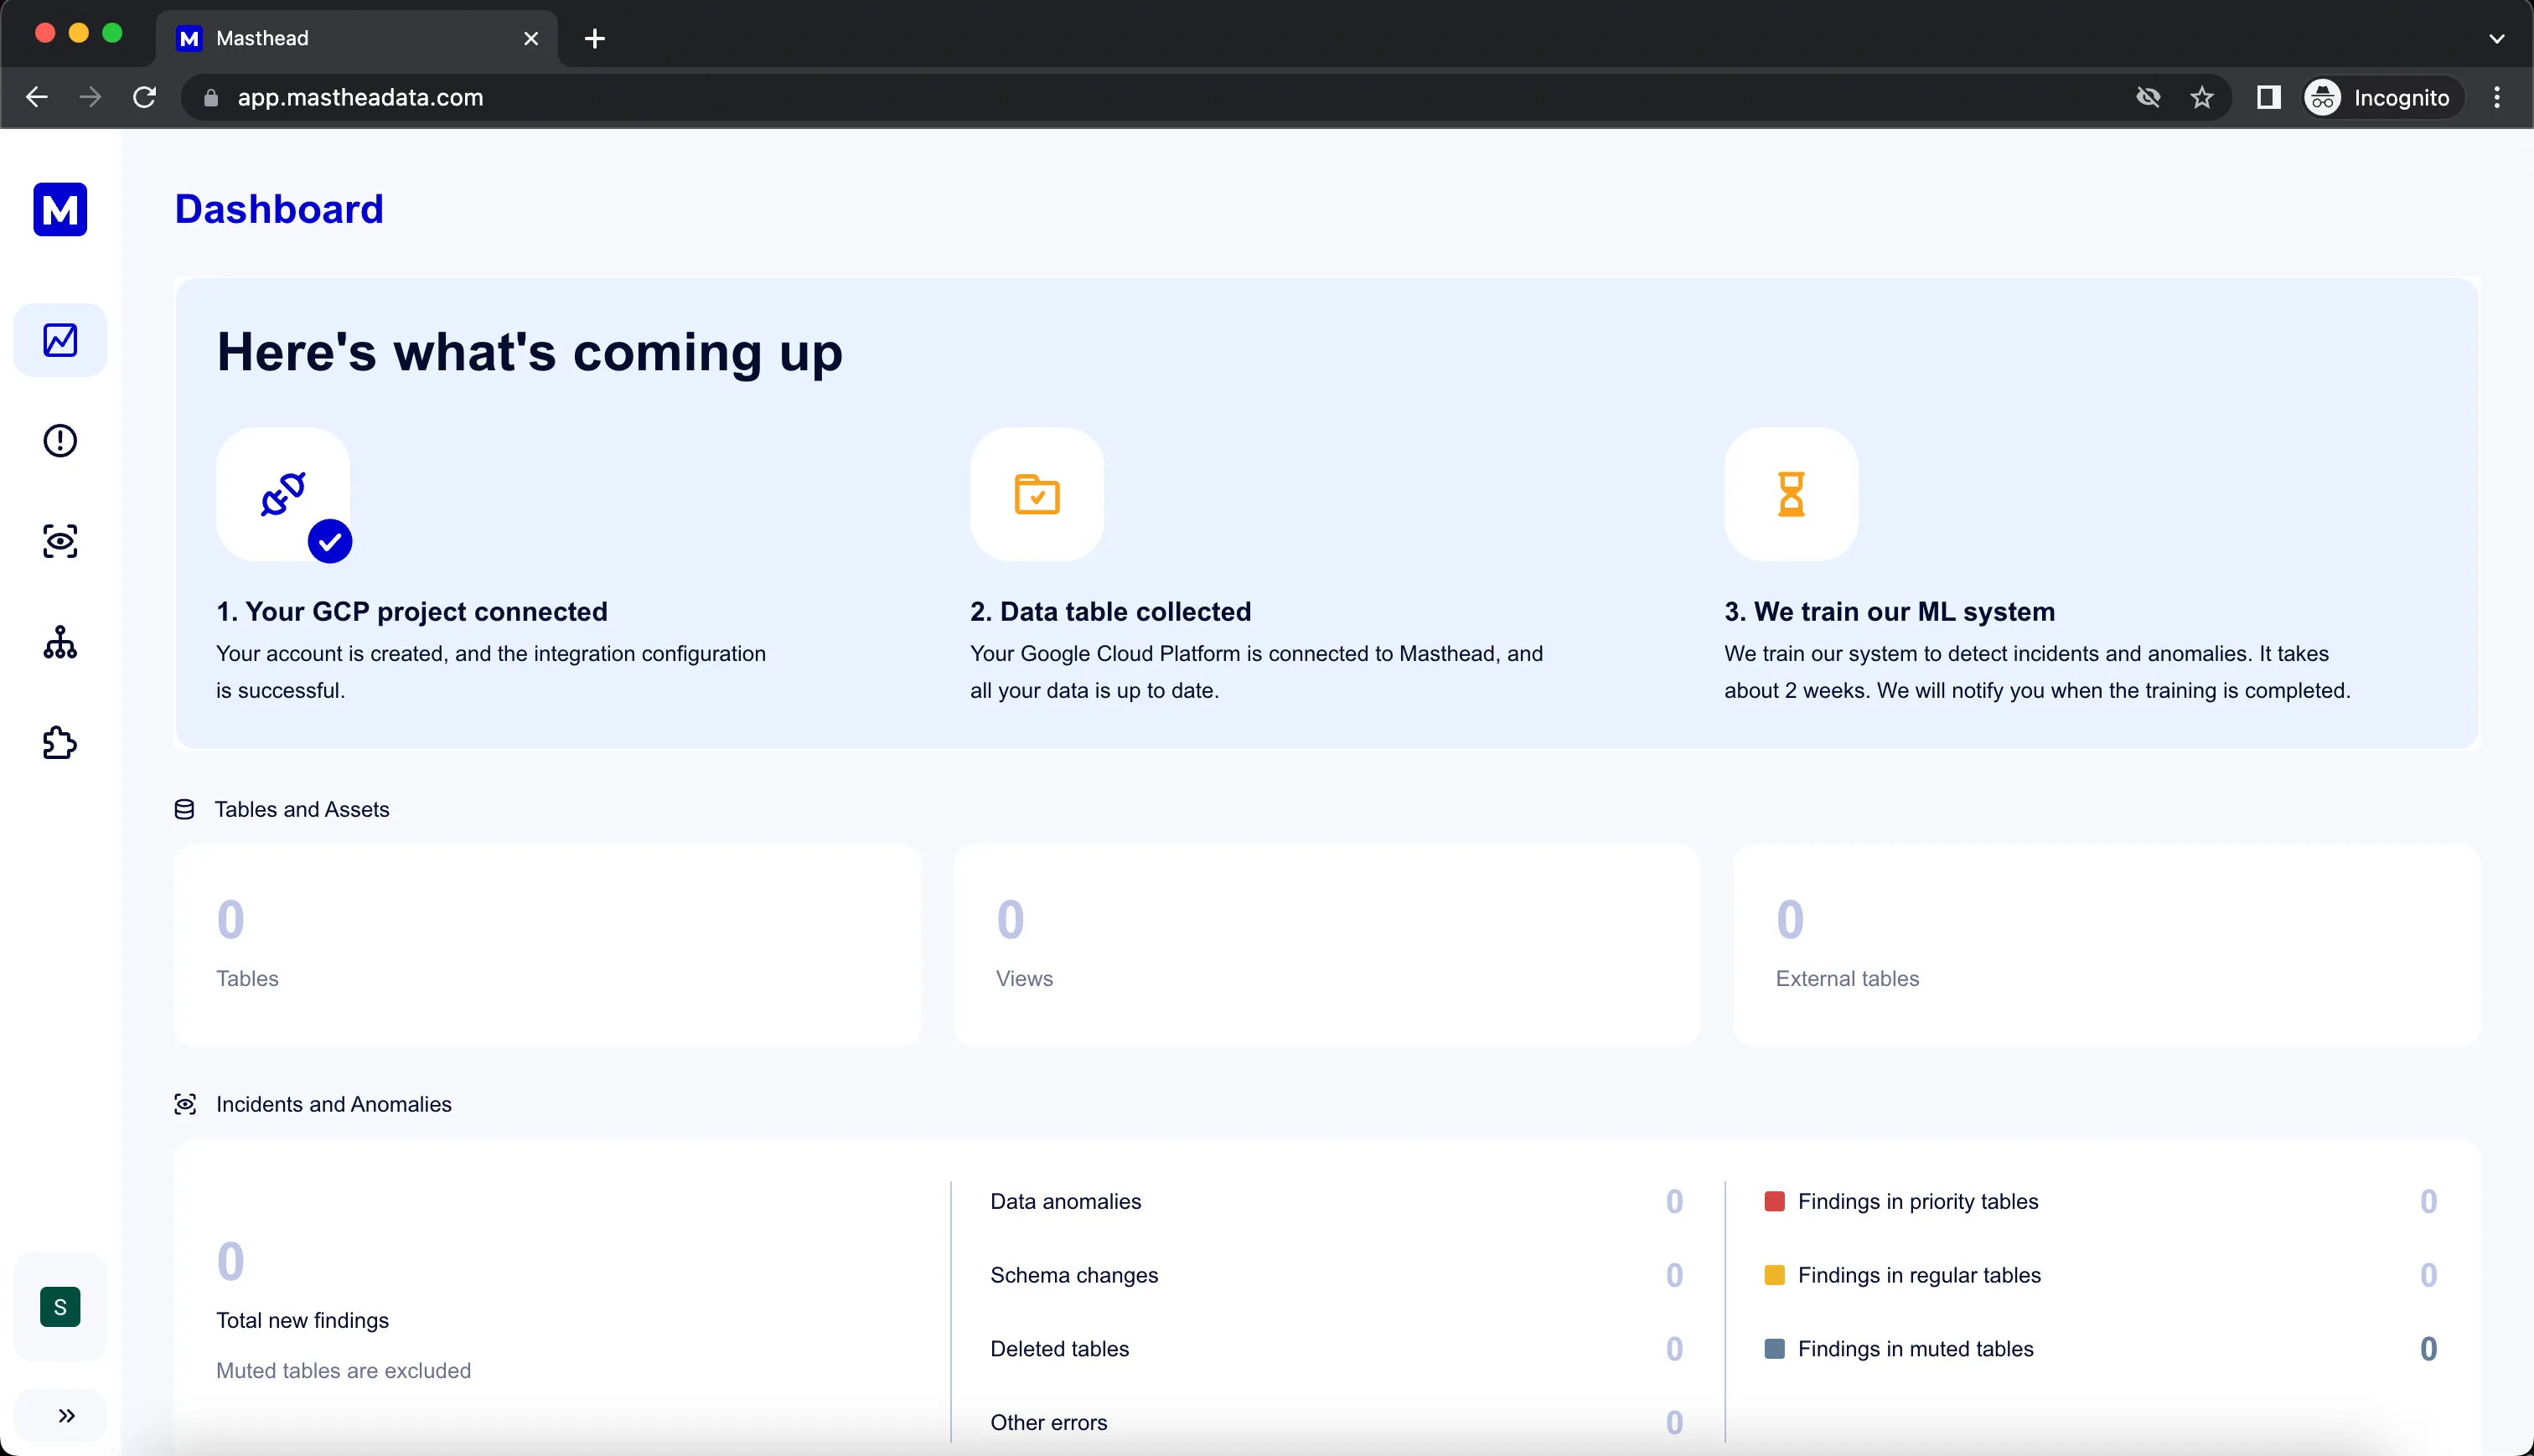
All done. Thank you for completing installation.
Google Cloud resources created by OAuth installation
#### Pub/Sub
[Section titled “Pub/Sub”](#pubsub)
* **Topic**: `masthead-topic`
* **Subscription**: `masthead-agent-subscription`
#### Logging
[Section titled “Logging”](#logging)
* **Log Sink**: `masthead-agent-sink`
* **Destination**: Pub/Sub topic `masthead-topic`
* **Filter**: BigQuery audit logs:
* `AppendRows`
* `InsertJob`
* `InsertTable`
* `Query`
#### IAM
[Section titled “IAM”](#iam)
* **Project IAM roles granted**
* to Google Cloud Logging service agent:
* [Pub/Sub Publisher](https://cloud.google.com/iam/docs/roles-permissions/pubsub#pubsub.publisher)
* to Masthead service account:
* [BigQuery Metadata Viewer](https://cloud.google.com/iam/docs/roles-permissions/bigquery#bigquery.metadataViewer)
* [BigQuery Resource Viewer](https://cloud.google.com/iam/docs/roles-permissions/bigquery#bigquery.resourceViewer)
* [Private Logs Viewer](https://cloud.google.com/iam/docs/roles-permissions/logging#logging.privateLogViewer)
* [Pub/Sub Subscriber](https://cloud.google.com/iam/docs/roles-permissions/pubsub#pubsub.subscriber)
# Data Products
## What’s a data product?
[Section titled “What’s a data product?”](#whats-a-data-product)
In Masthead, a data product is a curated collection of related data assets, such as datasets or tables, that you treat as a single, logical unit. It represents a valuable, ready-to-use data resource designed for a specific purpose or audience within your organization. Think of it as packaging data for consumption, complete with metadata, ownership, cost tracking, and quality monitoring.
Key components of a data product include:
* **Name:** A unique identifier for the data product.
* **Data Assets:** The underlying data included. Currently supported types:
* datasets
* tables
* **Domain:** An optional category or business area the product belongs to. See [Domains](/governance/domains).
* **Description:** Textual information about the product’s purpose and content. This field supports Markdown formatting.
## Create data product
[Section titled “Create data product”](#create-data-product)
You can create a Data Products to formally package and manage your key data assets.
### Go to data products
[Section titled “Go to data products”](#go-to-data-products)
Open [Data Products](https://app.mastheadata.com/data-product/) page and click **Create.** This opens the “Create Data Product” page.
### Enter name
[Section titled “Enter name”](#enter-name)
Provide a clear and descriptive **Name** for your data product. Masthead requires this field.
### Select data assets
[Section titled “Select data assets”](#select-data-assets)
Choose whether you are adding Datasets or Tables using the toggle buttons. Note that only Datasets is currently active.
In the “Data assets” input field, start typing the name of an existing dataset or table you want to include.
Select the desired assets from the dropdown list. You can add multiple assets. Masthead requires this field.
### Assign domain
[Section titled “Assign domain”](#assign-domain)
Click the “Select a domain” dropdown. Choose an existing domain from the list to categorize your data product. This step is optional.
Alternatively, click “Create new domain” if the domain doesn’t exist yet. See more about [Domains](/governance/domains).
### Add description
[Section titled “Add description”](#add-description)
Provide a detailed **Description** in the text area. Explain the purpose, content, intended use, or any other relevant context for the data product. Use the Markdown formatting if needed. This step is optional.
### Click create
[Section titled “Click create”](#click-create)
After you enter all required information and add any optional details, click the **Create** button. To discard changes, click **Cancel**.
Upon successful creation, Masthead redirects you to the detail page for the newly created data product. Here you can see the configuration you’ve defined, and the aggregated insights populate shortly.
You can explore the associated costs, incidents, assets, or subscribers and dive deeper into the details where applicable. See more in [Product Metrics](#product-metrics).
## Why use data products?
[Section titled “Why use data products?”](#why-use-data-products)
Creating and managing data products in Masthead provides several benefits:
* Group logically related datasets and tables under a single, meaningful entity.
* Assign clear ownership through [domains](/governance/domains) and track consumers using [subscribers](#subscribers).
* Monitor core data product metrics in an easy overview:
* Estimated compute and storage costs associated with the upstream data assets and pipelines within the product.
* Track associated pipeline and table incidents impacting the data product’s health.
* Understand who is using the data product and how often through job execution tracking.
## Referenced data assets
[Section titled “Referenced data assets”](#referenced-data-assets)
Masthead designs data products so that you can assign only your curated data assets for the data product. Masthead uses the lineage connection information to identify all levels of the referenced data assets upstream. The calculation of the [costs](#costs) and [incidents](#incidents) metrics includes assigned and referenced data assets along with all related pipelines.

Referenced data assets
This allows to keep data product assets management easy, and at the same time track all important operational information to the data product owners and subscribers.
## Product metrics
[Section titled “Product metrics”](#product-metrics)
### Subscribers
[Section titled “Subscribers”](#subscribers)
Users or service accounts that consume or interact with the data product.
Masthead identifies and displays all subscribers to make data consumption more transparent. See also [usage](#usage) to analyze the frequency of these interactions.

Product subscribers
### Usage
[Section titled “Usage”](#usage)
This metric measures the number of job executions that use the product’s assets as a source. This metric offers insights about the overall consumption frequency across data assets. Masthead aggregates the usage metric visualization on the dataset level.


### Incidents
[Section titled “Incidents”](#incidents)
Associated table and pipeline issues affecting reliability.

Product related incidents
### Costs
[Section titled “Costs”](#costs)
Aggregated compute and storage costs. To see more details regarding the compute costs of this product, click the **Compute costs** panel to go to the [Pipeline Costs](/cost-insights/compute-costs) page.

Product related costs
# Data Quality Scans
Data Quality scans help to check data for certain metrics, like completeness, uniqueness, validity, NULLs, consistency, or any custom rule you might need, like the length of the string, etc.
Masthead can integrate your own data quality scans or use [Dataplex](https://cloud.google.com/dataplex/docs/introduction), a native Google Cloud solution, to power and execute the data quality rules, which are, in essence, SQL queries. The following sections detail both options.
## Data scans with Dataplex
[Section titled “Data scans with Dataplex”](#data-scans-with-dataplex)
### What data does Masthead query with Dataplex?
[Section titled “What data does Masthead query with Dataplex?”](#what-data-does-masthead-query-with-dataplex)
None. Masthead doesn’t request permissions, nor does it read or edit client data. You should grant read-only permissions to Dataplex, a Google Cloud native service. Masthead only helps you create and manage rules in Dataplex.
### Is Dataplex available automatically?
[Section titled “Is Dataplex available automatically?”](#is-dataplex-available-automatically)
You can enable this feature with a single click. First, activate the Google Cloud Dataplex API in the connected Google Cloud project. The Masthead UI provides a link to the API under the **Data Quality** tab. Additionally, you must manually create rules for each table you want to monitor. Once you create and schedule the rules, they execute automatically.
#### Which metrics can you monitor using Dataplex?
[Section titled “Which metrics can you monitor using Dataplex?”](#which-metrics-can-you-monitor-using-dataplex)
This depends on each business and the metrics that are crucial for it. Data Quality rules schedule SQL queries to run. There are pre-set rules for aspects like completeness, accuracy, consistency, validity, uniqueness, and null checks.
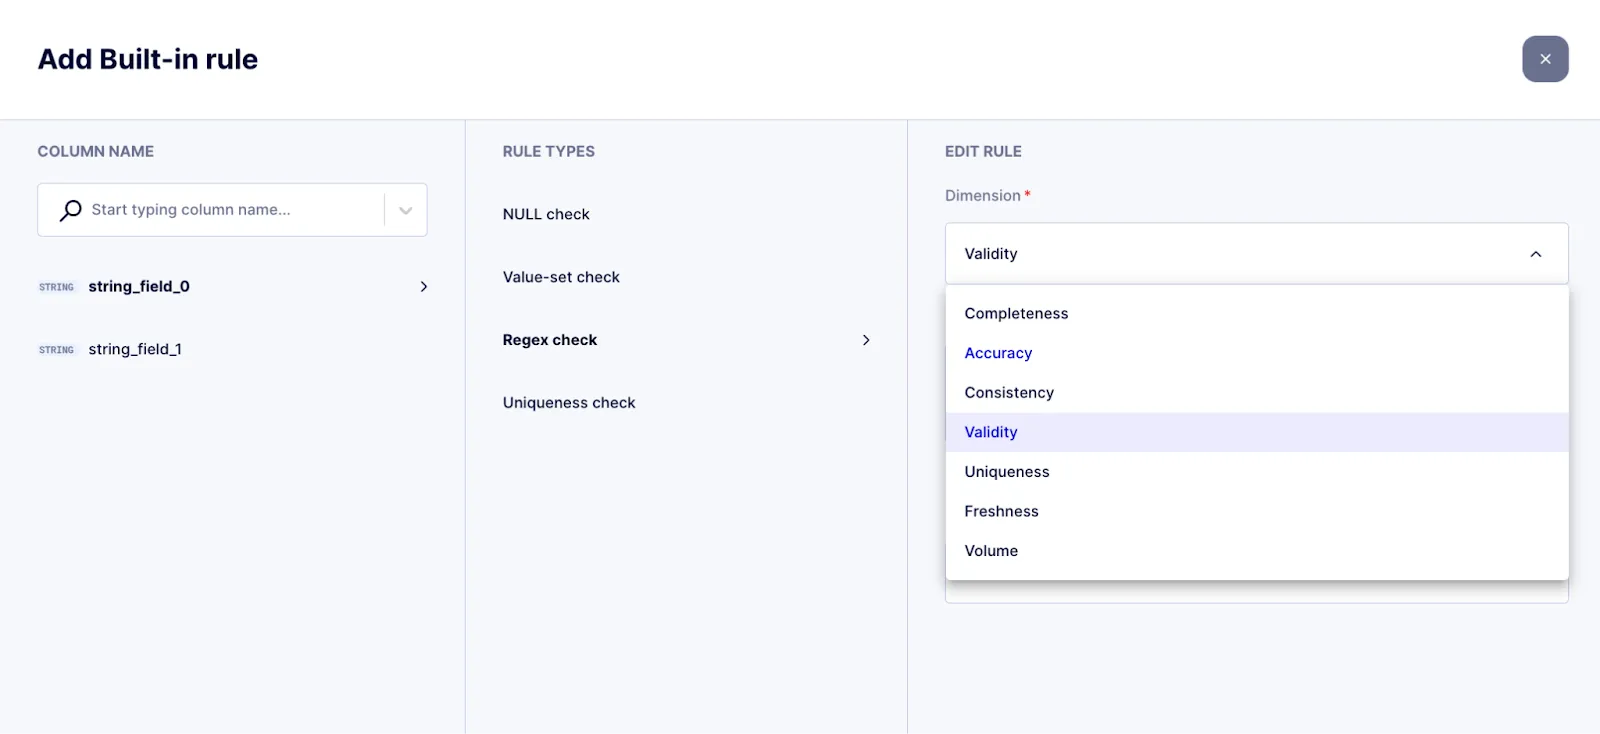
However, you can monitor any metric within any dimension using a custom SQL rule.
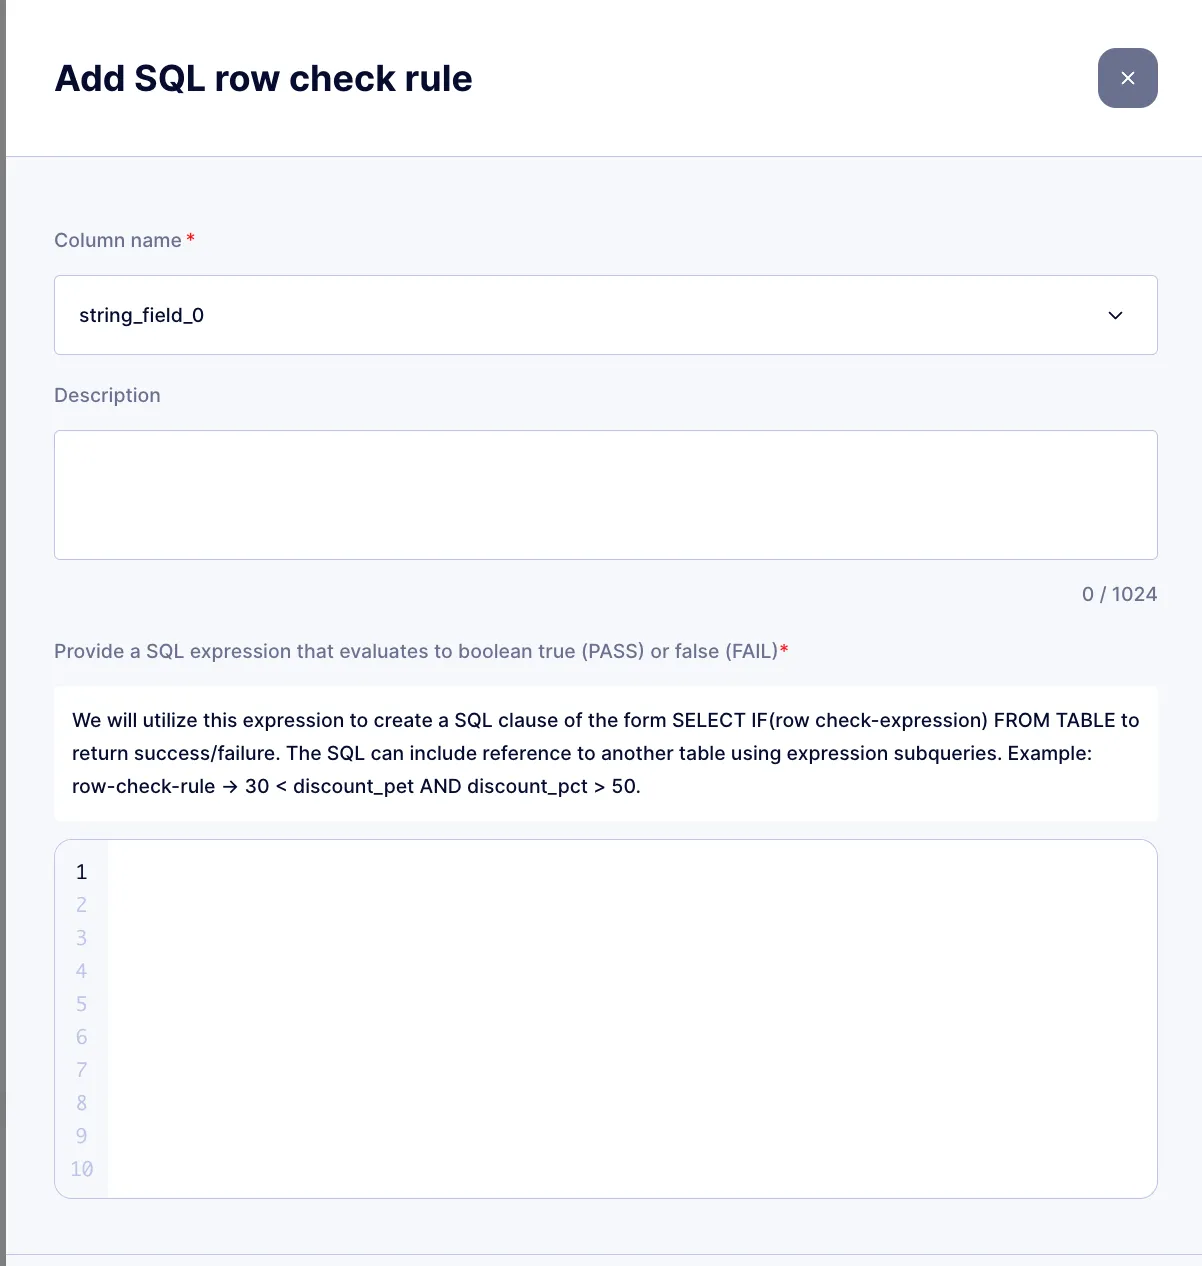
#### Why integrate Masthead with Dataplex?
[Section titled “Why integrate Masthead with Dataplex?”](#why-integrate-masthead-with-dataplex)
Dataplex combined with Masthead Data Quality is a SQL-based solution, in contrast to Masthead Monitors, which rely on logs and metadata. Unlike Dataplex, Masthead Monitors provide automated anomaly detection across the entire data platform by identifying anomalies in time-series tables and errors in pipelines in real-time. Additionally, it doesn’t increase cloud costs because it doesn’t run SQL queries.
Dataplex is the optimal solution for Google Cloud users to implement data quality checks. The benefits include:
* It’s 100x cheaper. Pay only for SQL execution, which helps avoid the 100X additional costs associated with purchasing another SQL-first solution plus to compute costs for executed queries.
* The safest approach. Doesn’t expose data to a third-party vendor, which also eliminates the need to spend time with security and legal teams for onboarding a third-party tool.
* No additional vendor lock-in.
## Custom data scans
[Section titled “Custom data scans”](#custom-data-scans)
Custom data scans bring your own data quality rule checks into Masthead. You publish data quality check results as a BigQuery table that holds one numeric metric per table and period. Masthead reads the table on a schedule, learns the patterns behind every metric, and raises a data quality incident when a value falls outside the forecasted range.
Caution
Custom data scans are available only on `app.mastheadata.com`. The UK region doesn’t support them.
### Set up a data scan
[Section titled “Set up a data scan”](#set-up-a-data-scan)
* **With an AI agent**: The [data scans skill](/developer/ai-agent-skills#data-scans-skill) walks your agent through the setup. It helps you write the metric query and checks it with your credentials. After you confirm each step, it creates the scan table and the scheduled query that keeps it current, grants Masthead access, and creates the scan through the [Masthead MCP server](/developer/mcp/tools#data-scan-tools).
* **By hand**: Create the scan table and its refresh, grant access as the following sections describe, and create the scan with the `create_data_scan` MCP tool.
You can’t create scans in the Masthead UI. Review them on the [Data Quality page](https://app.mastheadata.com/data-quality).
### Table columns
[Section titled “Table columns”](#table-columns)
| Column | Type | Description |
| ----------------- | ---------------------------------------------- | ---------------------------------------------------------------------------------------------------------------- |
| `table_reference` | `STRING` | The monitored table the metric describes, as `project.dataset.table`. Masthead attaches incidents to this table. |
| `rule_name` | `STRING` | The metric name, for example `null_email_percent`. It becomes the incident’s metric name, so keep it stable. |
| `timestamp` | `TIMESTAMP` | The start of the period the value describes, for example `TIMESTAMP_TRUNC(updated_at, DAY)`. |
| `value` | `INT64`, `FLOAT64`, `NUMERIC`, or `BIGNUMERIC` | The metric value. |
* Write one row per `table_reference`, `rule_name`, and period.
* Write a row for every metric in every period, including zero values. Masthead flags a period without a row as missing data.
* Don’t write NULL in any column. Masthead rejects a table whose rows contain NULLs.
* Keep at least 14 days of history. The first run analyzes the last 14 days.
* Express ratios as percentages (0–100) rather than fractions (0–1). Metrics with small values get wide expected ranges.
* Store aggregated metrics only, never raw rows.
### Keep the table current
[Section titled “Keep the table current”](#keep-the-table-current)
Add each closed period to the table before Masthead checks it, for example with a [BigQuery scheduled query](https://cloud.google.com/bigquery/docs/scheduling-queries), dbt, or Dataform. Masthead checks a period after its processing delay ends, so schedule the refresh to finish before then.
Example table that tracks the daily share of customers without an email address:
1. Create the table with the last 30 days of history:
```sql
CREATE TABLE `my-project.masthead_dq.customers_null_email` AS
SELECT
'my-project.crm.customers' AS table_reference,
'null_email_percent' AS rule_name,
TIMESTAMP_TRUNC(updated_at, DAY) AS `timestamp`,
100 * COUNTIF(email IS NULL) / COUNT(*) AS value
FROM `my-project.crm.customers`
WHERE updated_at >= TIMESTAMP(DATE_SUB(CURRENT_DATE(), INTERVAL 30 DAY))
AND updated_at < TIMESTAMP(CURRENT_DATE())
GROUP BY table_reference, rule_name, `timestamp`
```
2. Schedule a query that adds the previous day, once a day after midnight UTC:
```sql
MERGE `my-project.masthead_dq.customers_null_email` AS t
USING (
SELECT
'my-project.crm.customers' AS table_reference,
'null_email_percent' AS rule_name,
TIMESTAMP_TRUNC(updated_at, DAY) AS `timestamp`,
100 * COUNTIF(email IS NULL) / COUNT(*) AS value
FROM `my-project.crm.customers`
WHERE updated_at >= TIMESTAMP(DATE_SUB(CURRENT_DATE(), INTERVAL 1 DAY))
AND updated_at < TIMESTAMP(CURRENT_DATE())
GROUP BY table_reference, rule_name, `timestamp`
) AS s
ON t.table_reference = s.table_reference AND t.rule_name = s.rule_name AND t.`timestamp` = s.`timestamp`
WHEN MATCHED THEN UPDATE SET value = s.value
WHEN NOT MATCHED THEN INSERT ROW
```
### Grant access
[Section titled “Grant access”](#grant-access)
Keep scan tables in a dedicated dataset, for example `masthead_dq`, in the same location as the source data. Masthead reads that dataset only.
Grant the Masthead service account read access to the dataset:
```sql
GRANT `roles/bigquery.dataViewer` ON SCHEMA `my-project.masthead_dq`
TO "serviceAccount:masthead-quality-checks@masthead-prod.iam.gserviceaccount.com";
```
### How scans run
[Section titled “How scans run”](#how-scans-run)
* **Frequency**: hourly, every 6 hours, every 12 hours, or daily.
* **Processing delay**: after a period ends, Masthead waits before checking it, so late data can arrive. The default is half the period, up to 12 hours.
* **Trend and seasonality**: each metric gets its own model. Masthead detects the seasonal cycle, such as a weekly pattern in daily data, once the metric has two full cycles of history.
* **Late and corrected data**: every run rechecks the last 3 periods, so rows that arrive late or get corrected update the result.
* **Adapts over time**: every run retrains the model on recent history (60 days for daily scans), so the expected range follows a metric as it grows or shifts.
* **First run**: starts as soon as you create the scan, analyzes the last 14 days, and doesn’t send notifications. Later anomalies raise data quality incidents that follow your alert settings.
* **Cost**: Masthead pays for the queries that read the scan table. The queries that refresh it run in your project.
### Review results
[Section titled “Review results”](#review-results)
The **Data scans** tab of the [Data Quality page](https://app.mastheadata.com/data-quality) lists every data scan with its latest result. Each scan’s page shows the results per period, metric values against their expected ranges, the scan configuration, and the monitored tables.
[See results](/observability/data-anomaly-detection#data-quality) in the context of your data assets.
## FAQ
[Section titled “FAQ”](#faq)
* **Is data sampling supported?**
Yes, to make data quality checks more cost-efficient. You can filter it like any SQL query, based on data dimensions.
Data Quality with Dataplex has an easy-to-use UI-based setting that allows you to limit the scope and sample the data queried.
* **How much does it cost to run data quality checks?**
Masthead itself doesn’t charge for running data quality checks. Put simply, customers pay only for the execution of rules.
The cost of each data quality check is equivalent to the data processed in BigQuery at the chosen data location and the selected pricing plan for the particular Google Cloud project.
Dataplex charges based on pay-as-you-go usage. The cost to run data quality checks aligns with the [Dataplex premium processing pricing](https://cloud.google.com/dataplex/pricing#dataplex_premium_processing_pricing).
* **After creating a rule in Masthead Data Quality with Dataplex, does it appear in Dataplex in Google Cloud?**
Yes, once you create a rule in Masthead, it appears in the Dataplex UI, and vice versa. You can modify or delete rules created in Masthead within Dataplex at any time.
# Domains
## What’s a domain?
[Section titled “What’s a domain?”](#whats-a-domain)
In Masthead, a domain represents a high-level category to organize and manage related data products. Think of domains as logical groupings that often correspond to specific business areas, subject matters, teams, or strategic initiatives within your organization, such as Finance, Marketing, Product Analytics, or Customer Support.
**Purpose of domains:**
* Clearly assign responsibility for data products to a specific team or group.
* Link domains to specific Slack channels for focused notifications, alerts, and discussions related to the data products within that domain.
* Provide a rolled-up view of key metrics like cost and open incidents for all data products belonging to a domain.
## Create domain
[Section titled “Create domain”](#create-domain)
You can easily define new domains to organize your data products.
### Navigate to domains
[Section titled “Navigate to domains”](#navigate-to-domains)
Go to the **Data Products** section in the menu and click the **Domains** tab. Click **Create** to open the “Create domain” side panel.
### Fill in domain information
[Section titled “Fill in domain information”](#fill-in-domain-information)
Provide a clear and unique **Name** for the domain, such as `Marketing Analytics` or `Core Finance`.
Enter the group **email** address of the team responsible for overseeing the data products within this domain. This ensures clear accountability.
### Assign Slack channel
[Section titled “Assign Slack channel”](#assign-slack-channel)
Select an existing **Slack channel** from the dropdown list if you want domain-specific notifications routed there.
If the desired channel isn’t listed, complete these steps to enable the Slack integration:
1. check that you’ve integrated your Slack Workspace in Integration settings.
2. open the channel, type `/invite @Masthead_data_app` and hit Enter.
Click **Create**
Your newly created domain appears in the list.
## Why use domains?
[Section titled “Why use domains?”](#why-use-domains)
Domains provide significant value beyond simple categorization, particularly for teams responsible for producing, managing, and governing data.
### Efficient communication & collaboration
[Section titled “Efficient communication & collaboration”](#efficient-communication--collaboration)
Linking domains to specific Slack channels creates dedicated communication hubs. Data platform teams can route relevant alerts, such as pipeline failures affecting domain products, to the most relevant audience, which includes the domain owners and key stakeholders. This minimizes noise in broader channels and helps reduce the total time spent analyzing incidents.
### Holistic cost & health monitoring
[Section titled “Holistic cost & health monitoring”](#holistic-cost--health-monitoring)
Domains list view aggregates **Monthly Cost** and **Open Incidents** across all data products within each domain. This gives data teams and leadership a high-level overview of the operational burden and health status per business area, helping to prioritize resources for optimization or reliability improvements where they’re most needed.
By implementing and utilizing domains in Masthead effectively, data teams can enhance accountability, streamline workflows, improve communication, gain better operational insights, and build a more organized and governable data ecosystem.
# Overview
Masthead integrates with various data services to provide enhanced observability, governance, and cost insights for your data ecosystem.
* Google Cloud data platform services:
* [BigQuery](/integrations/bigquery)
* [Dataform](/integrations/dataform)
* [Dataplex](/integrations/dataplex)
* [Analytics Hub](/integrations/analytics-hub)
* Business intelligence services:
* [Looker](/integrations/looker)
* [Power BI](/integrations/power-bi)
* Notification channels
* [Slack](/integrations/notifications/slack)
* [Microsoft Teams](/integrations/notifications/microsoft-teams)
* [Microsoft Teams webhook](/integrations/notifications/microsoft-teams-webhook) (legacy)
* [Google Chat](/integrations/notifications/google-chat)
* [PagerDuty](/integrations/notifications/pagerduty)
* Other services:
* [Jira](/integrations/jira)
# Analytics Hub
Masthead’s Analytics Hub integration helps you manage shared BigQuery data assets and collaborative data sharing. Automatically create Data Products from shared assets and enable prioritized monitoring for critical shared datasets.
After the integration, you can explore the [Data Products](/governance/data-products) created with all corresponding metadata and adjust priority of each data asset on the [Dictionary](https://app.mastheadata.com/dictionary) page.
Note
An account running an installation should have the `Owner` role. Alternatively, you must assign the following roles in the Google Cloud project:
* `Project IAM Admin`
## Connect via OAuth
[Section titled “Connect via OAuth”](#connect-via-oauth)
Open [Integrations](https://app.mastheadata.com/integrations) page.
Click **Connect** button in Analytics Hub section.
Click **Add project**, enter the project ID and choose **Deploy with OAuth** to configure connection.
Note
Masthead doesn’t store OAuth token.
## Connect via Terraform
[Section titled “Connect via Terraform”](#connect-via-terraform)
```hcl
module "masthead-agent" {
source = "masthead-data/masthead-agent/google"
project_id = "YOUR_PROJECT_ID"
# Enable modules for the used services
enable_modules = {
bigquery = true
dataform = true
dataplex = true
analytics_hub = true
}
}
```
More details about the module [on Terraform Registry](https://registry.terraform.io/modules/masthead-data/masthead-agent/google/latest).
Google Cloud resources created:
* [`Analytics Hub Viewer`](https://cloud.google.com/iam/docs/roles-permissions/analyticshub#analyticshub.viewer) role for Masthead service account
# BigQuery
Masthead’s BigQuery integration provides comprehensive data observability, cost optimization, and governance for your core data warehouse. Monitor data pipelines, track costs, and ensure data quality across your BigQuery environment.
Note
An account running an installation should have the `Owner` role. Alternatively, you must assign the following roles in the Google Cloud project:
* [Logging Admin](https://cloud.google.com/iam/docs/roles-permissions/logging#logging.admin): `roles/logging.admin`
* [Pub/Sub Admin](https://cloud.google.com/iam/docs/roles-permissions/pubsub#pubsub.admin): `roles/pubsub.admin`
* [Project IAM Admin](https://cloud.google.com/iam/docs/roles-permissions/resourcemanager#resourcemanager.projectIamAdmin): `roles/resourcemanager.projectIamAdmin`
## Connect via OAuth
[Section titled “Connect via OAuth”](#connect-via-oauth)
Open [Integrations](https://app.mastheadata.com/integrations) page.
Click **Connect** in BigQuery section.
Click **Add project**, choose **Deploy with OAuth** and enter the project ID to configure connection.
Note
Masthead doesn’t store OAuth token.
## Connect via Terraform
[Section titled “Connect via Terraform”](#connect-via-terraform)
```hcl
module "masthead-agent" {
source = "masthead-data/masthead-agent/google"
project_id = "YOUR_PROJECT_ID"
# Enable modules for the used services
enable_modules = {
bigquery = true
dataform = true
dataplex = true
analytics_hub = true
}
}
```
More details about the module [on Terraform Registry](https://registry.terraform.io/modules/masthead-data/masthead-agent/google/latest).
After applying the Terraform configuration, go to [Deployment](https://app.mastheadata.com/deployment) page, click **Verify custom deployment** and enter the project ID to complete the integration.
## What’s next
[Section titled “What’s next”](#whats-next)
After successful integration, Masthead provides comprehensive insights within approx. 20 minutes:
* **Data observability** - Monitor table freshness, pipeline health, and data quality
* **Cost optimization** - Analyze compute and storage costs with actionable recommendations
* **Column-level lineage** - Visualize data flow and dependencies across your warehouse
* **Performance insights** - Identify optimization opportunities for queries and resources
Explore your [Observability Dashboard](https://app.mastheadata.com/observability) to get started.
# Dataform
Masthead’s Dataform integration provides observability across your Dataform action tags. Monitor execution of workflows, track costs, and optimize performance across your Dataform projects.
Note
An account running an installation should have the `Owner` role. Alternatively, you must assign the following roles in the Google Cloud project:
* `Logging Admin`
* `Project IAM Admin`
* `Pub/Sub Admin`
## Connect via OAuth
[Section titled “Connect via OAuth”](#connect-via-oauth)
Open [Integrations](https://app.mastheadata.com/integrations) page.
Click **Connect** in Dataform section.
Click **Add project**, enter the project ID and choose **Deploy with OAuth** to configure connection.
Note
Masthead doesn’t store OAuth token.
## Connect via Terraform
[Section titled “Connect via Terraform”](#connect-via-terraform)
```hcl
module "masthead-agent" {
source = "masthead-data/masthead-agent/google"
project_id = "YOUR_PROJECT_ID"
# Enable modules for the used services
enable_modules = {
bigquery = true
dataform = true
dataplex = true
analytics_hub = true
}
}
```
More details about the module [on Terraform Registry](https://registry.terraform.io/modules/masthead-data/masthead-agent/google/latest).
Google Cloud resources created:
* [`Dataform Viewer`](https://cloud.google.com/iam/docs/roles-permissions/dataform#dataform.viewer) role for the Masthead service account to provide read access to repositories and workflows
* Google Cloud Logging sink for Dataform workflow execution logs
* Pub/Sub topic and subscription for real-time workflow monitoring
## What’s next
[Section titled “What’s next”](#whats-next)
Visit your [Pipeline Observability](https://app.mastheadata.com/pipelines) to monitor Dataform workflows.
# Dataplex
Masthead’s Dataplex integration enables data quality monitoring across your [data assets](/observability/data-dictionary).
Note
An account running an installation should have the `Owner` role. Alternatively, you must assign the following roles in the Google Cloud project:
* `Logging Admin`
* `Project IAM Admin`
* `Pub/Sub Admin`
## Connect via OAuth
[Section titled “Connect via OAuth”](#connect-via-oauth)
Open [Integrations](https://app.mastheadata.com/integrations) page.
Click **Connect** in Dataplex section.
Click **Add project**, enter the project ID and choose **Deploy with OAuth** to configure connection.
Note
Masthead doesn’t store OAuth token.
## Connect via Terraform
[Section titled “Connect via Terraform”](#connect-via-terraform)
```hcl
module "masthead-agent" {
source = "masthead-data/masthead-agent/google"
project_id = "YOUR_PROJECT_ID"
# Enable modules for the used services
enable_modules = {
bigquery = true
dataform = true
dataplex = true
analytics_hub = true
}
}
```
More details about the module [on Terraform Registry](https://registry.terraform.io/modules/masthead-data/masthead-agent/google/latest).
Google Cloud resources created:
* [`Dataplex DataScan Administrator`](https://cloud.google.com/iam/docs/roles-permissions/dataplex#dataplex.dataScanAdmin), [`Dataplex Storage Data Reader`](https://cloud.google.com/iam/docs/roles-permissions/dataplex#dataplex.storageDataReader) and [`BigQuery Job User`](https://cloud.google.com/iam/docs/roles-permissions/bigquery#bigquery.jobUser) roles for Masthead service account
* Google Cloud Logging sink for Dataplex task execution and data quality logs
* Pub/Sub topic and subscription for real-time data quality monitoring
## What’s next
[Section titled “What’s next”](#whats-next)
After successful integration, track data quality scans and rule compliance with **Data quality monitoring**.
Explore [Data Quality Scans](/governance/data-quality-scans) to set up quality monitoring.
# Jira
This guide provides a step-by-step process for integrating Masthead Data with Jira to streamline your data incident management.
Integrating Masthead with Jira automates incident reporting, improves team collaboration, and speeds up resolution times.
## Create integration
[Section titled “Create integration”](#create-integration)
To enable Masthead for Jira, please follow the next steps:
### 1. Configure in Masthead
[Section titled “1. Configure in Masthead”](#1-configure-in-masthead)
Navigate to Masthead’s integration settings and select Jira. Enter your Jira URL and target project key.
### 2. Set up OAuth authorization
[Section titled “2. Set up OAuth authorization”](#2-set-up-oauth-authorization)
Complete the OAuth authorization flow with the following required scopes:
* **View**: `jira-user`, `jira-work` - Allows reading user information and work items
* **Update**: `jira-work` - Allows creating and updating Jira issues
### 3. Test connection
[Section titled “3. Test connection”](#3-test-connection)
Create a test incident in Masthead and use the integration to push it to Jira. Verify that the integration creates the Jira issue and populates all fields as expected.
Jira integration configuration is complete.
## Manage incidents in Jira
[Section titled “Manage incidents in Jira”](#manage-incidents-in-jira)
When Masthead detects a data incident, click the **Push to Jira** button on the incident widget. You can customize the following fields:
* **Project**: Select the target Jira project
* **Issue Type**: Choose the appropriate issue type for the incident
* **Summary**: Auto-suggested based on the incident context. You can edit this field.
* **Description**: Auto-suggested based on the incident context. You can edit this field.
* **Reporter**: Set the user who appears as the reporter.
Click **Create** to push the incident to Jira.
The integration creates the incident in Jira with all the specified details on behalf of the user.
After that, the appropriate team can timely start analyzing and resolving the data issue without any back-and-forth messages needed for problem clarification. This allows you to speed up task delivery and distribution, as well as helps you process the problem in the shortest terms.
Once the Masthead creates the Jira ticket, you can check its number and status until the team resolves the ticket. This ensures everyone on the team knows who is handling the data issue and understands its progress.
# Looker
[Column-level lineage](/observability/lineage) and details in [data dictionary](/observability/data-dictionary) become available within 15-20 minutes after integration.
## Create integration
[Section titled “Create integration”](#create-integration)
To enable Masthead for Looker, please follow the next steps:
### Create a permission set
[Section titled “Create a permission set”](#create-a-permission-set)
* In the navigation bar go to **Admin > Roles** and click **New Permission Set**.
* Name your permission set `masthead_permissions`.
* Select the necessary permissions:
```text
access_data
access_data.see_lookml_dashboards
access_data.see_looks
access_data.see_looks.see_user_dashboards
access_data.see_looks.explore
access_data.see_looks.see_lookml
see_system_activity
```
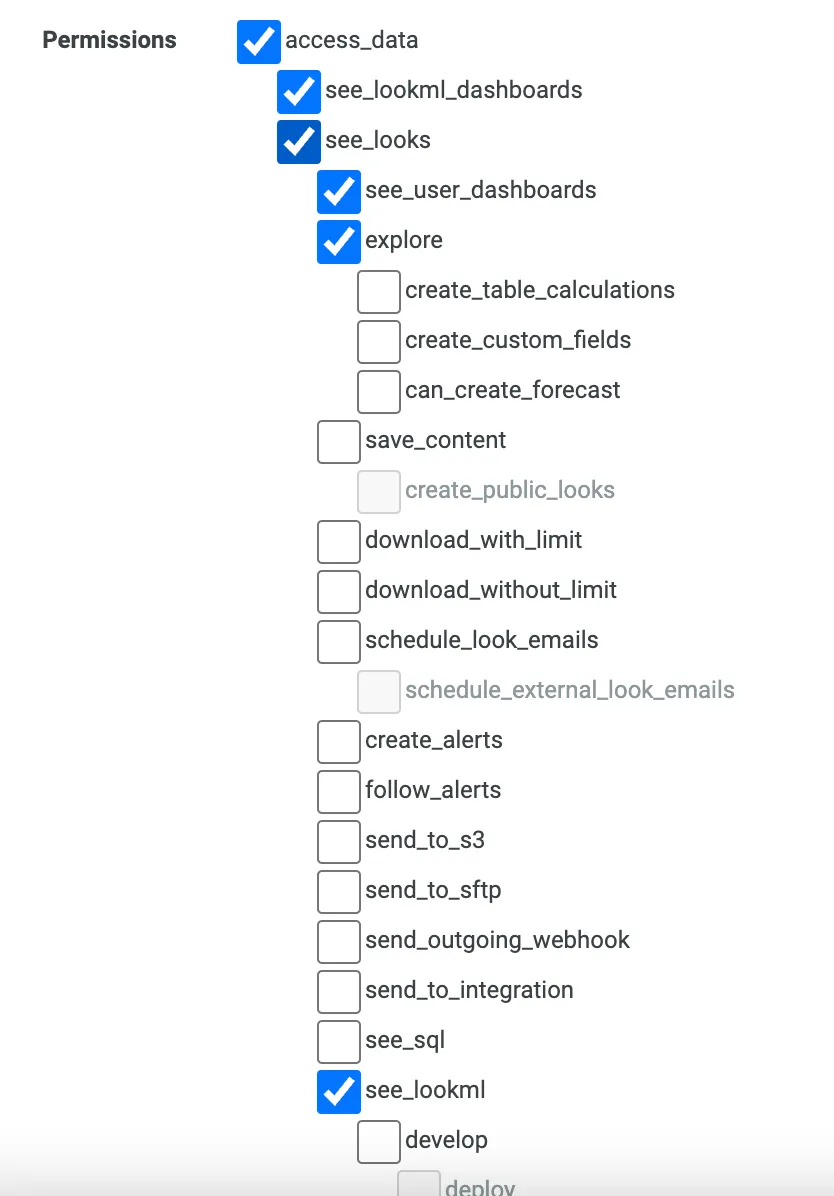
Looker permissions
* Click **New Permission Set** to save.
### Create a role
[Section titled “Create a role”](#create-a-role)
* Go to **Admin > Roles** and click **New Role**.
* Name a new role `masthead_role`.
* Select the permission set `masthead_permissions`.
* Select a model set `All`.
* Click **New Role** to save.
### Create a user and save API credentials
[Section titled “Create a user and save API credentials”](#create-a-user-and-save-api-credentials)
* Go to **Admin > Users** and click **Add** -> **Service Account**.
* Enter a *Service Account Name* to `masthead_service_account`.
* Toggle **Create default set of API credentials** option ON.
* Select the role `masthead_role`.
* Click **Save**.
* Click **Edit Keys** and copy *Client ID* and *Client Secret* values.
### Check content read access for a Masthead user
[Section titled “Check content read access for a Masthead user”](#check-content-read-access-for-a-masthead-user)
You can decide which folders to give access to.
* Go to **Admin > Content Access**.
* Select the *Shared* folder and click **Manage Access**. Check that the *All Users* group already has *View* or *Manage/Edit Access*.
* Click **Save**.
* Repeat with the *Users* and other folders.
Note
If your Looker instance has restricted content access, you may need to add the `masthead_service_account` user to specific folders.
Create a group, add the Masthead user to it, and give the group *View* access to the necessary folders.
### Completing Looker integration configuration
[Section titled “Completing Looker integration configuration”](#completing-looker-integration-configuration)
* Open [Integrations](https://app.mastheadata.com/integrations) page in Masthead and click **Connect** for Looker.
* Enter *Host URL and port* - address of your Looker instance.
* Enter *Client ID* and *Client Secret* you’ve copied in the previous step.
* Click **Save**.
Looker integration configuration is complete.
# Google Chat
> Install the Masthead Data app in Google Chat to receive and triage incident alerts
The Masthead Data app for Google Chat delivers incident alerts to your Google Chat spaces and lets your team triage them without leaving Chat: mark an incident as fixed, or mute a table or a pipeline directly from the alert message.
## Before you start
[Section titled “Before you start”](#before-you-start)
| Requirement | Details |
| -------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Masthead account** | Access to the **Integrations** page. |
| **Google Chat** | A Google Workspace account with permission to add apps to a space. If your organization restricts app installation, a Google Workspace administrator allows the app first. Personal Google accounts aren’t supported. |
| **Scope** | One Google Workspace organization connects to one Masthead account. Within that organization you can connect as many spaces as you need. |
## Install and connect the app
[Section titled “Install and connect the app”](#install-and-connect-the-app)
1. **Start from Masthead**
Open the [Integrations](https://app.mastheadata.com/integrations) page, select **Google Chat**, and click **Connect**. Masthead opens the Masthead Data app page in the Google Workspace Marketplace.
2. **Add the app to a space**
Click **Install** and follow the prompts. Then open the space in Google Chat that should receive alerts, click the space name, select **Apps & integrations** > **Add apps**, search for **Masthead Data**, and click **Add**. The app joins the space and posts its setup message there.
3. **Complete the setup**
In the *Connect Masthead Data to your organization* card, click **Complete setup**. The link opens Masthead and connects your Google Workspace organization to your Masthead account. The app confirms in the space with a *Setup complete* card.
4. **Setup a notification space**
Every connected space gets its own settings block on the Masthead integration page. Select notification settings and click **Save**.
Tip
The setup card goes to the space you add the app to. If you lose it, remove the app from the space and add it again—the app posts a new card. Type `/help` in the space, or send `help` to the app in a direct message, at any time to see these steps.
## Connect additional spaces
[Section titled “Connect additional spaces”](#connect-additional-spaces)
The connection belongs to your Google Workspace organization, not to a single space. Add the app to any other space the same way. The app posts a *Masthead Data is connected* card instead of the setup card.
Every added space appears on the Masthead integration page with its own settings block and its own policy. You don’t need any additional setup.
## Manage the integration
[Section titled “Manage the integration”](#manage-the-integration)
| Task | Where | Effect |
| ---------------------- | ------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------ |
| Pause one space | **Disable** on the space block in Masthead | The space stops receiving alerts and Masthead hides its policy settings. **Enable** brings them back unchanged. |
| Pause the organization | **Disable** on the organization block in Masthead | Every space stops receiving alerts. The app stays installed in Google Chat. **Enable** restores all spaces and their settings. |
| Remove one space | Remove the app from that space in Google Chat | The space disappears from Masthead. Its policy returns if you add the app to that space again. |
| Remove the integration | Remove the app from every space in Google Chat | The organization disconnects from Masthead. |
# Microsoft Teams
> Install the Masthead Data app in Microsoft Teams to receive and triage incident alerts
The Masthead Data app for Microsoft Teams delivers incident alerts to your Teams channels and lets your team triage them without leaving Teams: mark an incident as fixed, or mute a table or a pipeline directly from the alert message.
## Before you start
[Section titled “Before you start”](#before-you-start)
| Requirement | Details |
| -------------------- | -------------------------------------------------------------------------------------------------------------------------------------- |
| **Masthead account** | Access to the **Integrations** page. |
| **Microsoft Teams** | Permission to add apps to a team. If your organization restricts app installation, an IT administrator approves the app first. |
| **Scope** | One Microsoft Entra organization connects to one Masthead account. Within that organization you can connect as many teams as you need. |
## Install and connect the app
[Section titled “Install and connect the app”](#install-and-connect-the-app)
1. **Start from Masthead**
Open the [Integrations](https://app.mastheadata.com/integrations) page, select **Microsoft Teams**, and click **Connect**. Masthead opens the Masthead Data app page in the Microsoft Teams store.
2. **Add the app to a team**
Click **Add**. If your organization requires administrator approval, Teams shows **Request approval** instead—send the request and continue after your administrator approves the app.
Teams then shows the *Added successfully* dialog. Under **Or choose a place to use the app**, select a channel from the list and click **Go**. The app joins the team that owns the selected channel and posts its setup message there.
3. **Complete the setup**
In the *Connect Masthead Data to your organization* card, click **Complete setup**. The link opens Masthead and connects your Microsoft Entra organization to your Masthead account.
4. **Setup a notification channel**
Every connected team gets its own settings block on the Masthead integration page. Select a **Channel**, notification settings and click **Save**.
Tip
The setup card goes to the channel you pick during installation. If you lose it, remove the app from the team and add it again—the app posts a new card.
## Connect additional Teams
[Section titled “Connect additional Teams”](#connect-additional-teams)
The connection belongs to your Microsoft Entra organization, not to a single team. Add the app to any other team the same way, or from Teams directly by selecting **Manage team** > **Apps** > **More apps**, and searching for **Masthead Data**.
Every added team appears on the Masthead integration page with its own settings block and its own notification channel. You don’t need any additional setup.
## Manage the integration
[Section titled “Manage the integration”](#manage-the-integration)
| Task | Where | Effect |
| ---------------------- | ------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------- |
| Pause one team | **Disable** on the team block in Masthead | The team stops receiving alerts and Masthead hides its channel settings. **Enable** brings them back unchanged. |
| Pause the organization | **Disable** on the organization block in Masthead | Every team stops receiving alerts. The app stays installed in Teams. **Enable** restores all teams and their settings. |
| Remove one team | Remove the app from that team in Teams | The team disappears from Masthead. Its channel settings return if you add the app to that team again. |
| Remove the integration | Remove the app from every team in Teams | The organization disconnects from Masthead. |
# Microsoft Teams webhook
> Legacy Microsoft Teams integration that pushes Masthead Data alerts through a Workflows webhook
Legacy integration
Webhook notifications are the legacy way to get Masthead alerts in Microsoft Teams. Messages are read-only: you can’t mark an incident as fixed or mute a table or a pipeline from them. Install the [Microsoft Teams app](/integrations/notifications/microsoft-teams) instead.
Masthead utilizes webhooks with Workflows for Microsoft Teams to push alerts to Microsoft Teams channel.
## Create integration
[Section titled “Create integration”](#create-integration)
To connect Masthead to Microsoft Teams:
1. Click the **More options** icon, represented by three dots, to expand the context menu next to the channel where you want to receive alerts.
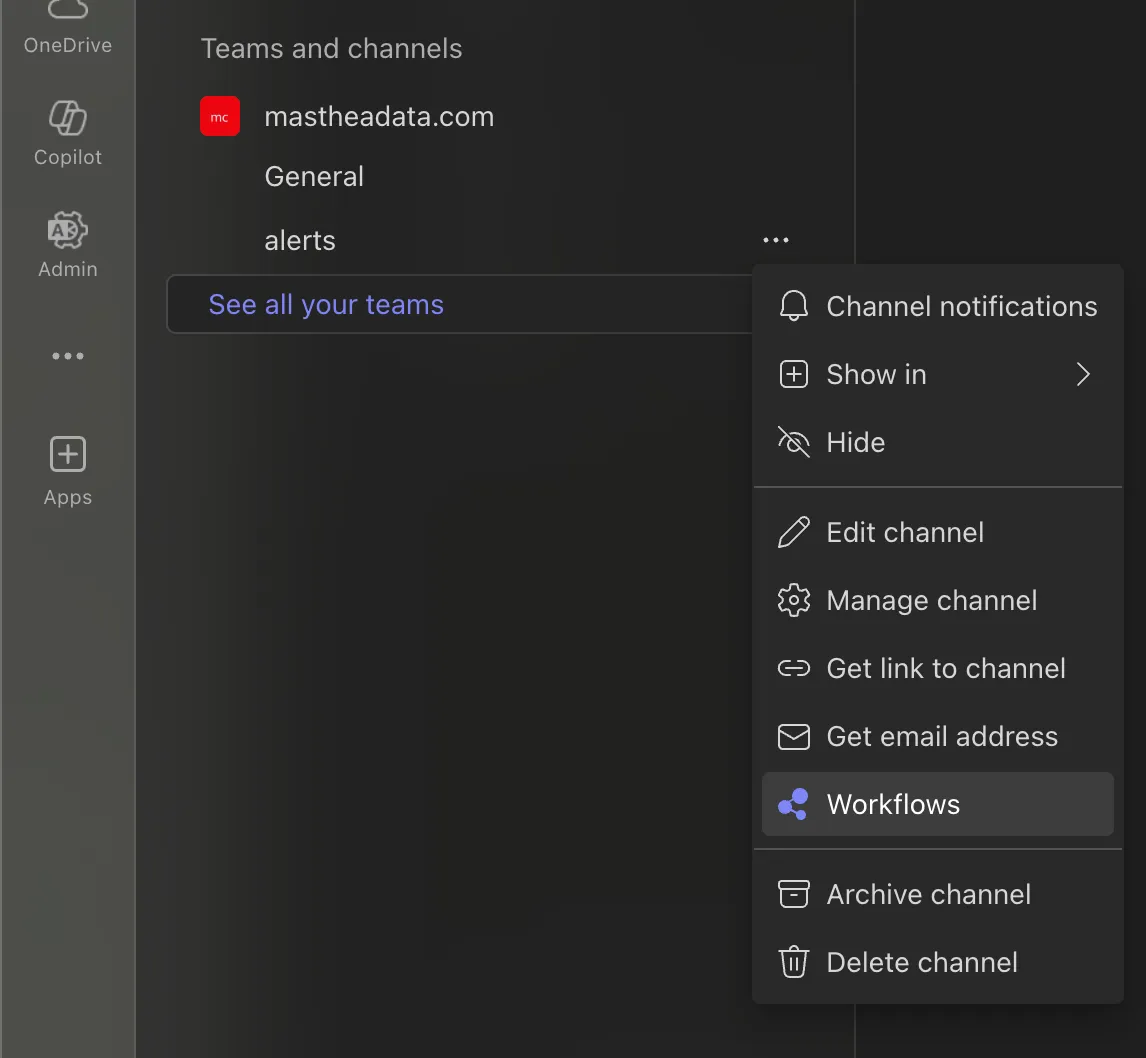
2. Search for “webhook” and select **Send webhook alerts to a channel**.
3. Click **Next** on the following screen.
4. Verify the channel details and click **Add workflow**.
Note
The webhook works by default for public and shared channels. If you want to use it in a private channel, you need to install the Workflows app to that channel first. To do this, click **More options**, represented by three dots, next to the channel name, select **Manage team** > **Apps** > **More apps**, and search for **Workflows**. After installing the app, you can proceed with the preceding steps.
5. Copy the resulting webhook URL into clipboard and click **Done**.
6. In Masthead open the [Integrations](https://app.mastheadata.com/integrations) page and in the Microsoft Teams widget click **Connect**. Enter the webhook URL copied from the previous step and **Save** the connection.
Note
If you need to copy the workflow URL again in Microsoft Teams, you can find it by opening the Workflows app within Teams, selecting the workflow you created, selecting **Edit**, and expanding the trigger **When a Teams webhook request is received**.
# PagerDuty
## Create integration
[Section titled “Create integration”](#create-integration)
To push anomalies into PagerDuty please complete the following steps to connect Masthead to PagerDuty service:
1. From the navigation menu click **Integrations**.
2. In the **PagerDuty** integration widget, click **Connect**. This redirects you to your PagerDuty account.
1. Sign in to your PagerDuty app. Choose the services from the dropdown list that you want to connect with Masthead.
1. Masthead connects to PagerDuty.
## Severity mapping
[Section titled “Severity mapping”](#severity-mapping)
| Masthead severity | PagerDuty severity |
| ----------------- | ------------------ |
| Critical | Critical |
| Priority | Error |
| Regular | Warning |
If you need help with this integration, please contact [support](/resources/support)
# Slack
> Integration of Masthead Data notifications with Slack
Get incident notifications and manage the resolution status from your Slack workspace.
## Create an integration
[Section titled “Create an integration”](#create-an-integration)
### 1. Start the integration
[Section titled “1. Start the integration”](#1-start-the-integration)
Go to [Integrations](https://app.mastheadata.com/integrations) page and click **Connect** for Slack integration.
### 2. Sign in to your Slack workspace
[Section titled “2. Sign in to your Slack workspace”](#2-sign-in-to-your-slack-workspace)
Slack might ask you to [sign in](https://slack.com/help/articles/212681477-Sign-in-to-Slack) and select the workspace you need if you have access to multiple workspaces.
### 3. Allow access
[Section titled “3. Allow access”](#3-allow-access)
The screen appears where you select a default channel from the drop-down list and click **Allow** to enable access for the Masthead Data app.
### 4. Slack app confirmation by workspace administrator
[Section titled “4. Slack app confirmation by workspace administrator”](#4-slack-app-confirmation-by-workspace-administrator)
If you don’t have administration permissions for the workspace, you may need to wait for the administrator’s approval before you can proceed.
You receive a notification in the Slack workspace as soon as the administrator approves the app and makes it available.
### 5. Add default notification channel for the account
[Section titled “5. Add default notification channel for the account”](#5-add-default-notification-channel-for-the-account)
To connect Masthead Data App to a channel you need to:
* open the channel, type `/invite @masthead_data` and hit `Enter`.
Or alternatively, go to channel settings, select tab **Integrations**. In the Apps section click **Add Apps**. In the list of apps in your workspace you should be able to find Masthead Data. Click **Add**.
A message appears in the channel:
> *username* added **Masthead Data** to #*channel*.
The first channel with the Masthead app added serves as the default notification channel for your account.
You have completed the Slack integration.
You can assign Slack channels for notifications at the account level to act as a default channel, or at the domain level, depending on the scope of data assets you want to watch.
## Personal notification in Slack
[Section titled “Personal notification in Slack”](#personal-notification-in-slack)
You can also customize personal notifications in your **Slack app** -> **Apps** -> **Masthead Data** -> **Notification Settings**:
The messages appear on the **Messages** tab.
## Notification message features
[Section titled “Notification message features”](#notification-message-features)
* Messages related to critical data assets mention `@channel`.
* You can archive an incident by clicking **Archive**.
* You can mute notifications for a pipeline or a table if you’re aware of some expected pattern changes, just click **Mute pipeline** or **Mute table** and select the timeframe.
# Power BI
To connect Masthead to your Power BI instance, you need to create a service principal and grant it Power BI Admin API access, allowing the Masthead app to access Power BI.
[Lineage](/observability/lineage) and details in [data dictionary](/observability/data-dictionary) become available within 15-20 minutes after integration.
## Create integration
[Section titled “Create integration”](#create-integration)
There are 4 steps to integrate Masthead to Power BI:
### Create a service principal app in Azure
[Section titled “Create a service principal app in Azure”](#create-a-service-principal-app-in-azure)
1. Log in to the Azure Portal, and search for and select **App Registrations**.
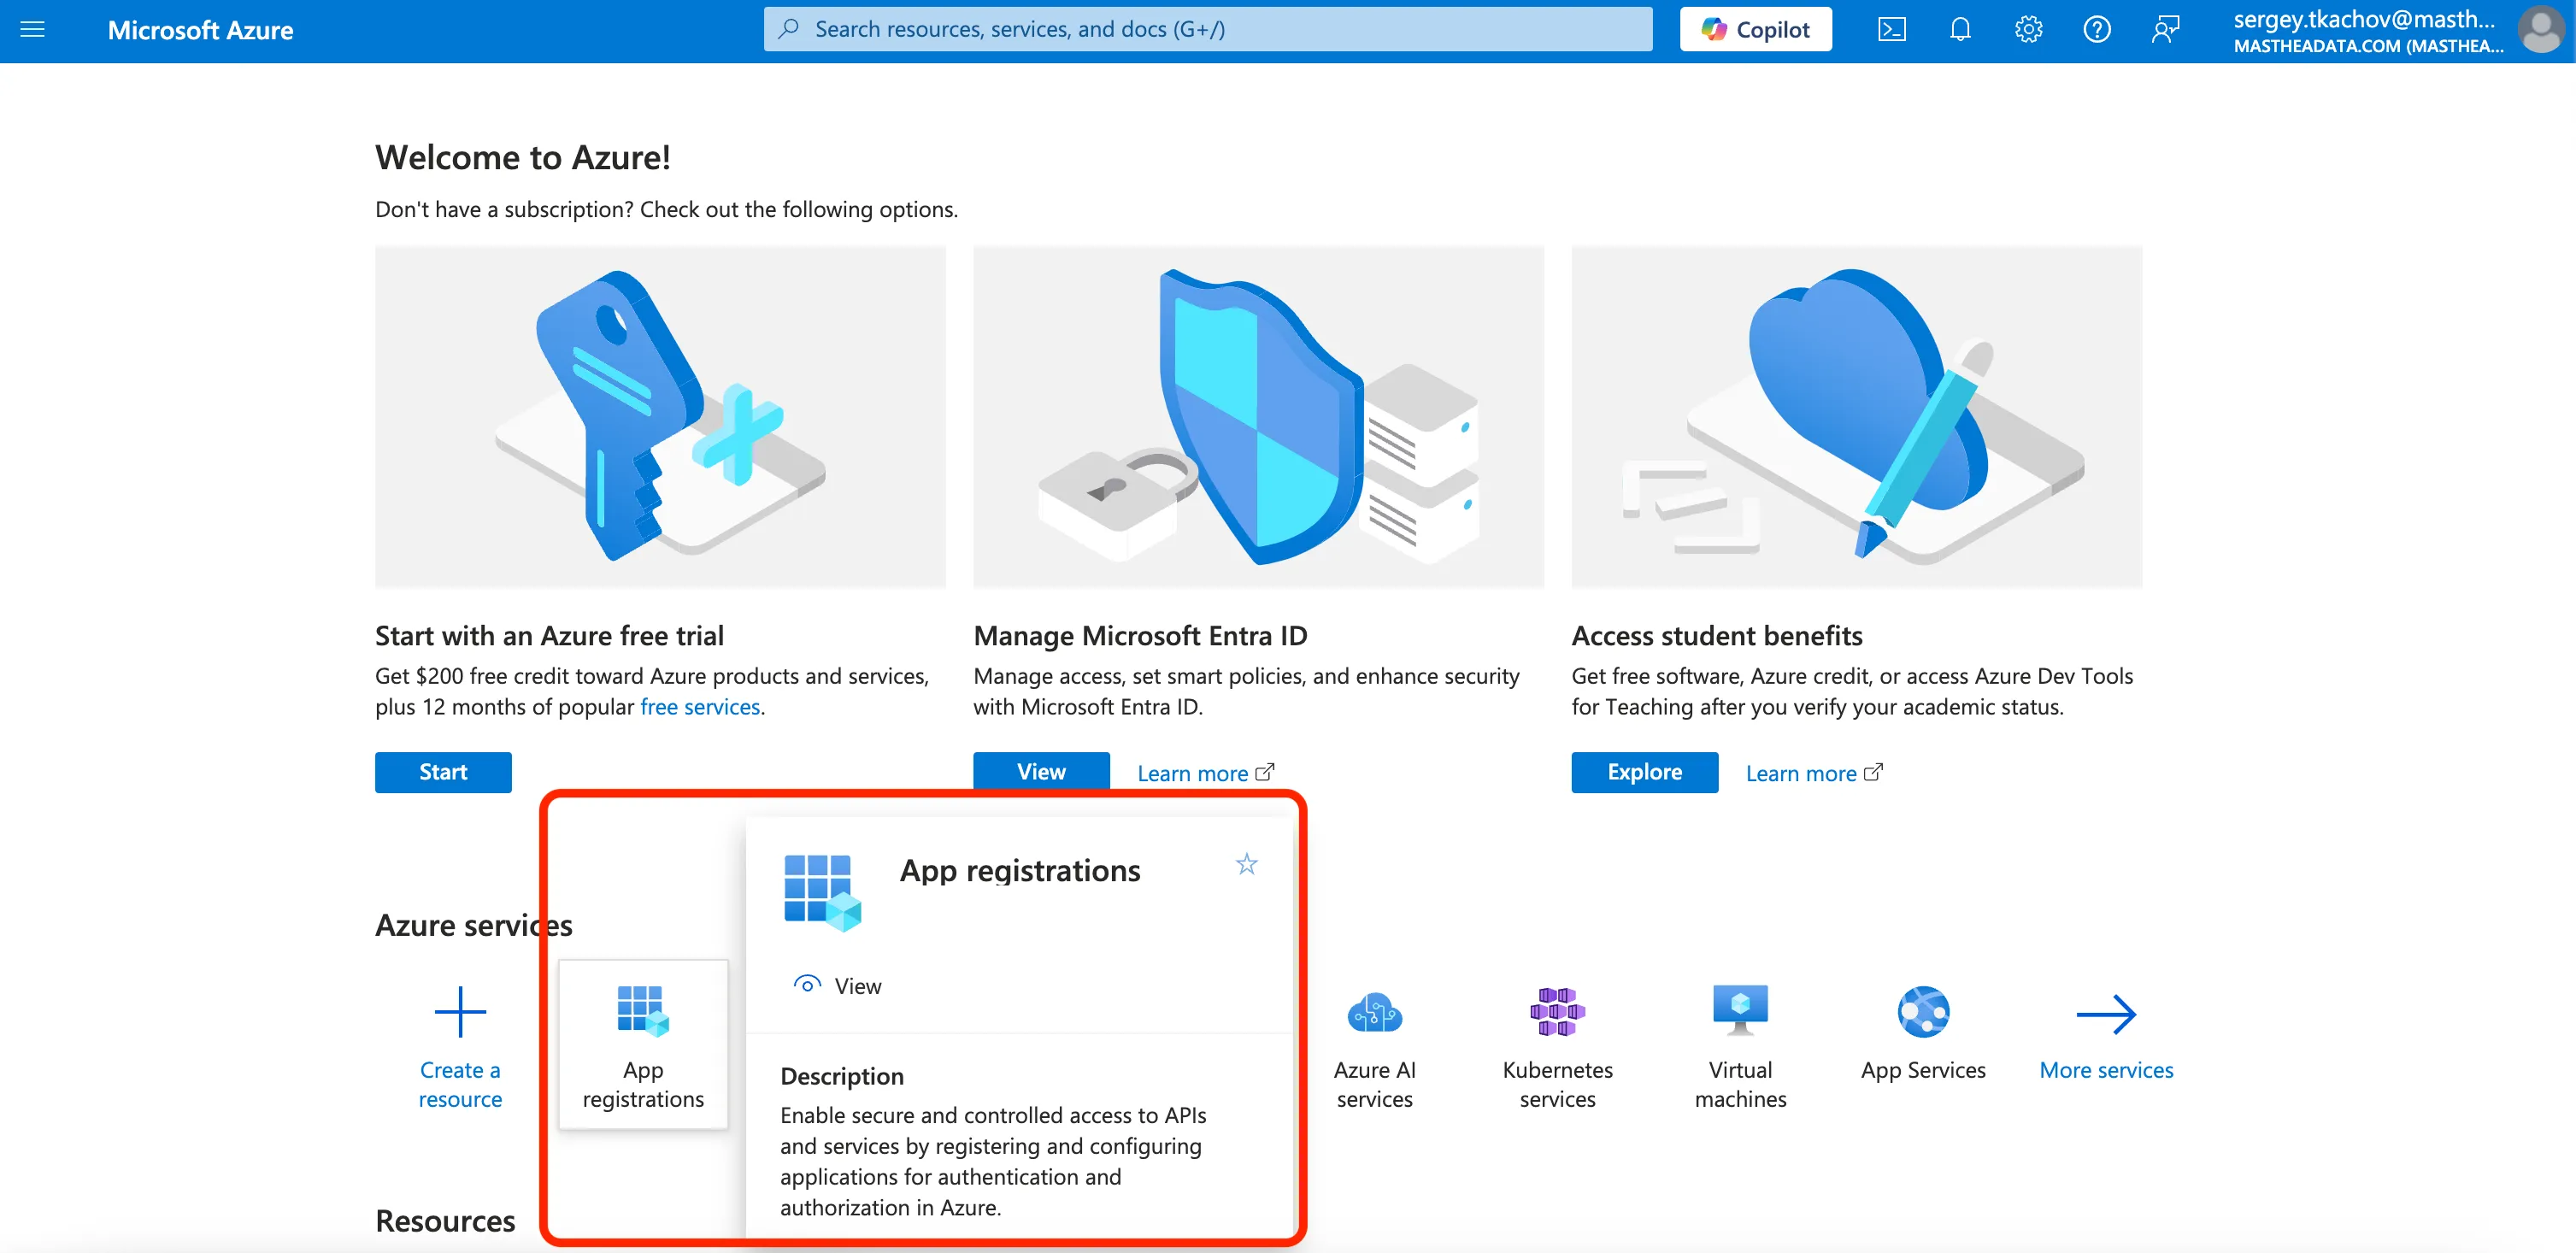
2. Click **New Registration**.
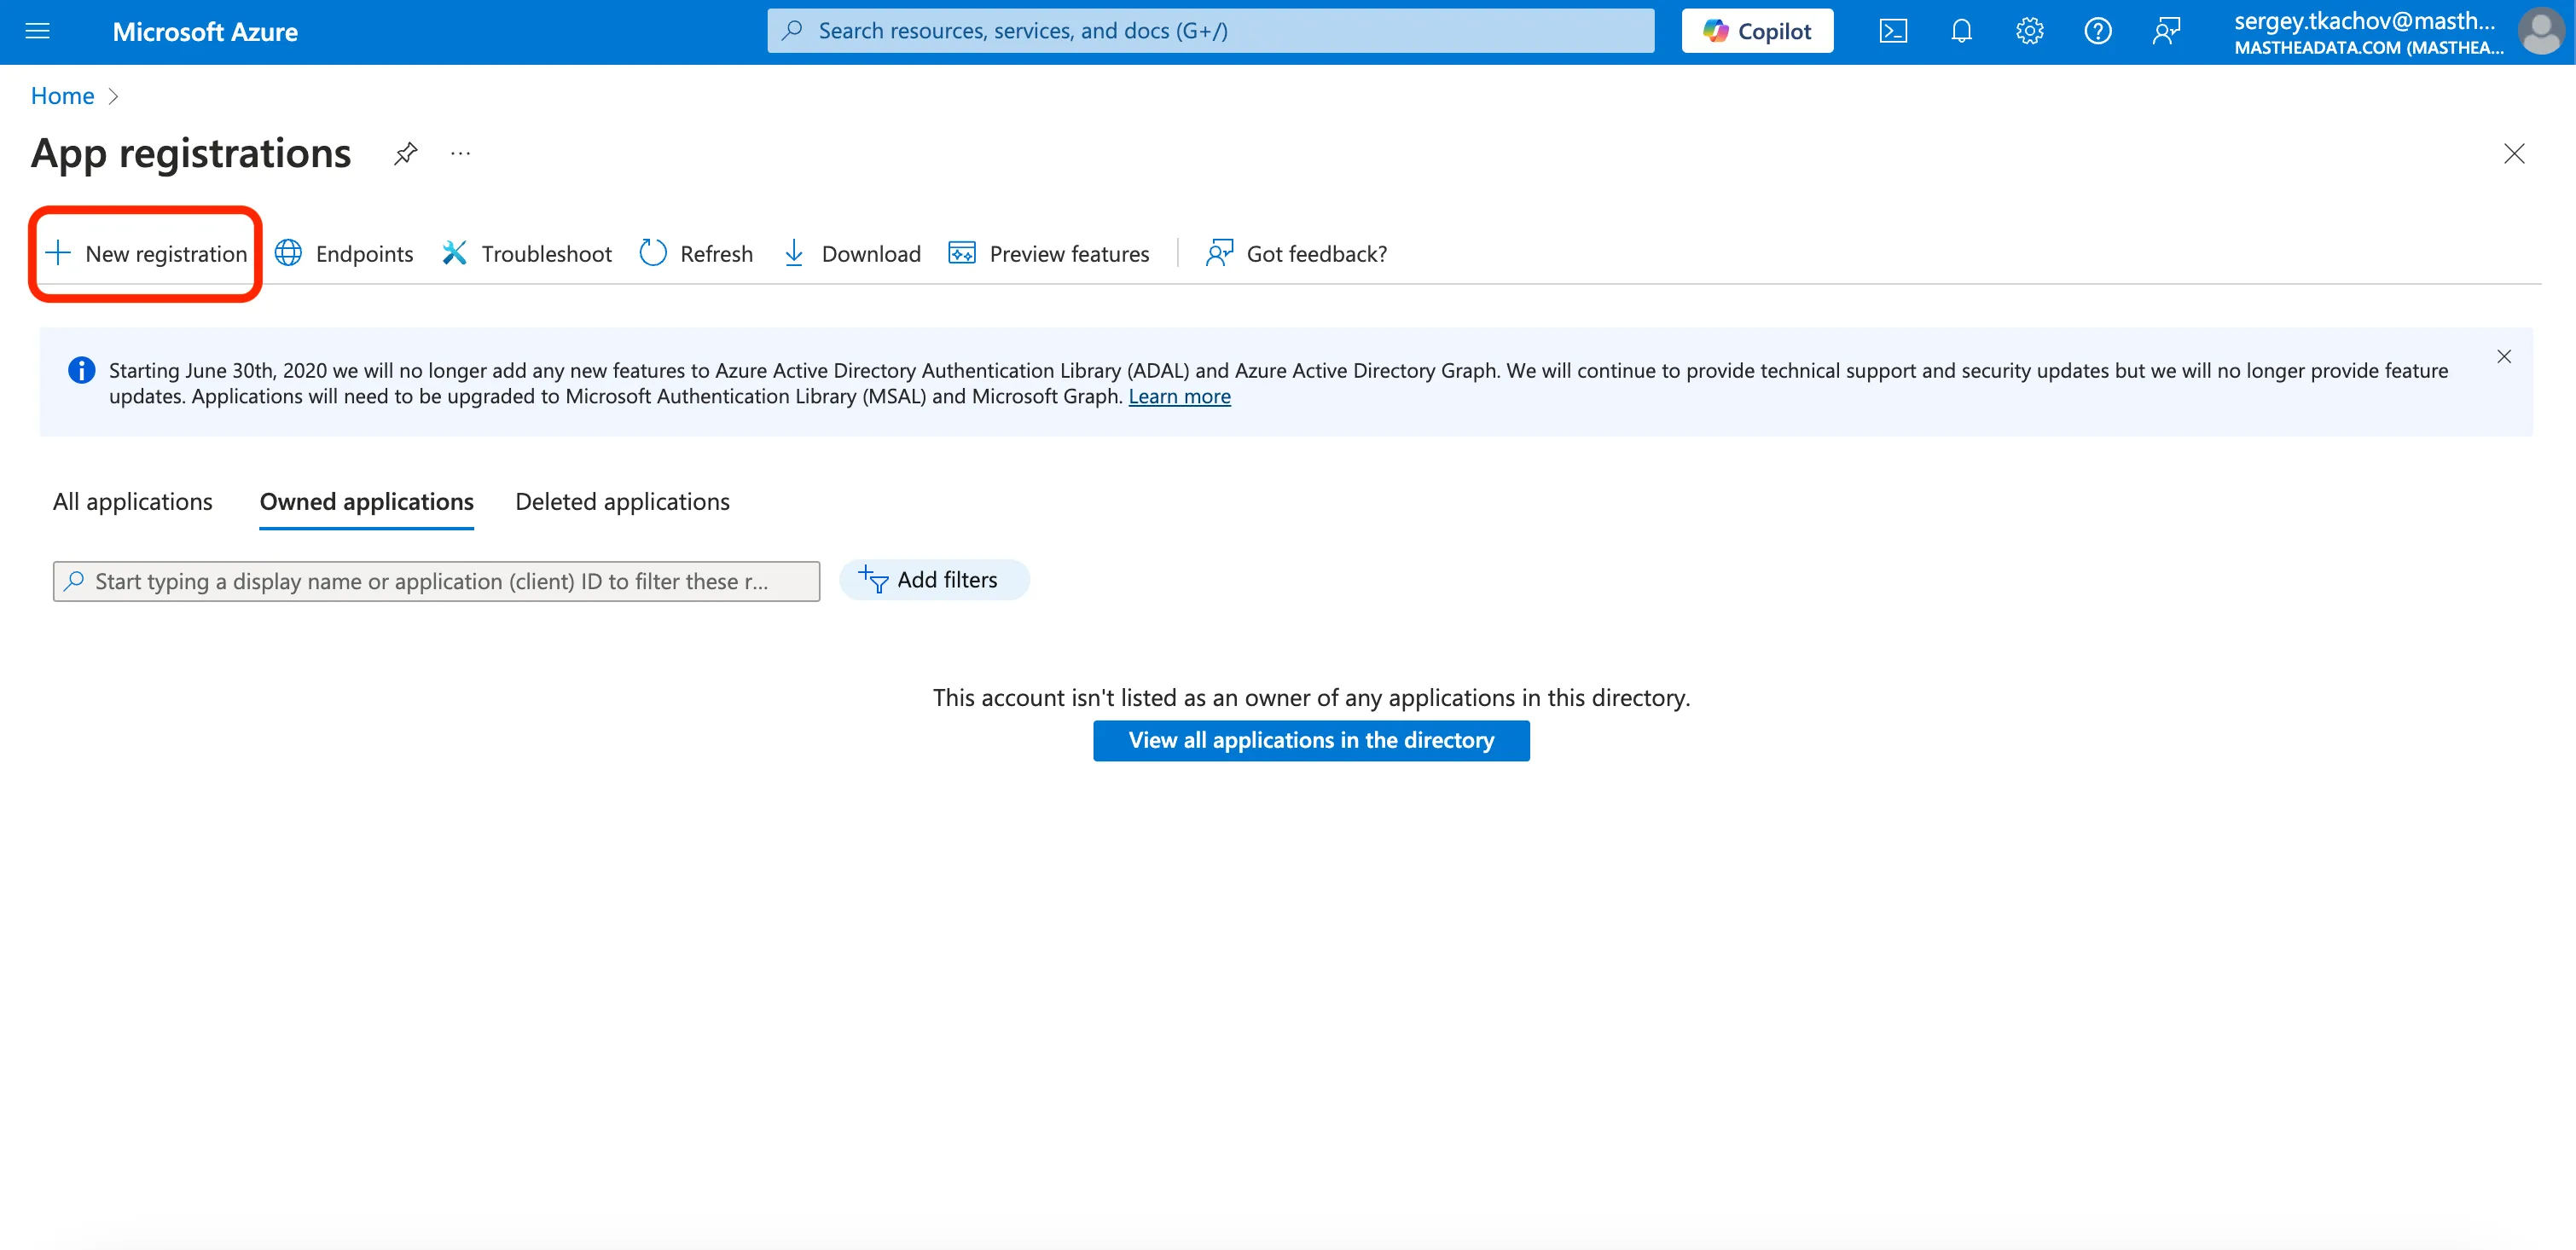
3. Name registration `masthead-powerbi-integration-app`. Click **Register**.
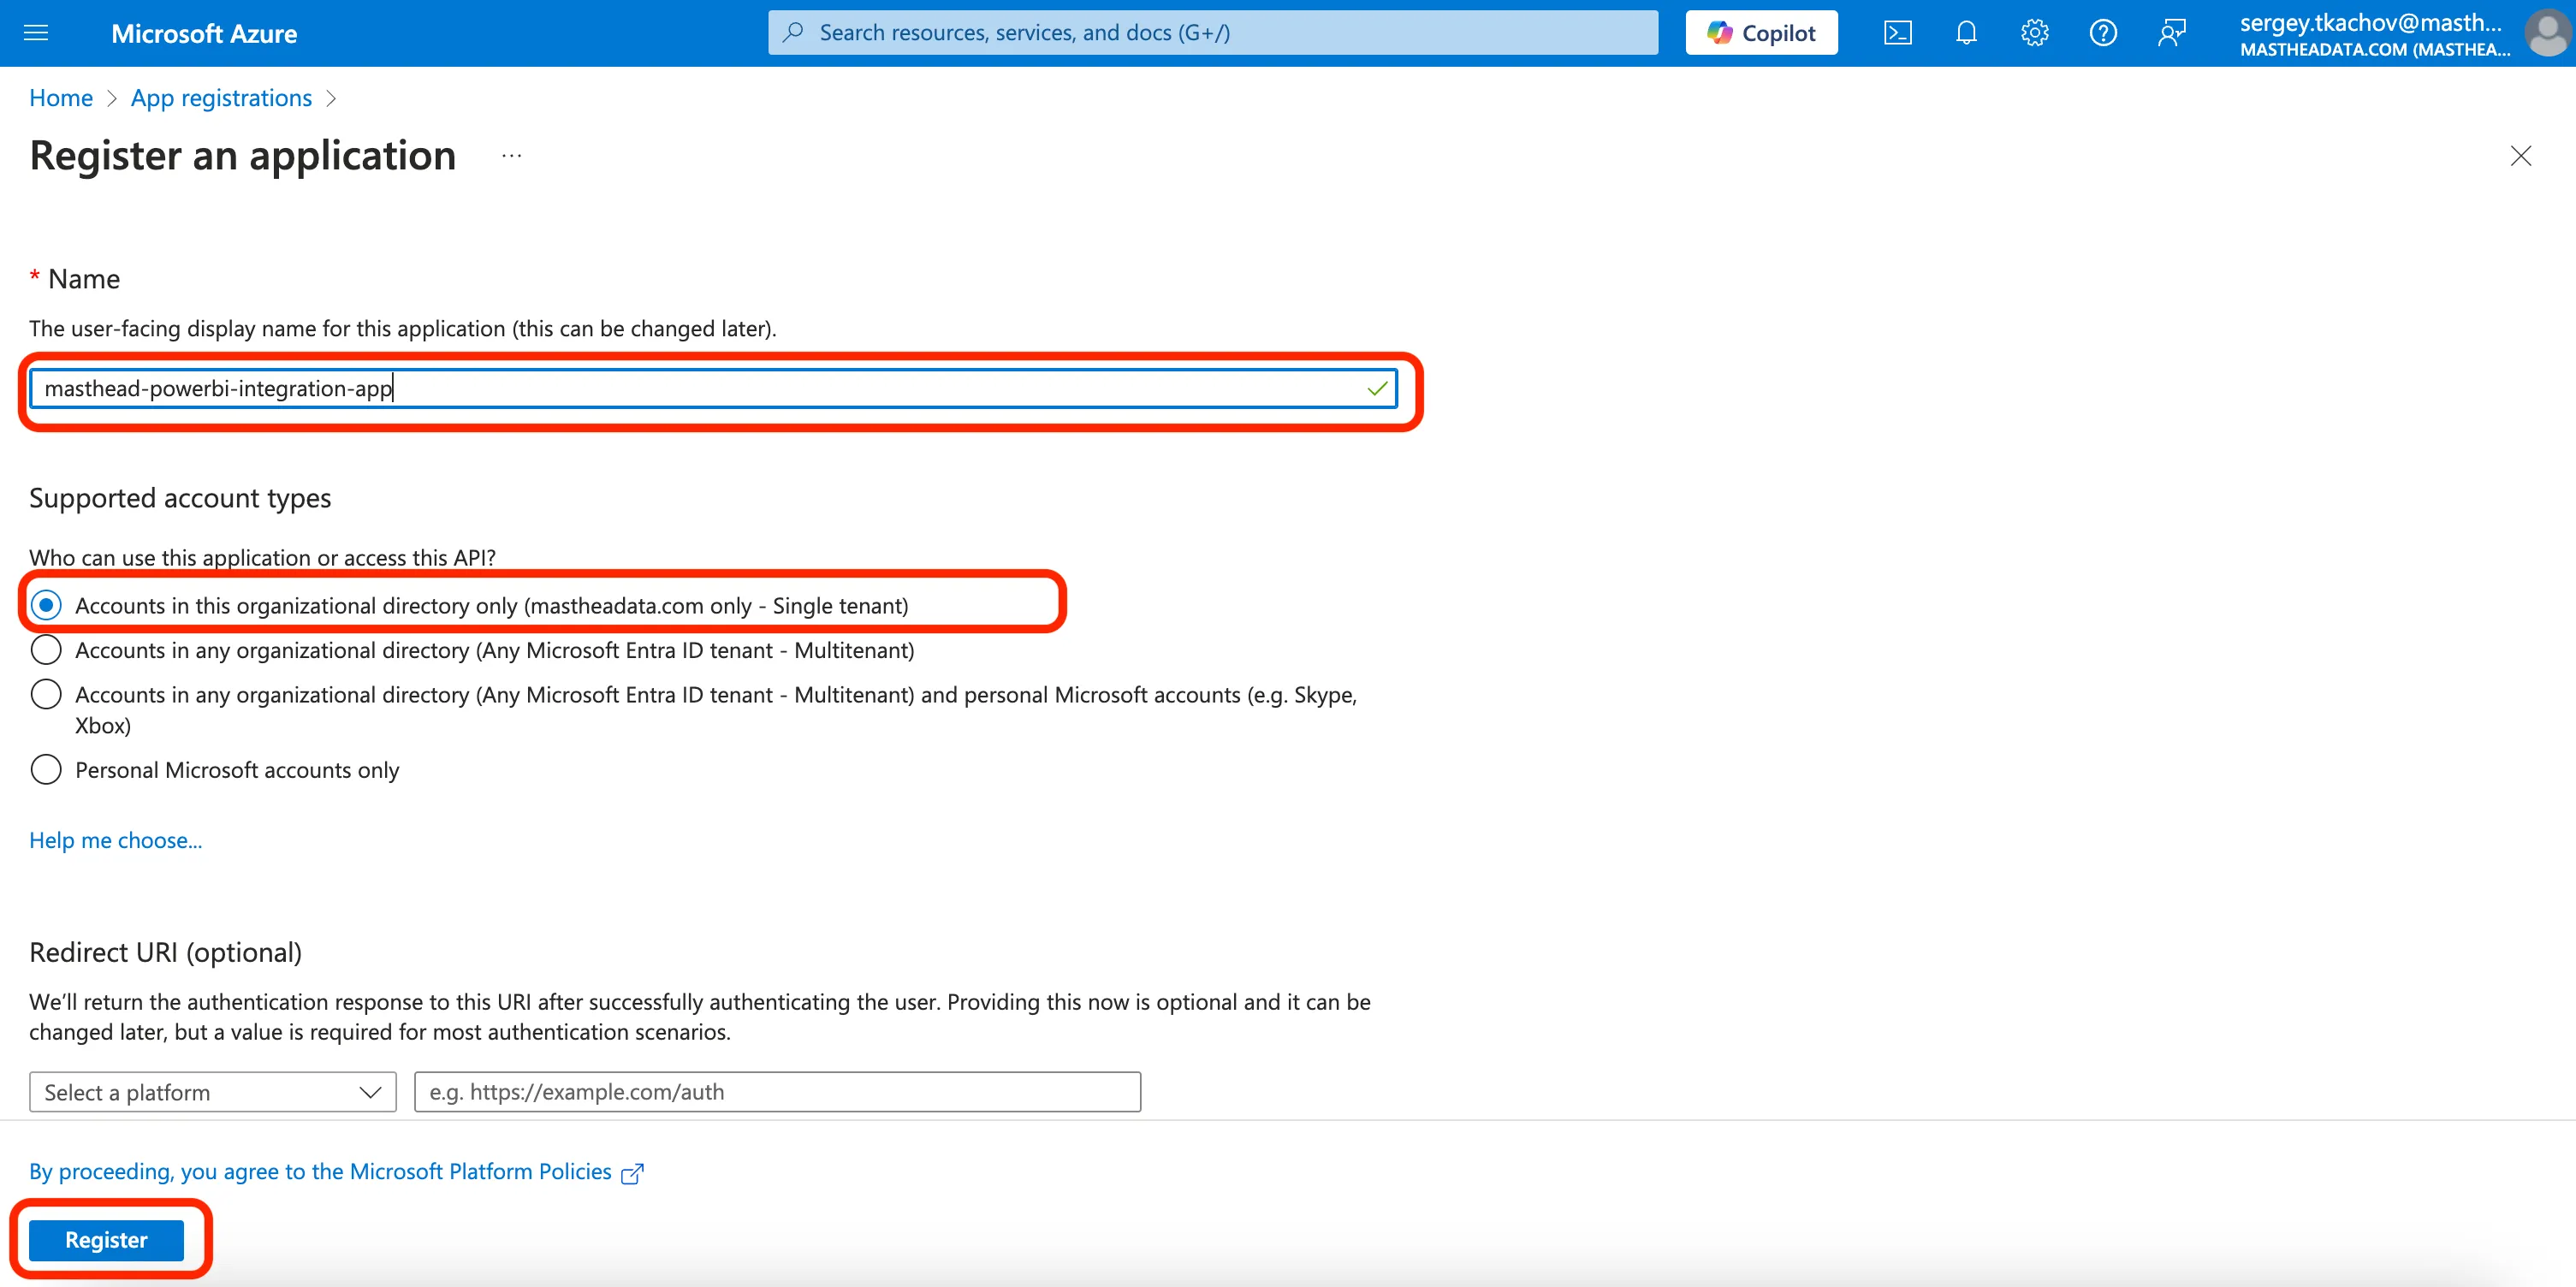
4. After successful app registration, an Overview page displays app details. Copy the Application client ID and Directory tenant ID values to a secure location. You need these values later.
5. From the **Manage** menu, click **Certificates & secrets**. Click **New client secret.**
6. Fill the name of the secret as `masthead-powerbi-integration-app-secret` and click **Add** button.
7. After the secret is successfully created, copy the value of the secret to a secure location; you need this value later.
### Create Azure Entra ID security group
[Section titled “Create Azure Entra ID security group”](#create-azure-entra-id-security-group)
1. Open **Microsoft Entra ID** menu
2. Click **Add** -> **Group** button
3. Set **Group type** - `Security`, and **Group name** - `masthead-powerbi-security-group`. Click **Create**.
4. Open the newly created group by navigating to **Groups** > **All groups** and clicking the `masthead-powerbi-security-group` group.
5. Navigate to the Members menu and click **Add members**
6. Search for `masthead-powerbi-integration-app` and select the checkbox to the left. Click **Select**.
### Grant security group the access to Power BI APIs
[Section titled “Grant security group the access to Power BI APIs”](#grant-security-group-the-access-to-power-bi-apis)
1. Go to the Power BI Admin portal
2. In Tenant settings, find **Developer settings**. Open the **Service principals can use Fabric APIs** and enable it. Select **Specific security groups** and type the name of the recently created security group `masthead-powerbi-security-group`. Click **Apply**.
3. In Tenant settings, find **Admin API settings**
4. Enable **Service principals can access read-only admin APIs**, specify security group `masthead-powerbi-security-group` and click **Apply**.
5. Enable ‘Enhance admin APIs responses with detailed metadata’, specify security group ‘masthead-powerbi-security-group’ and click Apply.
6. Enable **Enhance admin APIs responses with DAX and mashup expressions**, specify security group `masthead-powerbi-security-group` and click **Apply**.
Note
Note: The changes take up to 15 minutes to take effect. After that, you can use the tenant ID, client ID, and client secret to set up the integration in Masthead.
### Configure Power BI integration in Masthead
[Section titled “Configure Power BI integration in Masthead”](#configure-power-bi-integration-in-masthead)
Provide ‘Tenant ID’, ‘Client ID’ and ‘Client Secret’ via [the Google Form](https://docs.google.com/forms/d/e/1FAIpQLSdZrjJ1ErGbqhXMm-bcKL7zTIwN_dA9PZ7ItWL0URDMTue-HQ/viewform).
The Masthead team sets up the integration and sends a notification once it’s complete.
The Power BI integration is now complete.
# Data Anomaly Detection
> This functionality helps to detect anomalies or outliers in time series data by accessing logs and metadata of Google BigQuery and utilizing machine learning.
## Freshness
[Section titled “Freshness”](#freshness)
The automated freshness monitoring system tracks the frequency of updates on a table and notifies when the latest update becomes outdated by creating an incident in the Masthead UI and sending an alert to the Slack channel.
Masthead analyzes one month’s worth of retrospective logs to inform its ML model, ensuring that Masthead applies the freshness metric to all time series tables within 5-6 hours of deployment.
Masthead detects freshness anomalies in real-time. As Masthead examines log patterns, any deviation from the expected data ingestion schedule triggers an alert about the anomaly.
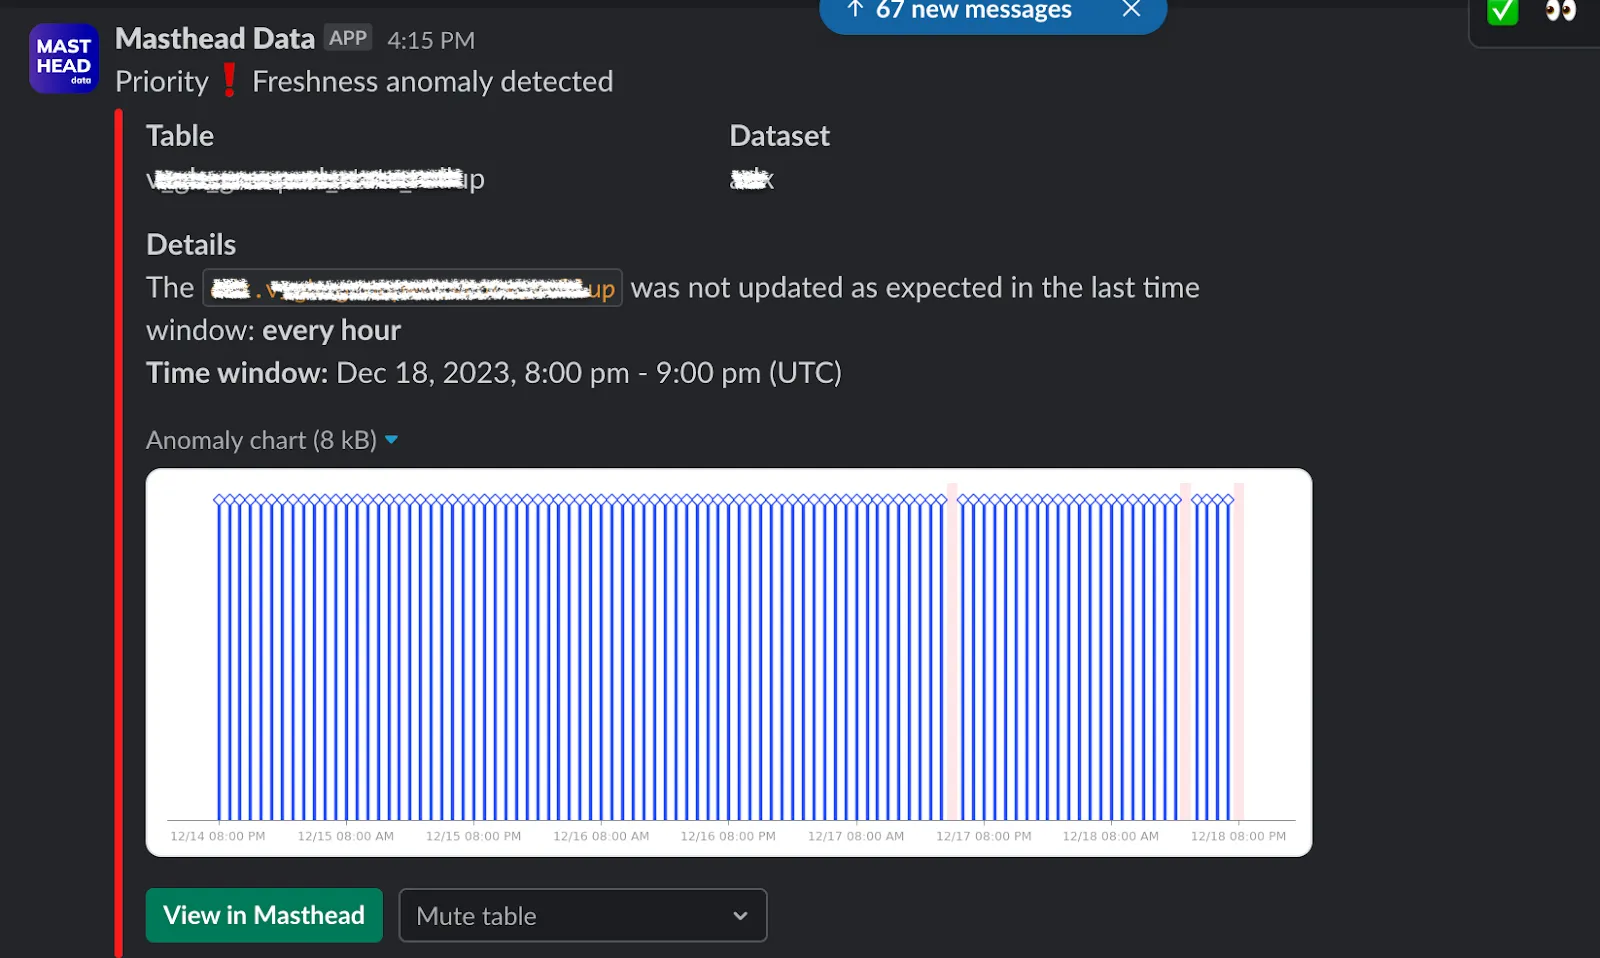
Slack bot message. Freshness anomaly
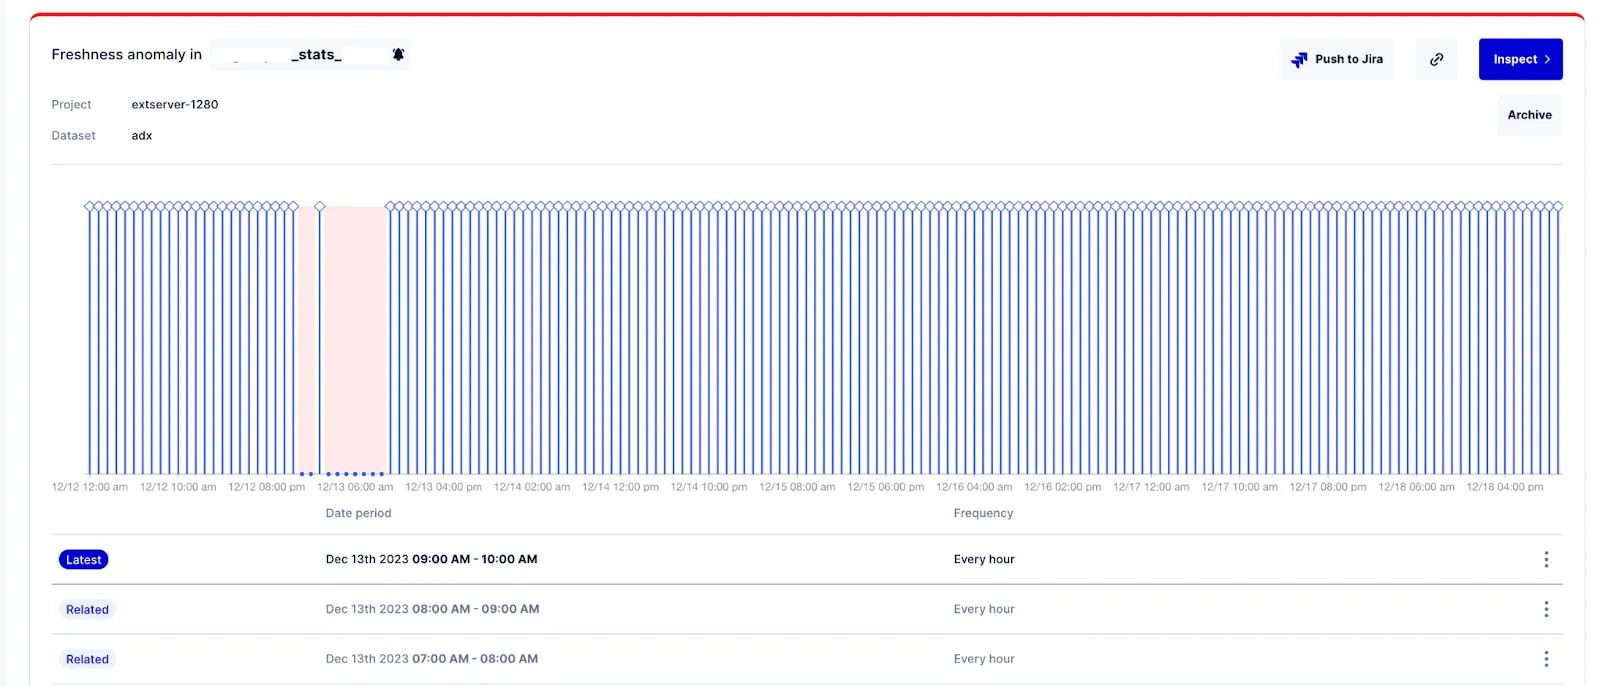
Masthead Freshness incident
The **Incident** tab contains:
1. The name of the table where the incident occurred.
2. Location on the table: its project and dataset.
3. A graph indicating when the table failed to update, marked in red. Each blue bar represents an update event for the table.
4. Below each incident, there is a display showing the duration of the missed updates and the expected update frequency based on past patterns.
## Volume
[Section titled “Volume”](#volume)
The automated volume anomaly detection system examines variations in the number of rows changed in a table and provides real-time alerts for unexpected data volume changes. This includes significant additions or deletions of data or any unusual patterns in row changes.
Masthead analyzes one month’s worth of retrospective logs to inform its ML model, ensuring that Masthead applies the freshness metric to all time series tables within 5-6 hours of deployment.
Masthead detects volume anomalies in real-time. When Masthead analyzes log patterns, any deviation from the expected data range during ingestion triggers an anomaly alert, both in the Masthead interface and on Slack.
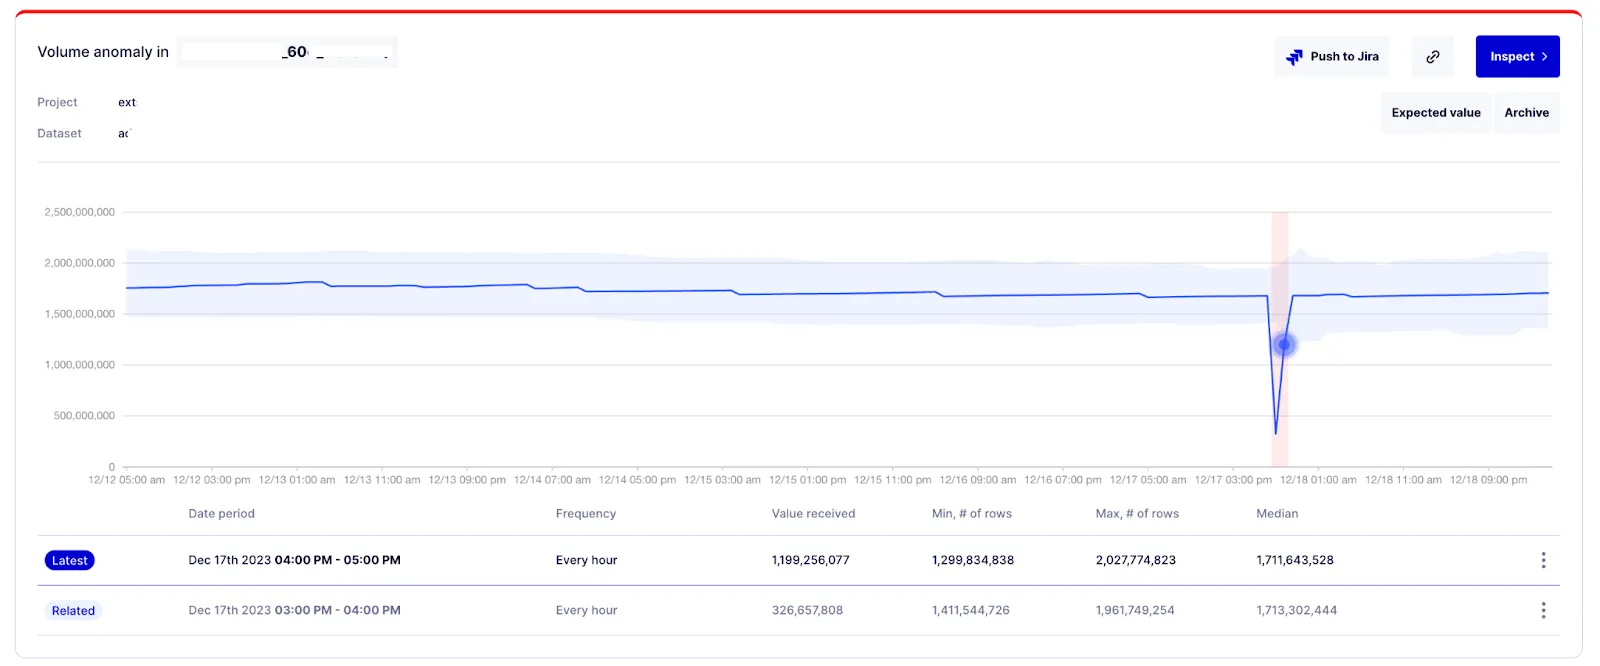
Masthead Volume incident
In the preceding example, you can see a table consistently adding rows and a sudden drop below the expected range during two ingestions.
The **Incident** tab contains:
1. The name of the table where the incident occurred.
2. Location on the table: its project and dataset.
3. A graph indicating when the table experienced unusual volume changes, marked in red. Each blue bar represents an update event for the table.
4. Below each incident, there is a table displaying: Date period, Frequency, Value received, Min, Max, Median, and Deviation based on past patterns.
## Data quality
[Section titled “Data quality”](#data-quality)
By leveraging custom data quality rules, you can implement specific validation queries tailored to your business needs. You store the results of these checks in dedicated tables within your project, providing a clear record of data quality status over time. See integration steps required in [Data Quality](/observability/data-anomaly-detection#data-quality).
Data quality incident
Masthead analyzes the scan results, identifies thresholds and triggers for the incidents, and sends notifications via your notification service integration.
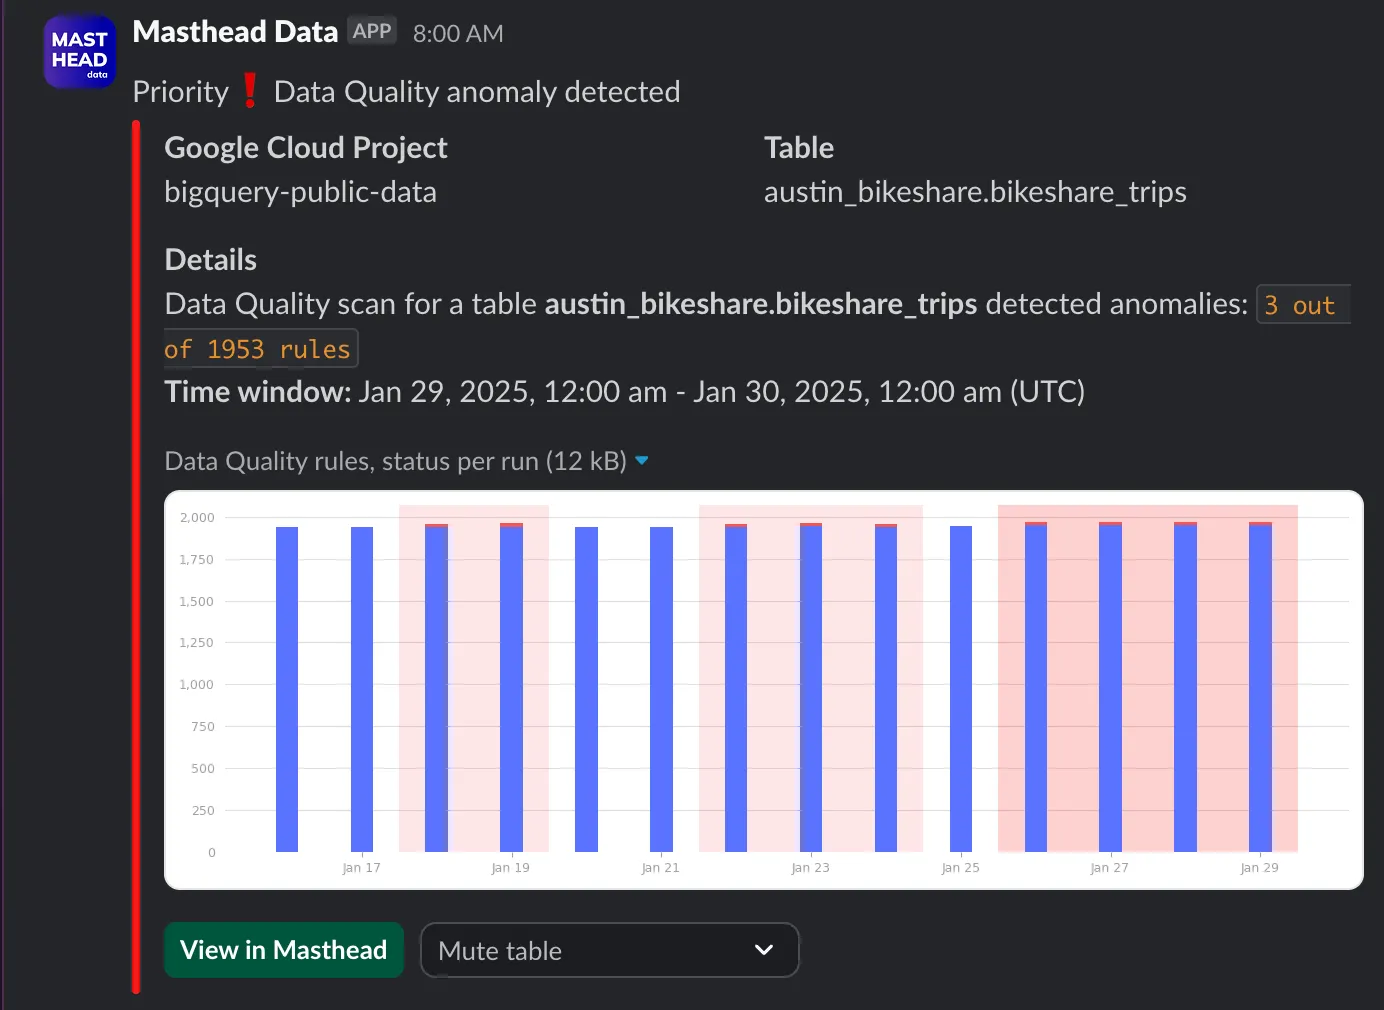
Data quality incident notification in Slack
## FAQ
[Section titled “FAQ”](#faq)
* **what’s the look-back period during onboarding?** Masthead uses 4 weeks of retrospective logs available in the audit log.
* **Do you access the schema table?** No, to collect the necessary data points, Masthead uses only logs.
* **Which tables can Masthead monitor in the data warehouse using anomaly detection?** Masthead automatically monitors all tables that updated within the cadences in the past month prior to Masthead’s deployment.
* **What data do you query?** None. Masthead doesn’t request permissions nor read or edit clients’ data.
* **How long does it take to deliver the first insights and catch the first anomalies?** Up to 6 hours, depending on the number of tables in BigQuery. During the deployment, Masthead parses retrospective logs, which allows an understanding of the patterns for every time-series table within BigQuery.
* **What metrics does data anomaly detection include?**
* **Freshness**: the recency of a table update. Masthead automatically identifies the frequency of each table update by using GCP logs.
* **Volume**: volume of data received per insert and per aggregate step.
* **Data Quality scans**: custom data property changes. Masthead uses the data of the regularly scheduled data scans to analyze the anomalies.
* **Do you need to enable it manually?** No. For Freshness and Volume Masthead parses retrospective logs and detects time-series automatically. Only Data Quality anomaly detection requires the configuration of custom data scans.
# Data Dictionary
## What’s a data dictionary?
[Section titled “What’s a data dictionary?”](#whats-a-data-dictionary)
The Data Dictionary in Masthead is a comprehensive list of all assets within the connected Google BigQuery and Looker environments. It’s a handy collection of metadata, enabling users to easily search for datasets, tables, columns, Looker dashboards, or looks.
For BigQuery tables, the dictionary provides essential information like the creation date, last update, size, and first-level upstream and downstream dependencies. It also includes any available descriptions from BigQuery.
Upon deployment, you’ll see a list of tables, views, and external tables in the connected Google Cloud projects.
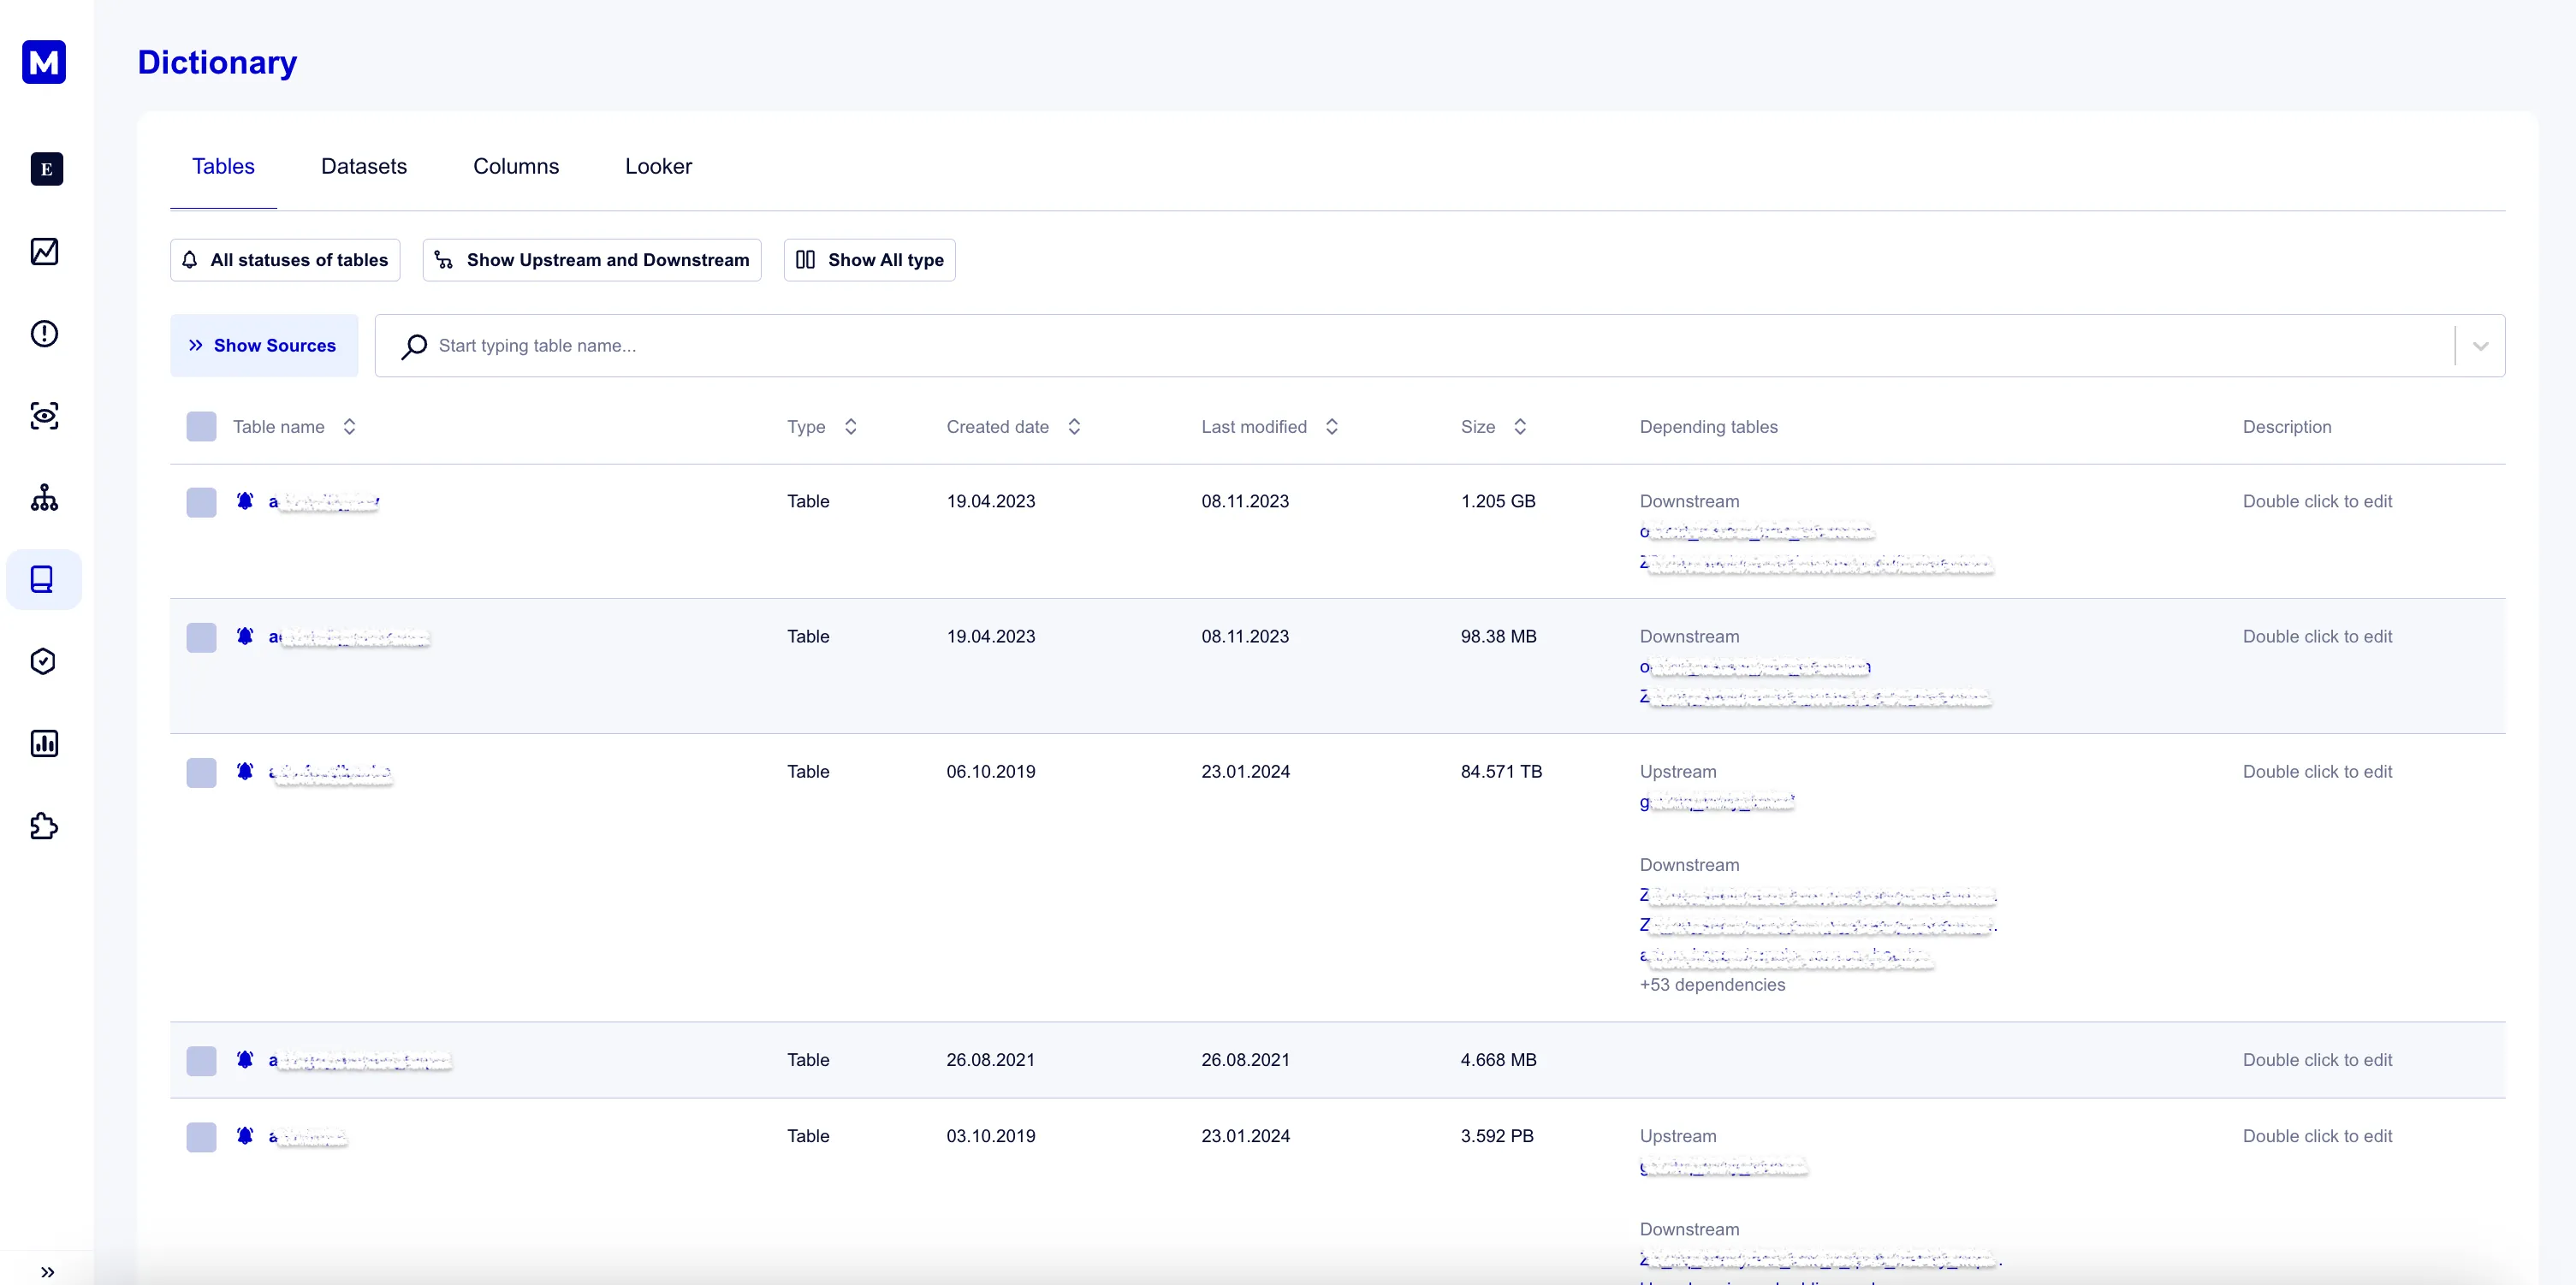
Tables dictionary
For columns, the dictionary allows users to search any term across the entire warehouse agnostically, providing details about the column type, its location, and description.
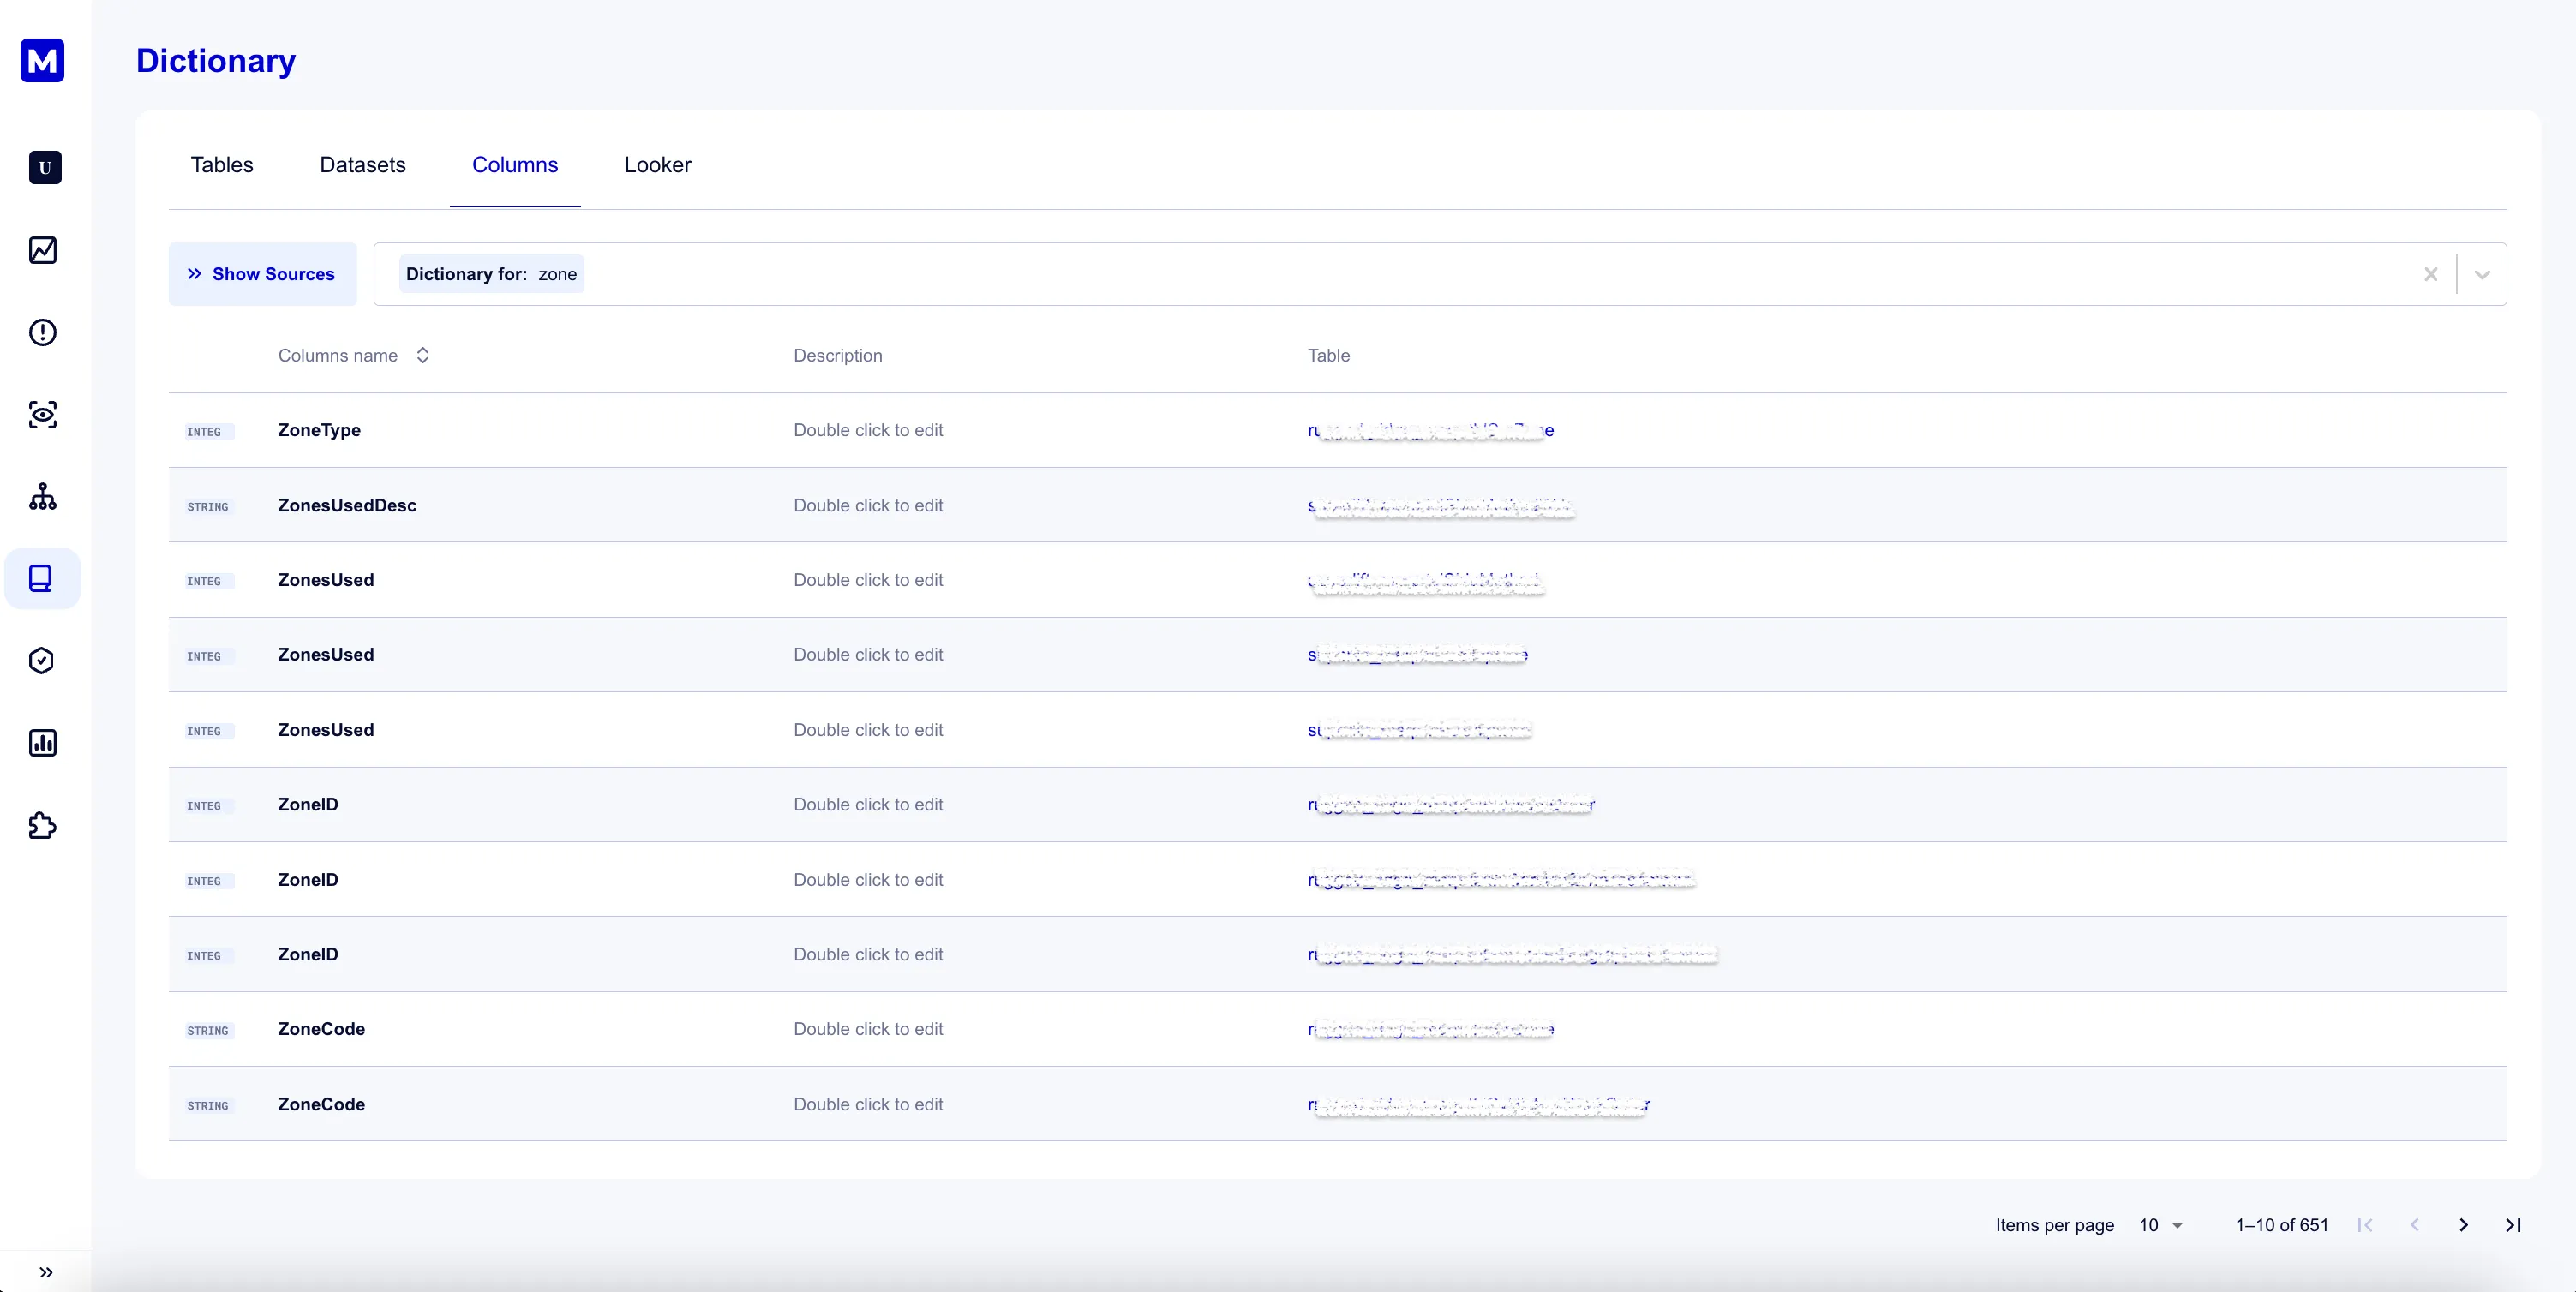
Columns dictionary
For BI assets, the dictionary offers visibility into all existing dashboards and reports. It includes their IDs with direct links to Looker, dashboard elements, upstream dependencies in Google BigQuery, and information on the dashboard’s creation and last update dates.
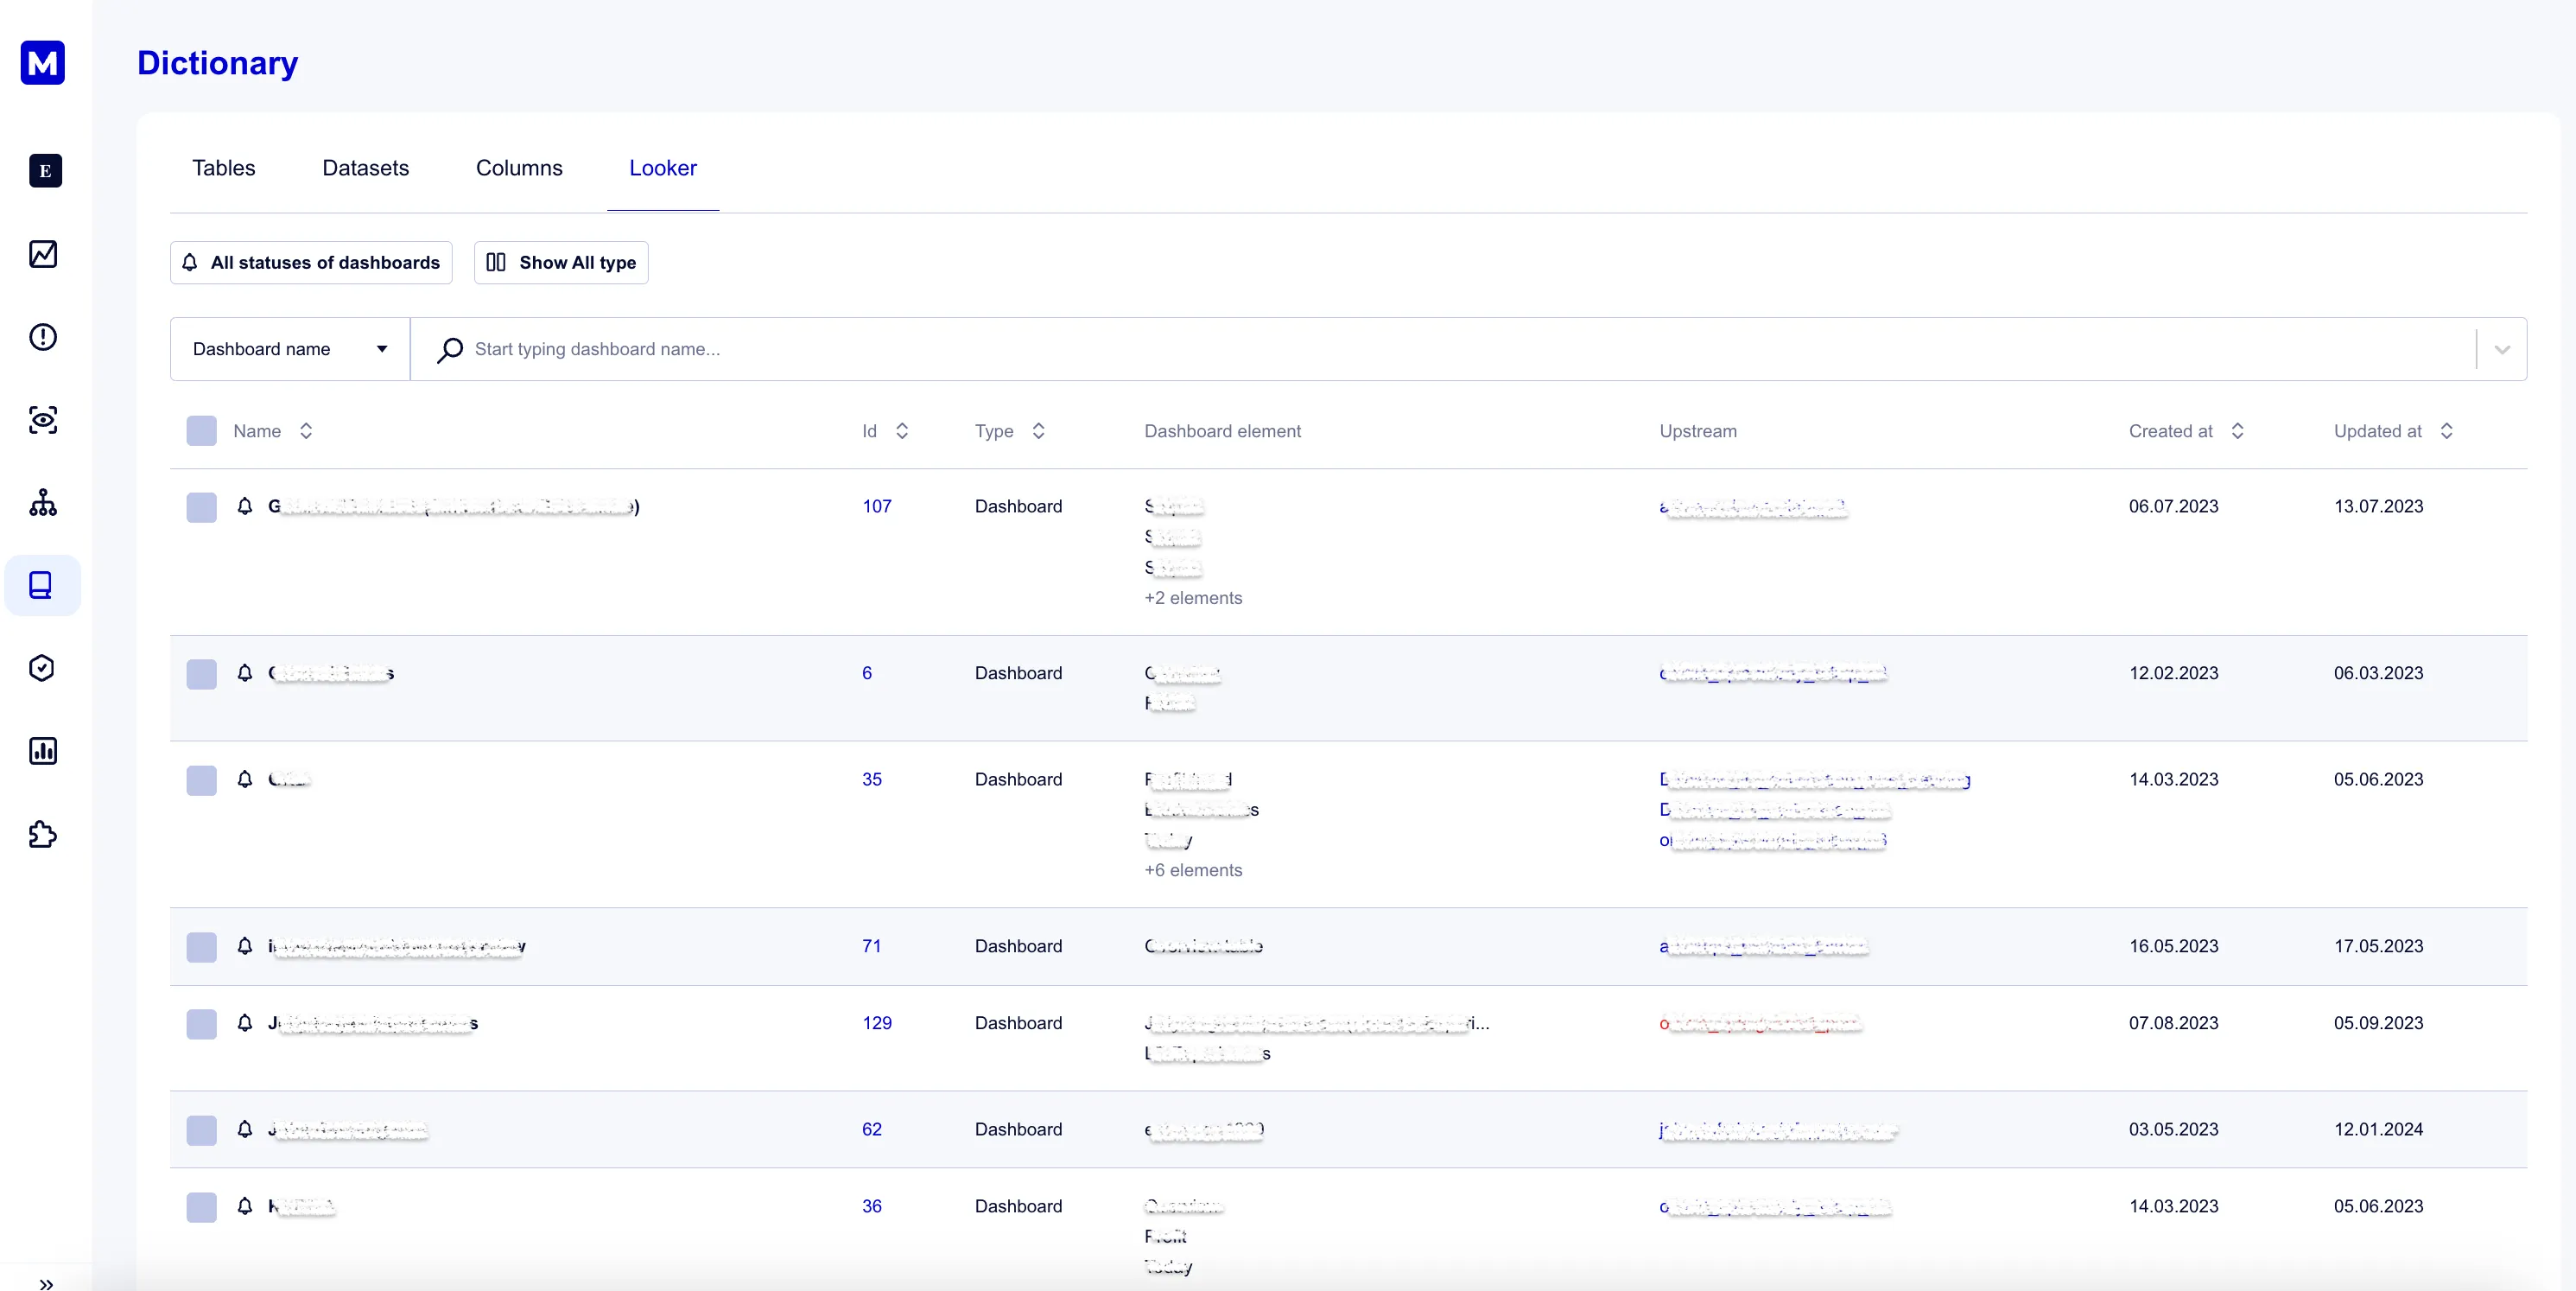
Looker assets dictionary
The Data Dictionary offers centralized access to metadata, significantly simplifying data exploration and analysis, thereby boosting efficiency when using Google BigQuery and Looker. It benefits both data and business teams by providing an intuitive UI to easily understand, locate, and interact with available data assets, data products, and its dependencies within the data platform.
## Asset priorities
[Section titled “Asset priorities”](#asset-priorities)
Every BigQuery table and every BI asset (Looker dashboard, Looker look, Looker Studio report, Google Sheet) carries a monitoring priority tier. The tier controls how Masthead alerts on that asset:
* **MUTED**: Masthead still detects anomalies, but sends no alert.
* **REGULAR**: The default tier; anomalies alert as normal.
* **PRIORITY**: Masthead escalates alerting, and lists incidents on the asset first on the Incidents page.
* **CRITICAL**: The highest tier, for the assets that matter most to the tenant; Masthead escalates alerting and lists incidents on the asset first on the Incidents page, ahead of PRIORITY.
For a BI asset, the tier also reaches upstream: a dashboard or report’s priority feeds into pipeline anomaly alerting for the pipelines that write the tables it reads from, so raising a dashboard’s tier can raise the alert sensitivity of its upstream pipelines too.
### Setting a tier
[Section titled “Setting a tier”](#setting-a-tier)
* For a table, use the row action in the Dictionary’s **Tables** tab.
* For a BI asset, use the **BI Dashboards** tab.
### Automating tier reviews
[Section titled “Automating tier reviews”](#automating-tier-reviews)
The [`masthead-asset-prioritization`](/developer/ai-agent-skills) agent skill reviews tables and BI assets against their Masthead asset scores and proposes tier changes—raising under-monitored assets that score highly, and lowering prioritized assets whose score no longer supports it—with a reason grounded in the score metrics for each suggestion, applying a change only after per-asset confirmation.
# Lineage
## What’s data lineage?
[Section titled “What’s data lineage?”](#whats-data-lineage)
Masthead’s lineage feature visualizes the origin and destination of data, identifying dependencies across tables, columns, views, spreadsheets, or dashboards and highlighting pipelines. This feature enhances understanding of data asset connections in your data platform and tracks how technologies like Fivetran, Stitch, dbt, and Dataform load and model data. Combined with anomaly detection, pipeline observability, and data quality, Masthead offers rapid and effective troubleshooting of data issues to pinpoint their root causes. It also efficiently assesses the impact of any changes on your data platform, providing insights in minutes.
Connect your [Looker](/integrations/looker) or [Power BI](/integrations/power-bi) instances to get lineage linked down to your BI dashboards.
Column-level lineage
# Pipeline and Model Observability
As the number of data pipelines in an organization increases, the complexity of creating, managing, deploying, and operating these pipelines also rises. Similarly, diagnosing, debugging, rolling back, or even identifying the owner of a pipeline becomes more challenging when issues arise in production. Additionally, complex SQL workflows for data transformation in BigQuery are prone to many different types of errors.
Masthead monitors all jobs executed in connected GCP projects and provides real-time alerts for any pipeline and model errors. It offers detailed descriptions of issues, along with other relevant information about the failed job, aiding in quick troubleshooting.
Error examples include infrastructure-related issues such as access denials for pipeline processing, exceeded deadlines while globbing file patterns, or data-related issues like missing staging files in Google Storage. Common data transformation errors might range from ‘unrecognized file formats’ and ‘missing required files’ to ‘syntax errors’.
These and many more types of errors can break continuous data import and transformation.\\
Masthead incident. Pipeline error
Details available on the Incident tab:
* The name of the destination table or project where the incident occurred.
* The project location of the job.
* The service account that executed the job.
* The key.
* Details of the error.
* Each incident card includes the error time and the pipeline or model source code, which you can open by clicking the card.
dbt model query
## FAQ
[Section titled “FAQ”](#faq)
* **Does the user need to implement any sort of SDK to receive alerts about these types of anomalies?**
No. Masthead notifies users about these types of errors by monitoring logs.
* **How quickly are pipeline errors reported?**
Masthead notifies users about pipeline and data model errors within seconds after their occurrence.
* **Does Masthead catch errors produced by dbt, Fivetran, and Python scripts?**
Masthead alerts users about pipeline errors regardless of the solution used. It doesn’t require direct integration with any of your data stack solutions.
# Environment sizing
> Information required to understand a customer's Google Cloud environment.
To estimate the scale of your infrastructure, gather two key metrics from your Google Cloud environment:
* the total number of tables
* and the expected volume of BigQuery logs that Masthead processes.
## 1. Total number of tables
[Section titled “1. Total number of tables”](#1-total-number-of-tables)
Use Cloud Asset Inventory to easily count BigQuery tables across multiple regions.
### Use the Google Cloud console
[Section titled “Use the Google Cloud console”](#use-the-google-cloud-console)
1. Open [Cloud Asset Inventory](https://console.cloud.google.com/iam-admin/asset-inventory/resources) in the Google Cloud console.
2. Apply the filter **Resource type = `bigquery.Table`** to view the total count.
### Use the gcloud command-line tool
[Section titled “Use the gcloud command-line tool”](#use-the-gcloud-command-line-tool)
Run the following command, replacing ``. For multiple projects, either sum the results or change `--scope` to your folder/organization level:
```bash
gcloud asset search-all-resources \
--scope="projects/" \
--asset-types="bigquery.googleapis.com/Table" \
--format="value(name)" | wc -l
```
## 2. Total number of BigQuery logs
[Section titled “2. Total number of BigQuery logs”](#2-total-number-of-bigquery-logs)
Masthead uses Google Cloud Logging to process metadata and analyze your BigQuery environment. To estimate the expected log volume:
1. Go to the [**Logs Explorer**](https://console.cloud.google.com/logs/query) in the Google Cloud console.
2. Refine the logs scope to ensure that you select the Google Cloud projects to integrate with Masthead.
3. Set the time range in the top right corner to **Last 30 days**.
4. In the query builder, apply the following log filter:
```text
(
protoPayload.methodName="google.cloud.bigquery.storage.v1.BigQueryWrite.AppendRows" OR
protoPayload.methodName="google.cloud.bigquery.storage.v1.BigQueryWrite.ReadRows" OR
protoPayload.methodName="google.cloud.bigquery.v2.JobService.GetQueryResults" OR
protoPayload.methodName="google.cloud.bigquery.v2.JobService.InsertJob" OR
protoPayload.methodName="google.cloud.bigquery.v2.JobService.Query" OR
protoPayload.methodName="google.cloud.bigquery.v2.TableDataService.List" OR
protoPayload.methodName="google.cloud.bigquery.v2.TableService.InsertTable"
) AND (
resource.type="bigquery_table" OR
resource.type="bigquery_dataset" OR
resource.type="bigquery_project"
)
```
5. Click **Run query**.
6. Under the **Histogram** panel and preceding the log list there is `X results` - a total number of matched log entries over the selected period.
7. Note the total count of matched logs and share this information with the Masthead team.
# Release Notes
## October 5, 2026 - custom data scans with AI agents
[Section titled “October 5, 2026 - custom data scans with AI agents”](#october-5-2026---custom-data-scans-with-ai-agents)
Custom data scans monitor the metrics that matter to your team, such as null rates, row counts, or daily costs, next to the checks Masthead runs on its own. You describe a metric to your AI agent, the agent publishes it as a BigQuery table that a scheduled query keeps current and creates the scan, and Masthead raises a data quality incident when a value falls outside its expected range.
* **Agent-guided setup**: The `masthead-data-scans` skill in the [Masthead agent tools plugin](https://github.com/masthead-data/for-agents) helps you write the metric query and checks it with your credentials. After you confirm each step, it creates the `masthead_dq` dataset, the table, its scheduled refresh, and the grant, and then creates the scan.
* **Metrics, not rows**: The scan table holds aggregated values per table, metric, and period. Masthead reads only that dataset, never your table rows.
* **Expected ranges and missing data**: Masthead learns the expected range of every metric and flags values outside it and periods without data. Masthead checks a period only after it closes and a processing delay passes, so late data can arrive.
* **Immediate first run**: The first run starts as soon as you create a scan and analyzes the last 14 days without sending notifications. Later anomalies follow your alert settings.
* **MCP tools**: Agents create, list, update, and delete scans with the [data scan tools](/developer/mcp/tools#data-scan-tools). A dry run validates the table before Masthead creates the scan.
* **Data scans tab**: The Data Quality page lists every data scan with its latest result. Each scan’s page shows results per period, metric values against their expected ranges, the scan configuration, and the monitored tables. Dataplex scans move to their own tab.
* **Scan queries on Masthead**: Masthead pays for the queries that read the scan table.
Custom data scans are available in the US region.
To create your first scan, follow the [data scans skill guide](/developer/ai-agent-skills#data-scans-skill) or read the [custom data scans documentation](/governance/data-quality-scans#custom-data-scans). Review your scans on the [Data Quality page](https://app.mastheadata.com/data-quality).
## September 9, 2026 - Masthead agent tools
[Section titled “September 9, 2026 - Masthead agent tools”](#september-9-2026---masthead-agent-tools)
Masthead ships a set of pre-built skills that let AI coding agents triage incidents and audit BigQuery spend against your Masthead data. The skills run in Claude Code, OpenAI Codex, and other agentic harnesses, and include the Masthead MCP server connection, so an agent reads your incidents, lineage, and cost recommendations directly.
* **One plugin**: The `masthead-agent-tools` plugin in the [for-agents repository](https://github.com/masthead-data/for-agents) bundles the skills, commands, and the MCP server connection.
* **Incident triage**: The triage workflow collects open incidents, traces lineage and blast radius, and drafts a mitigation plan.
* **FinOps audit**: The savings workflow reviews cost optimization opportunities across multiple categories and suggests actions to apply to realize them. The skills prepare a set of required code artifacts or reports for you to review.
Click **Agent tools** in the Masthead app to copy a setup prompt that walks your agent through installation and MCP sign-in.
Follow the [AI agent skills guide](/developer/ai-agent-skills) or review the [MCP tools reference](/developer/mcp/tools).
## September 8, 2026 - reservation recommendations by principal
[Section titled “September 8, 2026 - reservation recommendations by principal”](#september-8-2026---reservation-recommendations-by-principal)
Masthead recommends moving each principal’s workload to a cheaper BigQuery reservation or to on-demand compute, and generates the assignment configuration for you. A recommendations widget on the Principals tab ranks principals by potential savings, and each recommendation has a dedicated page with the reassignment details.
Review principal recommendations on the [Workload / Principals page](https://app.mastheadata.com/workload?tab=Principals) and follow the [Reservation Assignments guide](/cost-insights/compute-costs/reservation-assignments).
## September 2, 2026 - compute cost attribution by principal
[Section titled “September 2, 2026 - compute cost attribution by principal”](#september-2-2026---compute-cost-attribution-by-principal)
Workload gets a **Principals** tab that attributes BigQuery compute cost and potential savings to the identity that ran a job, whether a service account or a user. Use it to find which automated principals drive spend and where a billing-model change pays off.
Open the Principals tab on the [Workload / Principals page](https://app.mastheadata.com/workload?tab=Principals).
## August 14, 2026 - reservation recommendations for individual models
[Section titled “August 14, 2026 - reservation recommendations for individual models”](#august-14-2026---reservation-recommendations-for-individual-models)
Masthead recommends the most cost-effective BigQuery compute model for each individual data model, with an assignment configuration ready to apply.
Review model recommendations on the [Workload / Models page](https://app.mastheadata.com/workload?tab=Models) and follow the [Reservation Assignments guide](/cost-insights/compute-costs/reservation-assignments).
## August 3, 2026 - data quality scan severity and incident context
[Section titled “August 3, 2026 - data quality scan severity and incident context”](#august-3-2026---data-quality-scan-severity-and-incident-context)
Custom data quality scans carry a severity, and incidents show the scan that triggered them. You can judge how urgent a data quality failure is without leaving the incident.
Review scan results on the [Data Quality page](https://app.mastheadata.com/data-quality) or read the [data quality scans documentation](/governance/data-quality-scans).
## July 28, 2026 - incident origin data products, notes, and user roles
[Section titled “July 28, 2026 - incident origin data products, notes, and user roles”](#july-28-2026---incident-origin-data-products-notes-and-user-roles)
Incident triage gains product context and loses clicks, and you can change an incident assignee in the overview list.
Open the [Incidents page](https://app.mastheadata.com/incidents).
## July 24, 2026 - rebuilt data dictionary
[Section titled “July 24, 2026 - rebuilt data dictionary”](#july-24-2026---rebuilt-data-dictionary)
Masthead rebuilt the Dictionary for speed and clarity. The datasets list loads faster on large warehouses, and the table details page shows total cost and a dead-end indicator alongside schema and lineage.
Browse your tables on the [Dictionary page](https://app.mastheadata.com/dictionary).
## July 23, 2026 - BigQuery reservation monitoring
[Section titled “July 23, 2026 - BigQuery reservation monitoring”](#july-23-2026---bigquery-reservation-monitoring)
A new Reservation page tracks how your BigQuery slot capacity is used over time. Compare provisioned capacity against actual slot consumption for each reservation to find over- and under-provisioning before it reaches the bill.
Open a reservation from the Reservation tab in [Cost Insights](https://app.mastheadata.com/costs).
## July 14, 2026 - configurable pipeline cost columns and pipeline error context
[Section titled “July 14, 2026 - configurable pipeline cost columns and pipeline error context”](#july-14-2026---configurable-pipeline-cost-columns-and-pipeline-error-context)
The Pipelines tab on the Workload page becomes a table you configure, and pipeline details show recent run failures next to cost and lineage.
* **Configurable columns**: Choose which cost and usage columns the Pipelines list shows, and reorder them. Configurations are saved per user.
* **Pipeline error widget**: The pipeline view shows the most recent error message for a pipeline. You can still see the detailed retrospective in the Incidents page.
Open the [Pipelines tab on the Workload page](https://app.mastheadata.com/workload?tab=Pipelines) or read the [pipeline and model observability guide](/observability/pipeline-and-model-observability).
## July 1, 2026 - lineage for shared datasets and Looker explores
[Section titled “July 1, 2026 - lineage for shared datasets and Looker explores”](#july-1-2026---lineage-for-shared-datasets-and-looker-explores)
The Lineage graph shows cross-project dataset sharing and drills into Looker down to the explore.
* **Linked dataset nodes**: The graph renders shared datasets, the tables, views, materialized views, external tables, and routines inside them, and their external consumers as distinct node types.
* **Looker explores**: A Looker dashboard node lists its explores, and edges connect BigQuery tables to the explores that read them.
* **Rebuilt graph**: The Lineage page and the lineage widgets embedded in incident, data asset, and pipeline views share a more performant renderer and asset search.
Open the [Lineage page](https://app.mastheadata.com/lineage) or read the [lineage documentation](/observability/lineage).
## June 30, 2026 - expanded data stack coverage
[Section titled “June 30, 2026 - expanded data stack coverage”](#june-30-2026---expanded-data-stack-coverage)
Masthead expands the data stack of BI services and ETL/ELT tools:
* **New technologies**: Masthead detects Monte Carlo, Qlik, Terraform, Kestra, Confluent, Zapier, n8n, Boomi, and Claude.
Review detected technologies on the [Lineage page](https://app.mastheadata.com/lineage) or read the [lineage documentation](/observability/lineage).
## June 25, 2026 - expanded incident statuses, severities, and filters
[Section titled “June 25, 2026 - expanded incident statuses, severities, and filters”](#june-25-2026---expanded-incident-statuses-severities-and-filters)
Incidents carry a wider set of statuses and severities, and the incidents table filters are rebuilt.
* **More statuses and severities**: The incident status set is expanded with added severities.
* **Data quality preview**: Incident list shows a sparkline preview for data quality and Dataplex incidents.
Open the [Incidents page](https://app.mastheadata.com/incidents).
## April 30, 2026 - Dataplex data quality monitoring
[Section titled “April 30, 2026 - Dataplex data quality monitoring”](#april-30-2026---dataplex-data-quality-monitoring)
Masthead surfaces Google Cloud Dataplex data quality scans alongside its own checks.
* **Scans widget**: The Monitors page shows a Dataplex widget with each scan, its rules, and its latest results.
* **Dataplex incidents**: Incident filters and labels distinguish Dataplex data quality incidents, and incident rows show a data quality sparkline.
Connect Dataplex from the [Integrations page](https://app.mastheadata.com/integrations) or read the [Dataplex integration guide](/integrations/dataplex).
## April 7, 2026 - BI assets in data products and the dictionary
[Section titled “April 7, 2026 - BI assets in data products and the dictionary”](#april-7-2026---bi-assets-in-data-products-and-the-dictionary)
Looker dashboards and looks are assets you attach to a data product, and they appear in the Dictionary next to BigQuery tables.
* **Data product BI assets**: When you create or edit a data product, add Looker dashboards and looks alongside datasets and tables.
* **Dictionary BI dashboards**: The Dictionary lists BI dashboards with their upstream tables, and search matches dashboard names and elements.
Open the [Data Products page](https://app.mastheadata.com/data-product) or read the [data products documentation](/governance/data-products).
## March 25, 2026 - redesigned incident details page
[Section titled “March 25, 2026 - redesigned incident details page”](#march-25-2026---redesigned-incident-details-page)
The incident details page is rebuilt with a clearer layout, and updated freshness and volume charts.
* **Dedicated URL**: Each incident has its own address, so you can link a teammate straight to it.
* **Reworked layout**: The details, history, and contributing pipelines widgets, and pagination and search on the incidents list.
Open the [Incidents page](https://app.mastheadata.com/incidents).
## March 12, 2026 - Looker Studio and Google Sheets as pipeline destinations
[Section titled “March 12, 2026 - Looker Studio and Google Sheets as pipeline destinations”](#march-12-2026---looker-studio-and-google-sheets-as-pipeline-destinations)
Masthead recognizes Looker Studio reports and Google Sheets as data destinations in Pipelines, Cost Insights, and the Lineage graph.
* **Destination detection**: Jobs that export to Looker Studio or Google Sheets show the destination type in pipeline and cost tables.
* **Lineage nodes**: The Lineage graph renders Looker Studio and spreadsheet nodes.
Review destinations on the [Pipelines tab of the Workload page](https://app.mastheadata.com/workload?tab=Pipelines).
## February 24, 2026 - compute model switch recommendations
[Section titled “February 24, 2026 - compute model switch recommendations”](#february-24-2026---compute-model-switch-recommendations)
The compute savings view recommends switching a workload to a cheaper BigQuery pricing model and shows the simulated cost of the cheapest model.
* **Simulated cheapest model**: Each workload shows its current compute cost next to the cost under the cheapest on-demand or Editions model alternative.
* **Apply from a recommendation**: A recommendation shows how to create a new reservation assignment or adjust an existing one, depending on the workload’s current reservation.
Review recommendations on the [Workload page](https://app.mastheadata.com/workload) and follow the [Reservation Assignments guide](/cost-insights/compute-costs/reservation-assignments).
## February 13, 2026 - GCP integrations verification and reconnect
[Section titled “February 13, 2026 - GCP integrations verification and reconnect”](#february-13-2026---gcp-integrations-verification-and-reconnect)
To re-authorize a connected GCP project or check its access - use the Integrations page.
* **Verify access**: The integrations check and list the required resources and highlight any issues.
* **Reconnect flow**: To update roles on an existing project - use the reconnect action in the connected projects list.
Open the [Integrations page](https://app.mastheadata.com/integrations) or read the [BigQuery integration guide](/integrations/bigquery).
## February 11, 2026 - advanced Looker lineage
[Section titled “February 11, 2026 - advanced Looker lineage”](#february-11-2026---advanced-looker-lineage)
Masthead now provides automated upstream-to-BI lineage, creating a complete observability path from BigQuery tables to Looker business logic. We track actual data flow rather than relying on static LookML analysis, ensuring lineage stays in sync with real usage.
* **Cost Attribution**: Precisely pin BigQuery costs, bridging Google Cloud billing and Looker assets.
* **Impact Analysis**: Automatically discover which Looker Dashboards and Explores depend on specific BigQuery tables to prevent breaking changes. Get instant stakeholder notifications when data incidents affect business-critical BI content.
* **Usage & Optimization**: Differentiate production (Dashboards) from exploration (Ad-hoc) spend to highlight where inefficient logic originates. Identify orphaned or high-intensity BI assets to prioritize LookML and storage improvements.
[Connect your Looker](https://app.mastheadata.com/integrations/looker) to start.
## June 30, 2025 - dead-end pipelines
[Section titled “June 30, 2025 - dead-end pipelines”](#june-30-2025---dead-end-pipelines)
Masthead highlights the upstream pipelines that *only* produce “Dead-End Tables” - tables that have no downstream consumption.

Dead-end table upstream in the Lineage view
What this offers for you:
* Identify Waste: Easily pinpoint upstream pipelines that produce only these unconsumed tables.
* Reclaim Resources: Quickly review and switch off unnecessary pipelines to save on compute, storage, and operational costs.
* Boost Efficiency: Streamline your data ecosystem by removing unused assets and improving overall data governance.
**Get Started**: Check for “Dead-end pipelines” savings available on [Compute Costs](https://app.mastheadata.com/costs) to identify reclaimable resources. And keep an eye for “Dead-End” tags in your [Lineage](https://app.mastheadata.com/lineage) view .
## April 10, 2025 - data products and data domains
[Section titled “April 10, 2025 - data products and data domains”](#april-10-2025---data-products-and-data-domains)
Masthead helps you better organize, govern, and manage your data with **Data Products** and **Data Domains.**
**What’s New?**
* **Data Products:** Treat your key data assets like first-class products. Group related datasets and tables into a single, manageable entity (for example, “Finance Core Metrics” or “User Activity”). This allows you to:
* Monitor aggregated costs (compute, storage).
* Track usage, subscribers, and associated incidents.
* Improve operational governance and get more context.
* **Data Domains:** Introduce high-level categorization for your Data Products (for example, Finance, Marketing, or Product). Domains help you:
* Organize products logically by business area or team.
* Assign clear ownership via responsible team emails.
* Route relevant communications via dedicated Slack channels.
* View rolled-up cost and incident metrics per domain.
* **Manage as Code with Terraform.** Alongside these features, we’re launching [Masthead Terraform provider](https://registry.terraform.io/providers/masthead-data/masthead/latest). Now you can define, manage, and version your Data Products and Data Domains declaratively using Infrastructure as Code. Automate your data governance setup, ensure consistency, and integrate with existing CI/CD pipelines in your data platform.
**Why it Matters:**
These features provide a robust framework for treating data strategically within your organization. Improve organization, enhance governance, gain better cost and reliability visibility, and streamline management through automation.
**Get Started:**
* Explore the new [Data Products](https://app.mastheadata.com/data-product) section in the Masthead UI.
* Check out the documentation for [Data Products](/governance/data-products), [Domains](/governance/domains) and the [Terraform Provider](https://registry.terraform.io/providers/masthead-data/masthead/latest).
We believe these additions will significantly improve how you manage and leverage data in your teams.
## April 9, 2025 - transitioning to standard BigQuery metadata roles
[Section titled “April 9, 2025 - transitioning to standard BigQuery metadata roles”](#april-9-2025---transitioning-to-standard-bigquery-metadata-roles)
To enhance security and provide deeper insights into modern BigQuery features, Masthead is updating its Google Cloud integration. We are transitioning from custom IAM roles to standard Google Cloud roles, namely [BigQuery Metadata Viewer](https://cloud.google.com/bigquery/docs/access-control#bigquery.metadataViewer) and [BigQuery Resource Viewer](https://cloud.google.com/bigquery/docs/access-control#bigquery.resourceViewer).
**Why the Change?**
* **Improved Security:** Standard roles grant access only to configuration metadata, ensuring your underlying data and compute resources remain inaccessible to Masthead.
* **Enhanced Visibility:** Allows Masthead’s log-based analysis to provide you transparency into all the modern BigQuery capabilities like Routines, Models, Reservations, and Commitments.
* **Standardization:** Aligns Masthead integration with Google Cloud best practices for secure metadata exchange.
This new configuration is applied to all the new customers moving forward. See [which resources](/get-started/integrate-using-iac) are used in the integration.
**Actions Required for Existing Customers:**
To benefit from these improvements, we’ll reach out with more information to update your existing Masthead integration. We are providing two options there:
1. **OAuth Integration:** You can update configuration [via the UI in a one-click OAuth process](https://app.mastheadata.com/integrations?updateRoles=true) to re-authorize with the new roles.
2. **Terraform Integration:** Update to the latest version of our [Terraform module](https://registry.terraform.io/modules/masthead-data/masthead-agent/google/latest) and re-apply your configuration.
## February 25, 2025 - storage cost insights
[Section titled “February 25, 2025 - storage cost insights”](#february-25-2025---storage-cost-insights)
We’re excited to introduce **Storage Cost Insights**, a new feature in Masthead that helps to get an overview and optimize BigQuery storage costs. Masthead now analyzes BigQuery metadata and usage logs to estimate storage costs and provides actionable recommendations to reduce spending.
Key facts:
* Aggregated Storage Cost Metrics: View estimated storage size and cost per dataset.
* Actionable Billing Model Recommendations: Masthead evaluates both Logical and Physical storage billing models to suggest the most cost-effective option for each dataset. Easily identify datasets where switching billing models can lead to consistent cost savings.
* Simple Implementation: Apply recommended changes using a one-line DDL statement:
When you need to switch a dataset to logical storage billing model:
```sql
ALTER SCHEMA my_dataset SET OPTIONS(storage_billing_model = "LOGICAL")
```
or to physical:
```sql
ALTER SCHEMA my_dataset SET OPTIONS(storage_billing_model = "PHYSICAL")
```
* Impact Awareness: Changing a dataset’s billing model takes effect after 24 hours.
Review storage cost recommendations in the [**Storage Cost Insights**](/cost-insights/storage-costs) page and apply the suggested optimizations to reduce storage expenses.
## January 27, 2025 - data quality analysis with custom scans
[Section titled “January 27, 2025 - data quality analysis with custom scans”](#january-27-2025---data-quality-analysis-with-custom-scans)
Masthead’s new [Data Quality anomalies detection with custom scans](/observability/data-anomaly-detection#data-quality) combines several key advantages: it requires minimal effort to set up, allowing you to quickly implement tailored quality monitoring that reflects your unique business needs. This approach is designed to identify any data issues before they impact your operations.
The solution automatically organizes and monitors your scans results, handling the heavy lifting of data synchronization and analysis. This streamlined automation eliminates the need for granular configuration, letting you focus on core business activities rather than intricate setup details.
Seamlessly integrating into your workflow, the feature strikes an optimal balance between simplicity and robust data validation. It’s the go-to option for teams seeking an efficient, hassle-free solution to maintain high data quality without compromising on performance.

Data quality incident
Compared to data quality feature in Google Dataplex, our approach delivers a more familiar, non-intrusive experience with minimal setup and transparent cost, providing highly tailored insights that effortlessly fit into your operational flow.
Enjoy peace of mind with a non-intrusive, metadata-driven approach to data quality that keeps your operations running smoothly and reliably.
Get started by [integrating your custom data scans](/governance/data-quality-scans#custom-data-scans) with Masthead’s anomaly detection.
## October 9, 2023 - Looker dashboards
[Section titled “October 9, 2023 - Looker dashboards”](#october-9-2023---looker-dashboards)
Masthead Data is excited to introduce a new feature designed specifically for BI specialists who work with Looker. Starting today, you can prioritize specific Looker dashboards in Masthead, ensuring that BI engineers receive notifications solely about selected dashboards. This feature reduces the number of alerts for unrelated anomalies and errors, allowing users to focus only on those that impact Looker dashboards or reports.
Additionally, we’ve provided the ability to categorize Looker dashboards as “priority,” “regular,” or “muted.” This ensures that BI engineers remain focused on what matters most.
You can now view a comprehensive list of Looker dashboards affected by anomalies or errors within a notification. Alternatively, you can explore these connections and gather detailed insights in the Data Lineage. We have added Looker, which helps visually to understand Google BigQuery and Looker dependencies.
**With this update, BI specialists can:**
1. Receive immediate notifications when a top-priority Looker dashboard is down or experiences an anomaly.
2. Consolidate all affected dashboard elements in one location, making it simpler to identify erroneous data sources and affected data consumers.
3. Focus solely on Looker dashboards and reports, avoiding notifications related to other data system failures.
**How do the Looker incidents work?**
Ensure that Looker is connected to Masthead. If Google BigQuery sources any of the dashboards in Looker, any anomaly related to BigQuery tables that affects those Looker dashboards will be displayed in the “incidents” tab (Looker).
The incident will include a list of all dashboards affected by a particular anomaly, enabling users to assess the implications and address the issue comprehensively.
**How does the Looker Dictionary work?**
The Data Dictionary now contains a list of all dashboards available in the connected Looker. This simplifies the understanding of data sources and the dashboard elements in use.
This provides a comprehensive view of dashboards, or data products if you prefer, used within the organization. It includes links to the actual Looker dashboards, a list of dashboard elements, a list of Google BigQuery tables, as well as their creation and last update dates.
The Looker Dictionary is also designed to simplify searches. Users can search by dashboard name, dashboard ID, dashboard element, or any source table upstream for a Looker dashboard.
## July 30, 2023 - Looker dictionary
[Section titled “July 30, 2023 - Looker dictionary”](#july-30-2023---looker-dictionary)
Masthead Data introduces Looker Dictionary, empowering you to spot issues in your Looker dashboards before they reach data end-customers. Gain full visibility into your data products and know how anomalies in pipelines and tables affect business users in Looker dashboards. This update enables smart searches by dashboard IDs, look names, look IDs, dashboard elements, or upstream tables, which simplifies management of Looker assets.
With this new feature, you can review the type of your Looker data product (whether it’s a look or dashboard), its core elements, owner, the upstream tables used, as well as its creation and update history of the dashboards.
You can also reach any of your Looker dashboards by just clicking on its ID in the Masthead Looker dictionary.
Dictionary for Looker helps you to:
* Get alerts about errors and anomalies that may impact your Looker dashboards long before they ever reach your customers, which is especially critical for BI engineers.
* Manage Looker entities in a single space. Know how many Dashboards and Looks are in Looker, when they were created and last updated, who is the owner.
* Run a fast and intuitive search for your critical Looker asset.
**How does this feature work?**
Once you connect Looker, go to the “Dictionary” tab and choose “Looker Dictionary.”
Masthead displays you a full list of your Looker assets, supported with interactive search options, critical information on your data products, and an opportunity to review all upstream tables affecting your dashboards.
Note that Masthead Data is a non-intrusive data observability solution that processes only metadata without accessing the actual data in your Looker.
## May 27, 2023 - query optimizer
[Section titled “May 27, 2023 - query optimizer”](#may-27-2023---query-optimizer)
Masthead Data has recently introduced a new feature that enables you to optimize your SQL queries using OpenAI GPT. With this latest update, you now have the option to select any query captured by Masthead and utilize the AI Optimizer to receive recommendations on how to improve it.
With this feature you can:
* Enhance the effectiveness of your SQL queries by following best practices recommended by the world’s foremost AI agent.
* Reduce the cost of your SQL queries by improving their overall quality.
* Receive valuable recommendations that may help you refine your query-writing approach.
The AI Optimizer ensures that your table contents remain private and are not shared with the AI agent. It only shares metadata with OpenAI to enhance the query-writing capabilities of GPT.
**How does this feature work?**
Select any SQL query from the “Compute Costs” tab and review it. If you wish to improve this query, simply click the “AI Optimizer” button.
Masthead sends a request to OpenAI GPT and provides you with a response containing a recommendation for enhancing the query. It is entirely up to you to decide whether to use the recommended query.
Note that Masthead Data cannot guarantee the accuracy of the output in every instance. Hence, we strongly advise you to thoroughly review the recommended query before executing it.
## April 27, 2023 - column data lineage
[Section titled “April 27, 2023 - column data lineage”](#april-27-2023---column-data-lineage)
Masthead Data has just released an update to its data lineage feature, allowing you to gain the most comprehensive insight into your data. Going forward, you’ll be able to see the connections between your data tables down to the smallest details of each table column. By highlighting related columns across different tables, Masthead enables you to understand how each column affects downstream data.
With this update, you get:
* Opportunity to dig deep into your data tables and pinpoint the exact connections between them
* Ability to identify and track the root cause of data anomalies affecting your tables all the way down to the specific table column
* Complete and clear observability of your data flows and connections down to reports in Looker
**How does this feature work?**
While checking your data lineage, click the number of columns in a table in the Lineage tab.
You will visualize your table column dependencies and see how each of your table columns affects related columns across different tables.
## April 14, 2023 - integration with Looker
[Section titled “April 14, 2023 - integration with Looker”](#april-14-2023---integration-with-looker)
Masthead Data offers you complete control over the quality of your Looker’s data visualizations and dashboards. No one is immune to bad data, which can quickly spread and impact the quality of downstream tables that Looker dashboards rely on. By integrating Masthead with Looker, you can quickly identify reports and dashboards affected by data anomalies and easily visualize the root cause of the problem with data lineage.
This update provides you with the following benefits:
* Complete control over the quality and reliability of your Looker reports and dashboards
* Clear view of the interactions between tables sourcing Looker reports, allowing you to effortlessly trace the data path throughout the platform
* Ability to identify and track down to the root cause any anomalies that affect your Looker reports and dashboards
**How does this feature work?**
Follow the [instructions](/integrations/looker) to create Looker configurations and allow Masthead to observe your Looker dashboards and real-time reports.
Visualize your table dependencies with data lineage to see how bad data spreads across your data tables and identify Looker reports and dashboards affected by the data anomaly.
## March 30, 2023 - in-depth Cloud cost tracking. beta
[Section titled “March 30, 2023 - in-depth Cloud cost tracking. beta”](#march-30-2023---in-depth-cloud-cost-tracking-beta)
Masthead Data introduces advanced functionality for managing your BigQuery fees. Normally, BigQuery only shows the total cost of using the cloud service, without any information on how individual pipelines and queries contribute to this fee. However, with our latest update, you can easily track the cost of each pipeline and query, giving you complete control over your pricing dynamics. Our new feature includes the following benefits:
* Full control and analytics over the cost of your data pipeline
* The ability to track the frequency, average memory/slot consumption, average cost, and total cost of your query requests for both BigQuery On-demand and Flat-rate pricing models
* Cloud cost consumption tracking for database services and tools such as Looker, Fivetran, dbt, and Dataform
* The ability to view the price and cloud resource consumption dynamics for different query requests and pipelines within a set timeframe.
**How does this feature work?**
When you onboard to Masthead, define your BigQuery pricing model.
Indicate the region where your data centers are located and see the price you pay for a terabyte of cloud resource or 100 slots of cloud compute power, depending on your commitment plan.
With our new feature, you will get a detailed overview of TB or slots consumed for running your pipeline, as well as detailed analytics on your cloud resource consumption and pricing dynamics. Here you can also check how additional database tools and services, such as dbt, contribute to your cloud cost.
With our latest feature, you’ll get a detailed breakdown of how much cloud resource you’re consuming or how many slots you’re using, and in-depth analytics on your consumption and pricing trends. You can even see how additional database tools and services, like dbt, are impacting your cloud cost.
If you want to review the pricing dynamics of individual queries, you can easily do that too. If you’re using an On-demand BigQuery pricing plan, Masthead will show you the query’s frequency and time, average memory usage in terabytes, average cost per terabyte, and total cost. For Flat-rate BigQuery subscribers, you’ll see an overview of the query’s frequency and time, the number of slots required to run it, average cost per slot, and total cost.
On top of that, you are able to check the query and its lineage of your pipeline.
With Masthead’s detailed analytics and breakdowns of your cloud resource consumption and pricing, you can stay on top of your cloud cost. By identifying which pipelines and queries are consuming the most resources and cost, you can make informed decisions and optimize your usage to pay less and save money.
## December 26, 2022 - lineage improvements
[Section titled “December 26, 2022 - lineage improvements”](#december-26-2022---lineage-improvements)
Effective data governance is critical for making informed and reliable decisions. As data engineers handle vast amounts of data at high speeds, it is crucial to have a clear understanding of the origin and transformation of the data. This is where data lineage comes in ”“ it helps to ensure that the data being used is trustworthy, accurately transformed, and stored in the correct location. By tracking the lineage of data, organizations can ensure that strategic decisions are based on high-quality data.
We are excited to announce an update to our data lineage:
* Visual enhancements to help identify data assets that have been impacted by anomalies or errors.
* Users can now view the type of every field within the data lineage, providing greater clarity and detail in the tracking of data transformation.
Masthead Lineage feature now includes visual highlighting to clearly identify tables that have been impacted by data anomalies or errors. Grey highlighting is also used to show downstream tables or views that may be affected by these errors.
In addition, we have carefully evaluated the color contrast of our Masthead UI and data lineage tools to ensure they meet accessibility standards outlined in the Web Content Accessibility Guidelines (WCAG). This includes considerations for individuals with color blindness, making our platform more inclusive for all users.
The Masthead Lineage now provides types of data in column-level lineage, allowing data engineers quickly see the types of data within each column.
This level of granularity is crucial for understanding the transformation and flow of data and its use downstream.
## November 14, 2022 - Jira integration
[Section titled “November 14, 2022 - Jira integration”](#november-14-2022---jira-integration)
Masthead takes a solid step towards more efficient issue management. From now on, you can immediately find people associated with the detected data errors and collaborate to solve data issues faster. Jira integration enables:
* More control over issue detection and solution process.
* More convenient interface for data teams responsible for data processing.
See [Jira Integration](/integrations/jira) on how this feature works.
# Support
> Masthead's friendly, knowledgeable solutions engineers are here to help.
If you need help with installation, configuration, or integration, please contact .
# Account settings
## Members
[Section titled “Members”](#members)
[Members](https://app.mastheadata.com/users?tab=Members) page provides an overview of users associated with your Masthead Data account, along with their roles and activity:
* **Role:** Indicates the permission level of each user. See permission details in the table below.
* **Last active:** Shows when each user last accessed the account.
Click **Invite** to invite new team members.
| Permissions | User | Owner |
| -------------------------------------- | ---- | ----- |
| Manage data dictionary | ✅ | ✅ |
| Manage incidents | ✅ | ✅ |
| Manage data products | ✅ | ✅ |
| Manage domains | ✅ | ✅ |
| Manage account members - View - Invite | ✅ ❌ | ✅ ✅ |
| Manage API tokens | ❌ | ✅ |
## API tokens
[Section titled “API tokens”](#api-tokens)
Manage your access tokens for the Masthead Data API. These tokens allow applications or scripts to interact with your account resources programmatically via [Terraform provider](https://registry.terraform.io/providers/masthead-data/masthead/latest).
Click **Generate new token** to create a new personal access token for your account. You can specify:
* **Token name**: A name, such as `CI/CD token`, that helps you identify the token’s purpose.
* **Expiration date**: The date, such as `Expires May 14, 2025`, that shows when the token expires. You need to generate a new token to continue access beyond this date.
You can immediately invalidate a token by clicking **Revoke access**, which is crucial for security if a compromise occurs or if you no longer need the token.
# Google Cloud discounts
For the customers who have private price negotiations with Google Cloud, Masthead takes these discounts into consideration when analyzing the costs and recommending the savings opportunities. Please share this information with Masthead to adjust your account configuration.
Where to check the discount in Billing account:
Go to [**Billing**](https://console.cloud.google.com/billing/) -> Select billing account required -> switch to **Pricing** in the left menu.
Click **View all SKUs** to show complete conditions.
Use **Column display options** button and select:
* *SKU ID*
* *Product taxonomy*
* *Discount*
* *Discount from SKU group*
* *Discount fixed date*
* *List price* `(€)`
* *Contract price* `(€)`
* *Effective discount*
Click on **Download CSV** and share it with Masthead.
Note
Masthead requires only the rows with `GBQ` in the *Product taxonomy* column.